



coval retweeted

Gradium and @covaldev are hosting an evening in Paris for people building voice agents.
Thursday, 5 Nov, 6 pm CET.
We’ll start with a short fireside chat between our research teams, followed by drinks and conversation with both teams.
RSVP: luma.com/wszf3b7v

coval retweeted

What's your way of showing you care?
In Seoul, it can sound like "Have you eaten?"
In Moscow, like "Put your hat on, it's minus twenty out."
In Tbilisi, like a toast to the guests.
We built Simba 3.5 to connect people in 48 languages, spoken like a local. Out today.
Sound on.
🤖 Made with AI
coval retweeted

$52M seed round. 15M+ users. But this is what we're most proud of yet.
Introducing Drama 3: the most emotive and controllable TTS model in the world
And yes, it's open-weight.
You can now control how even a single word should sound, change its tone, and shift your voice mid-sentence.
Uncle Roger was impressed too.
Try it here:
s.fish.audio/rqh0l8
Comment “DRAMA” within the next 48 hours for 1 month free.
If you're an enterprise your first month is on us:
s.fish.audio/qz9r0t
coval retweeted
Gradium TTS beta model is out now to define what fast means.
Less than 50ms TTFA, same quality. Most models are >100ms TTFA.
Try it now: studio.gradium.ai/?model_nam…
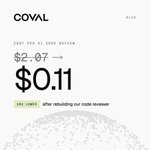
Building a code reviewer that engineers actually trust is much harder than it looks. Our engineer Dana wrote up the real story behind ours, including the parts that didn't work.
Early versions ran on frontier models and hallucinated defects that weren't there, at $2.07 per review. The fix wasn't a bigger model, but a smaller, more deliberate system: a bounded read-only agent, an ensemble of cheaper models that de-correlate better than four runs of one strong model, and a simple constraint requiring every claim to quote the exact changed line.
That last change alone took false positives from 38% down to 98% verified accuracy.
The result: a reviewer that catches real defects at eleven cents per review in production.
Full breakdown from Dana here: coval.ai/blog/how-we-built-o…

coval retweeted
The evaluation metrics for Text-to-Speech by @covaldev include leading silence.
This led us to train a new model.
Now our latency is down to 214ms, giving developers a much better experience.
Read more: gradium.ai/blog/coval-percei…

Most TTS latency benchmarks stop the clock the moment any audio arrives, silent or not. We changed ours to count that silence. The day the update shipped, @gradiumai reported latency moved from 172 ms to 430 ms. No model change or infrastructure change. Their audio was arriving fast, it just opened with up to 655 ms of dead air before anything audible.
Gradium used that signal to retrain their default model. Now they're hitting 214 ms, about 170 ms faster.
If you're picking a TTS provider on a latency number, make sure to check what that number is actually measuring.
Read more in our latest blog post with Gradium: coval.ai/blog/time-to-first-…

coval retweeted

We're proud to define the quality-latency Pareto frontier for STT in Coval's benchmarks.
Voice AI is an inference problem, and teams need benchmarks that measure inference to know what their users will actually feel.
Proud to partner with @covaldev for an open, reproducible methodology.
Read more here: baseten.co/blog/baseten-lead…

coval retweeted

Introducing ExtractBench, the most comprehensive benchmark for information extraction from complex enterprise documents.
The latest models are pushing the frontier of coding and knowledge work, but surprisingly they still struggle on complex doc extraction tasks in production. A well-tuned extractor must parse multi-page filings without dropping rows, emit exact spatial citations for auditability, and handle messy scans. Also they must do all of this at a viable per-page cost so that you can scale this to millions of docs in production (you can’t be paying upwards of $1 in tokens per page!)
Existing extraction benchmarks fall short: they are not large/diverse enough in document domain (finance, energy, gov, auto), elements (long records, scans, grounding), and schemas.
So our applied research team built ExtractBench.
We evaluated 14 systems: frontier VLMs, coding agents, and specialized extraction APIs, against 370 enterprise documents: 4,869 pages, 67 document types.
Our biggest finding 🧪: Short documents mask critical system flaws. On files past 50 pages, commercial VLMs collapse below 35% recall due to silent list truncation. They hold high precision, but lose output attention and drop most of the table rows.
ExtractBench evaluates value accuracy, long-record completeness, spatial grounding, and per-page cost with zero LLM judges. It is 100% deterministic and reproducible.
In tandem with ExtractBench, we’re also introducing 𝗔𝗴𝗲𝗻𝘁𝗶𝗰 𝗣𝗹𝘂𝘀, a new Extract tier in LlamaParse that debuts at #1 on the leaderboard: 95.6% value accuracy, at less than a third the cost of the closest peer.
Explore the findings, download the dataset, or run the harness:
Blog:
llamaindex.ai/blog/introduci…
GitHub: github.com/run-llama/Extract…
HuggingFace: huggingface.co/datasets/llam…
We will be actively evolving both our extraction benchmark as well as our extraction harness over time.
If you check out either ExtractBench or LlamaParse, let us know your feedback!

Introducing 𝗘𝘅𝘁𝗿𝗮𝗰𝘁𝗕𝗲𝗻𝗰𝗵: the most comprehensive benchmark for information extraction from complex enterprise documents. Our applied research team tested:
14 systems — frontier VLMs, coding agents, extraction APIs — on 370 enterprise docs, 4,869 pages, 67 doc types. Zero LLM judges, fully deterministic.
Biggest finding: past 50 pages, commercial VLMs collapse below 35% recall. Precision stays high, but they silently drop most of the table rows.
What is your extraction agent missing? Run ExtractBench to see today.
Blog:
llamaindex.ai/blog/introduci…
GitHub: github.com/run-llama/Extract…
HuggingFace: huggingface.co/datasets/llam…
coval retweeted

I’m excited to announce @covaldev raised a $28M Series A, led by @NorwestVP with participation from @Base10Partners, @twilio Ventures and @ycombinator, among others.
I started Coval with the belief that the simulation and evaluation approaches that made autonomous vehicles a reality could unlock the same for voice AI. That parallel has only gotten sharper as enterprises deploy autonomous conversational agents at scale.
Voice and chat are the new interface in the AI era. Talking is the most natural way to interact with complex autonomous systems. The same way web and mobile transformed every enterprise, every company will have a voice agent as the front door to their product. This platform shift is happening now.
From Y Combinator to working with companies like @DeepgramAI, @perplexity_ai , and @Zoom, it's been a wild ride. We watched voice AI go from an emerging modality to every Fortune 500 enterprise building a conversational interface.
Autonomous agents are the future. But you can't ship and hope for the best when agents are taking on real work. The stakes are too high.
Coval will be what enables us to actually trust those agents. The platform to help teams reliably scale voice and chat agents.
We wouldn’t be here without Coval’s founding engineers @rheacoval and Kobi Hudson. Rhea took a chance on Coval before we had a single customer, a line of code, or an office that wasn't my couch. Kobi left @Waymo after 10 years building foundational simulation systems to help us build the frontier of voice simulation.
To the full Coval team - you all are insane engineers and builders who inspire me every day. Rob Young Alejandra Vergara Henry Finkelstein Callum Reid Dakota Mallen Dana Dzik Mallory McLoughlin Christopher Kuester Jake Levi Brooke Hartley Kappi Patterson
To all our investors - @NorwestVP, @Base10Partners Partners, @twilio Ventures, @ycombinator, @alumniventures, Swift Ventures, Fortitude VC and so many more. You are what made Coval possible.
To @koh_terai who brought my video vision to life.
And last but certainly not least, thank you to everyone who's been building with us.
We're just getting started.
coval retweeted

Flux Multilingual is live.
Real-time conversational speech-to-text for voice agents in 10 languages, with monolingual-grade accuracy, turn detection, and code-switching.
Deploy once and launch globally.
Learn more → deepgram.com/learn/introduci…
There’s a persistent belief in startups that you have to choose between moving fast and building stable systems.
Early on, it feels true. Infrastructure looks like overhead. Monitoring, evals, rollback logic, routing discipline — none of it directly ships a new feature. When you’re racing to find product-market fit, stability can feel like something you earn later.
But in systems like voice AI, the tradeoff turns out to be mostly imaginary.
What actually slows teams down isn’t infrastructure. It’s the absence of it. It’s spending days debugging a regression because no one captured per-turn latency. It’s pushing a prompt update and not knowing whether it improved resolution or just shifted failures somewhere else. It’s being afraid to deploy because you can’t predict the blast radius.
When you build observability and structured evaluation early, releases get less dramatic. You know what changed. You know what broke. You can attribute performance movement to a specific component instead of debating guesses in Slack. Rollbacks become procedural instead of emotional.
Speed without feedback is chaotic. Stability without iteration is stagnation. The teams that compound fastest figure out how to build both at the same time — tight feedback loops, clear instrumentation, and the confidence to ship because measurement is built in.
Over time, the supposed tradeoff disappears.
What remains is a system that improves quickly precisely because it’s stable enough to trust.
🎉 Exciting News! Please join us in welcoming Rob Young to the Coval team!
Before joining Coval, Rob designed products at Google and Apple, and founded and led the product design studio OM. He brings a wealth of experience crafting elegant, user-centered experiences at some of the world's most innovative companies.
Outside of work, you'll find Rob spending time with his family, skateboarding, doing yoga, and painting.
Welcome to the team, Rob! 🚀

🧵 This week in conversational AI:
🎤 @OpenAI Realtime takes a big step forward — sub-500ms latency, sharper function calling, non-verbal cue detection, seamless language switching, and SIP (telephony) support. Already benchmarked at coval.ai, and the gains on instruction following are a real unlock for production-grade voice agents.
🧪 @cartesia demos custom evals for voice agents — defining, validating, and reusing LLM-powered metrics on real calls. A strong signal that observability is becoming core infrastructure for scaled agents.
🔗 @DeepgramAI × Cloudflare : Deepgram’s STT + TTS now run directly on Cloudflare’s global edge. Low-latency voice agents deployed serverlessly — making conversational AI faster and more accessible worldwide.
💡 Together AI named an IA40 Winner in the “Enabler” category — powering over 800K developers building AI-native apps. Great to see Cartesia , Arcee AI , and ElevenLabs also recognized, showing how fast the real-time voice ecosystem is maturing.
📣 Coming up (Sept 3, SF): 𝗩𝗼𝗶𝗰𝗲 𝗔𝗜 𝗣𝗿𝗼𝗻𝘂𝗻𝗰𝗶𝗮𝘁𝗶𝗼𝗻 𝗖𝗵𝗮𝗹𝗹𝗲𝗻𝗴𝗲𝘀, hosted by @Covaldev , @rimelabs, and @ConverseNowAI. We’ll dig into why models stumble on words like Chipotle, tradeoffs between emotional range and consistency, scaling TTS in production, and war stories from the trenches. If you’re building voice AI, this is for you.
P.S: We'll be sharing more behind-the-scenes of our Coval Benchmarks 2.0, with a special focus on TTS! Make sure to sign up for the event! luma.com/dd7lgjbc
What did I miss?

🎉 Exciting News! Please join us in welcoming Loren Phillips to the Coval team!
Before joining Coval, Loren worked on autonomous vehicle safety validation at Zoox, Amazon’s self-driving subsidiary. He also brings a diverse research background spanning nanophotonics, soft robotics, and medical devices.
When he’s not massively advancing how AI agents are tested and deployed, Loren spends his free time road cycling, running his Etsy store of 3D-printed art, and developing Voice AI applications — from cloning sites to dating platforms.
Welcome to the team, Loren! 🚀

coval retweeted

🎙️ Testing non-deterministic AI requires a new approach. Forget exact outputs; it's about probabilistic success. @bnicholehopkins of @covaldev breaks down the shift on the latest Generationship episode. Tune in! 🎧
hubs.ly/Q03kj05Z0

coval retweeted

don't miss that OAI also published a prompting guide WITH RECEIPTS for GPT 4.1 specifically for those building agents... with a new recommendation for:
- telling the model to be persistent (+20%)
- dont self-inject/parse toolcalls (+2%)
- prompted planning (+4%)
- JSON BAD - use XML or arxiv 2406.13121 (GDM format)
- put instructions + user query at TOP -and- BOTTOM - bottom-only is VERY BAD
- no evidence that ALL CAPS or Bribes or Tips or threats to grandma work


🎉 Exciting News! Please join us in welcoming Kobi Hudson to the Coval team!
Prior to Coval, Kobi spent 8 years at Waymo working alongside our own Brooke, where he played a pivotal role in building Waymo's early simulation infrastructure - some of the foundational systems powering autonomous vehicle testing today. Now, he’s bringing that simulation superpower to Coval, helping us build the future of how AI agents are tested, evaluated, and deployed.
When he’s not leveling up infrastructure, you’ll find him at the beach with his wife and dogs or hitting up skateparks around the Bay 🛹
Welcome to the team, Kobi! 🚀

coval retweeted

very detailed and fair evals and impressions on the new STT+TTS models. thx @covaldev

🎙 OpenAI’s dropped new voice AI Models- get Coval's scoop and see the benchmark results 🫢
@OpenAI just dropped a new text-to-speech model, We’ve been testing gpt-4o-mini-tts and the prosody, pronunciation, and controllability are next-level.
💭 Prosody that feels real: The intonation, rhythm, and expressiveness are way ahead of previous versions.
🔢 Impressive number pronunciation: No more awkward digit reading—finally, a TTS that understands numbers in context.
🧑💻 Tags for fine-tuned control: You can tweak tone, style, and delivery for different use cases.
📊 Higher latency compared to other providers, but better pronunciation: There’s a tradeoff, but for many applications, the quality boost is worth it.
🚀 They also launched
- New transcription models that are way better than Whisper
- Better noise cancellation for transcription
- Voice agent SDK & better tooling
- Semantic voice activity detection
At @covaldev, we’re diving deep into testing these models for our customers! The potential for conversational AI is massive.
If you’re working with voice AI, these new models deserve your attention. What’s your take on the latest OpenAI TTS updates? Let’s discuss! ⬇
coval retweeted

The folks at @covaldev did a deep dive with our audio models, some great examples of pronunciation with difficult words
🎙 OpenAI’s dropped new voice AI Models- get Coval's scoop and see the benchmark results 🫢
@OpenAI just dropped a new text-to-speech model, We’ve been testing gpt-4o-mini-tts and the prosody, pronunciation, and controllability are next-level.
💭 Prosody that feels real: The intonation, rhythm, and expressiveness are way ahead of previous versions.
🔢 Impressive number pronunciation: No more awkward digit reading—finally, a TTS that understands numbers in context.
🧑💻 Tags for fine-tuned control: You can tweak tone, style, and delivery for different use cases.
📊 Higher latency compared to other providers, but better pronunciation: There’s a tradeoff, but for many applications, the quality boost is worth it.
🚀 They also launched
- New transcription models that are way better than Whisper
- Better noise cancellation for transcription
- Voice agent SDK & better tooling
- Semantic voice activity detection
At @covaldev, we’re diving deep into testing these models for our customers! The potential for conversational AI is massive.
If you’re working with voice AI, these new models deserve your attention. What’s your take on the latest OpenAI TTS updates? Let’s discuss! ⬇