

Founder, AI Scientist, CEO of webAI™
Austin, TX
Joined March 2020
- Tweets773
- Following2.7K
- Followers12.4K
- Likes1.4K




Pinned Tweet
Modest intelligence is arriving faster than most people realize.
Today, we're open-sourcing TwIL-8B.
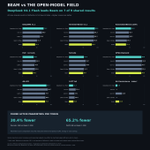
Just 8.8 billion parameters, yet approaching frontier-model scores on several difficult benchmarks:
• 93% of frontier performance on coding
• 92% on instruction following
• 90% on contest mathematics
All from a model small enough to run on your own hardware.
But the benchmarks aren't the most important part of this announcement.
For years, the AI industry has focused on building the most capable model, regardless of the cost required to run it.
I believe that equation is changing.
The next era of AI will be defined by the cost of completing work. Not simply the intelligence of the model, but how efficiently that intelligence can accomplish the task.
If a model with 8 billion parameters can reliably complete the same work as one with hundreds of billions, why pay for the larger model?
As smaller models become more capable, intelligence becomes something we can distribute, specialize, and run across the hardware we already own.
That's the future we're building at @thewebAI
TwIL-8B is available today. Open weights.
And this is just the first of several announcements we're making today.
HF Link: huggingface.co/webAI-Officia…
Thank you all for the incredible support. TwiL-8B hit #24 of 433,863 text generation models on Hugging Face in its first 7 hours.
We have more to share, and it’s worth waiting for. Tomorrow morning we’re releasing one more model, our best yet, and opening general access to webAI.
See you in the morning.

Release 2 of 4 today: webAI Air.
73% smaller. Nearly 99% of measured benchmark performance retained.
Air is our method for compressing AI models so more capable intelligence can run on everyday devices.
Our first release applies Air to Google’s Gemma 4 26B A4B. Compared with the original model:
* 73% smaller model file: 50.5 GB → 13.47 GB.
* 98.7% of the average benchmark score retained: 78.3 versus 79.3 across six benchmarks.
* 2.1× the generation speed: 60.6 versus 28.7 tokens per second in our DGX Spark tests.
Compared with Google’s own 4-bit version, Air is also 6.7% smaller, with 61% lower divergence from the original model’s predictions in our evaluation.
Useful intelligence is becoming smaller, faster, and easier to put to work. That changes the economics of AI and puts more of it on hardware people already own.
Make cloud AI optional.
Two more releases coming today.

@thewebAI's Intelligence Lab is open sourcing Gemma 26b 4a Air
2.6× closer to full precision
Significantly more faithful to the original model than Google's official 4-bit release (KL divergence: 0.068 vs. 0.176).
Nearly 4× smaller
Just 13.5 GB vs. 50.5 GB, with the full 128K context fitting in 16 GB of memory.
Almost no loss in intelligence
Scores 78.3 vs. 79.3 across 6 benchmarks, retaining 99.4% of original performance on knowledge, math, and coding.
Matches the original on real-world tasks
Nearly identical wIL scores (Track A: 0.502 vs. 0.508; Track B: 0.812 vs. 0.812).
HF: lnkd.in/gJK6xR9B


David Stout retweeted

The cost of completing a task matters more than the raw intelligence of the model running it.
That’s the thesis behind TwIL-8B, our new 8.8B reasoning model. Open weights. Runs on hardware you already own.
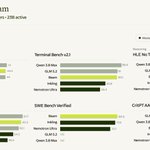
Against Qwen3.5-9B, it opens a 16-point lead on LiveCodeBench (81.6 vs 65.6) and tops MATH-500 (98.2 vs 96.6). Against Gemma 4 31B, 4x the size, it still wins on MATH-500 (98.2 vs 87.9) and AIME 2025 (88.3 vs 87.1).
Tiny by frontier standards. Does the reasoning work anyway.
Download the model on @huggingface: huggingface.co/webAI-Officia…
its almost like ai in the cloud does not work ... ai will move toward user owned hardware.
@thewebAI has major announcements this week.

Whoever signed compute commitments is going to have a rough one, the amount of providers asking if we need compute for training has exponentially jumped the past few weeks. At a fraction of the price that is being advertised.
Clearly there is a capacity surge.
Guppy level death
nitter.cf/hotaisle/status/211690…


I think Elon has one of best compute infrastructure build outs in the world, and the unit economics are still trailing, hybrid will make the most sense.

Your car sits parked most of the day. That doesn’t mean a taxi company should own it.
The same applies to AI.
Ownership buys autonomy, availability, and control.
Calling that “inefficient” is convenient when your business depends on selling access.

sam: local inference is a terrible allocation of scarce resources
“a lot of people want local inference, and somehow they assume that the problem is solved now because we have open-source models, we're going to be able to run them on our computers, and so we're not going to need all the stuff in the data centre
but from a global allocation perspective, actually it's quite terrible to have everybody, like, have a bunch of the world's limited supply of DRAM sitting in their own computer and being used five percent of the time
you want maximum utilisation in the cloud if you're trying to deal with this very supply-constrained environment
somehow many people's intuition is the opposite of that”


