

PhD student @WisconsinCS / Intern @Snorkelai / RL Resident Prime Intellect
Joined January 2021
- Tweets355
- Following214
- Followers900
- Likes890


Pinned Tweet
Agents will soon replace humans as the main users and designers of libraries.
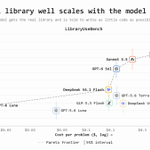
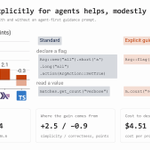
A good library will let future agents write correct programs with less code.
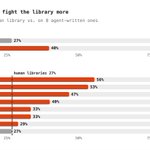
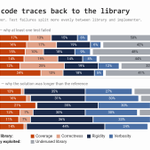
Introducing LibraryDesignBench: one agent designs a library, and other agents write programs with it.

Gabe Orlanski retweeted
Our RL Residency gives independent researchers compute grants and mentorship to build open evals and training environments for overlooked problems.
In 2026, residents shipped projects spanning robot control, medical imaging, gameplay, and GPU kernels. Some highlights:

Thanks for having me! Was a great discussion on what the current state is and what the future holds!

Emergent Behaviors with Gabe Orlanski, creator of SlopCodeBench: 🦄 AI That Works #81 nitter.cf/i/broadcasts/2WXPoPRqB…

A few weeks ago, @dexhorthy released a great blog on how frontier agents performed on SlopCodeBench.
Now, slop is moving up the stack and destroying your codebase with duplicate code.

You can read the full blog here: gabeorlanski.github.io/posts…
Or go to the benchmark sites to learn more:
SCB: scbench.ai
LDB: ldbench.com

1
16
508
This work was supported by the @primeintellect RL Residency and by @snorkelai Open Benchmark Grants.
Thanks again to @dexhorthy for running SCB to get these results and to @omouamoua for the feedback.
11
428
Gabe Orlanski retweeted

a year ago at @aidotengineer Code Summit I spoke about Research Plan Implement, how to apply context engineering to your coding agents, and why every concept in AI is doomed to suffer "semantic diffusion". That talk has over 600k views and changed the way engineers everywhere think about building with AI
On thursday next week at 5pm, I'll be doing the ultimate mash-up talk: "Twelve Factor Factories: Design Patterns for Agentic Engineering"
should be a fun one, see y'all there 🙂

Gabe Orlanski retweeted

How much of your training compute should go to rewriting your data as you scale pretraining?
We trained a *22B* hero run at 33× our fit range and it ended up being within 1.1% of the pre-registered loss forecast!
🧵Thread from my amazing co-lead @AhmedSQRD 🧵
👇👇👇

Was thinking about this for a while today. And the NS moment for coding that come to mind for me are:
Final METR time horizon update
Rewriting Bun in rust
Huggingface incident (ik not exactly coding)

i'm not exactly sure how to describe what openai just did to math, but whatever that was, that moment is gonna hit coding in 6-18 months, and i have no understanding of what that actually looks like and what it means
7
655
Gabe Orlanski retweeted

Today, we’re expanding @SnorkelAI’s Open Benchmarks Grants by 10x to a $30M commitment:
- Funding a more diverse, robust, and continuously-updated ecosystem of open benchmarks
- Launching the Open Benchmarks Red Team to continually test and strengthen them
- Introducing the Snorkel Research Fellowship to support independent contributors developing new evaluation methods
Since our launch earlier this year, we’ve been humbled to partner with the teams behind Terminal-Bench, TB-Science, ARC-AGI-3, OSWorld 2.0, Agents’ Last Exam, Continual Learning Bench, Senior SWE-Bench, SlopCodeBench, and more. Alongside these teams, we’ve helped design evaluation methodologies, develop task construction pipelines, and scale quality control. OBG-funded benchmarks have appeared on the latest model cards from every major frontier lab; have helped to index and measure frontier progress and alignment; and have contributed to guiding the frontier of AI development.
Benchmarks have always been guideposts for—and drivers of— AI progress: setting a metric and then “hillclimbing” against it is the core of how AI works! But when benchmarks fall behind frontier capabilities, our ability to evaluate and align these systems does as well. They become too simple, static, or correlated, and the risk of “benchmaxxing” increases.
We need more diverse, robust, and continuously-updated benchmarks, developed by a broader ecosystem of researchers and domain leaders.
We’re incredibly excited to accelerate frontier evaluation with Open Benchmarks Grants— raising the ambition and investment in robust, open, and independent measurement. Read our full announcement and apply here: benchmarks.snorkel.ai/fronti…

Gabe Orlanski retweeted
I’m at #COLM2026! If you’re excited about the science of LLMs or scaling laws, feel free to reach out for a time to chat!
Tomorrow at 4:30 PM, I’ll be presenting our work showing that joint pretraining and test-time scaling makes overtraining compute optimal. @COLM_conf 🦙


I will be in SF for #COLM2026 on Tue & Wed. Then, on Thursday, I'll present SlopCodeBench at @SnorkelAI's Frontier Data Summit.
Always happy to chat about evaluations, agents for code, or just general long-horizon agentic tasks! (Also: on the job market this spring!)
This was an exciting project! It would not be possible without my amazing collaborators: @a1zhang @atrost3122 @vincentsunnchen @fredsala @awsTO @lschmidt3
This work was generously supported by @DARPA, @NSF, @PrimeIntellect, and through @SnorkelAI 's Open Benchmark Grant.
Check out the leaderboard at ldbench.com!
Paper: arxiv.org/abs/2609.36730
Repo: github.com/SprocketLab/libra…
HF Papers: huggingface.co/papers/2609.3…
Blog: gabeorlanski.github.io/posts…