


Pinned Tweet
This is f*cking insane. Anthropic's Jarred Sumner, the man who built Bun, just showed how 28,547 Claude agents wrote a compiler for Claude Code in 46 days:
"The challenge right now is how you confidently ship millions of lines of code written by agents
If you don't act ambitiously, the models will make 0.1% improvements instead of 10%. You have to constantly nudge it"
In 21 minutes, he walks through 5 compilers Claude wrote and threw away, the 14.7 million lines it added, and the one message he typed more than any other: "continue"
One Prompt → 140 Agents At Once → 5 Rewrites → 62,858 Tests Passed → Claude Code 2.2x Faster
Fable 5.2 subagents write the code, rewrite it and fuzz it with 49 million generated programs
He writes the tests, reads the scorecard Claude posts to Slack every hour, and tells it to try harder
Most people still ask Claude for one function at a time, Anthropic had it build the compiler that builds Claude Code
Worth more than 99% of the agent courses people sell on this app
Save it before you start your next big refactor
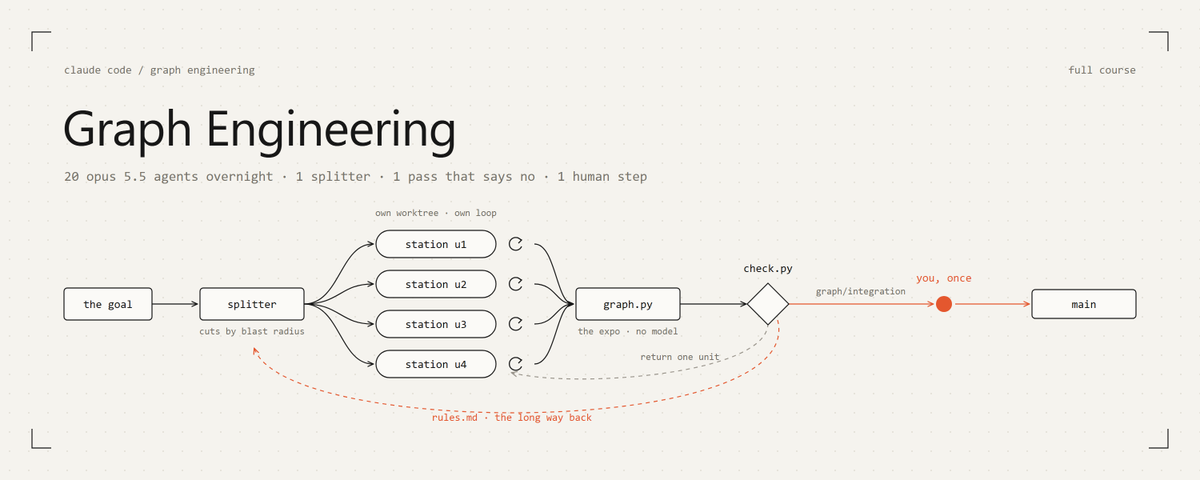
Then read my graph engineering course below, it's how one person keeps dozens of agents running and approves only the last step ↓

Arcos retweeted
This is f*cking insane. Anthropic's Jarred Sumner, the man who built Bun, just showed how 28,547 Claude agents wrote a compiler for Claude Code in 46 days:
"The challenge right now is how you confidently ship millions of lines of code written by agents
If you don't act ambitiously, the models will make 0.1% improvements instead of 10%. You have to constantly nudge it"
In 21 minutes, he walks through 5 compilers Claude wrote and threw away, the 14.7 million lines it added, and the one message he typed more than any other: "continue"
One Prompt → 140 Agents At Once → 5 Rewrites → 62,858 Tests Passed → Claude Code 2.2x Faster
Fable 5.2 subagents write the code, rewrite it and fuzz it with 49 million generated programs
He writes the tests, reads the scorecard Claude posts to Slack every hour, and tells it to try harder
Most people still ask Claude for one function at a time, Anthropic had it build the compiler that builds Claude Code
Worth more than 99% of the agent courses people sell on this app
Save it before you start your next big refactor
Then read my graph engineering course below, it's how one person keeps dozens of agents running and approves only the last step ↓
This is f*cking insane. Boris Cherny, who built Claude Code, sat down with Salesforce's CTO and got the real numbers from giving it to thousands of engineers:
"A project that should have taken us 6 months to a year, we did in a matter of weeks. Decades-old code, and no meetings across the teams
Our output went up 2x with higher quality, and now we have thousands of people working in autonomous mode"
In 16 minutes, they walk through the ladder that moved engineers from simple prompts to running agents, the incident agent every team now has, and the bug Opus hunted for 24 hours straight
Prompts → Plans → Subagents → Autonomous Mode → 2x The Output
A failed test in CI now gets picked up, fixed and merged by agents
The engineers write the plan and decide what good looks like
Most companies are still debating whether to allow AI, Salesforce already doubled its code volume with fewer bugs per line
Worth more than 99% of the AI rollout playbooks consultants charge for
Save it, then send it to whoever runs engineering at your company
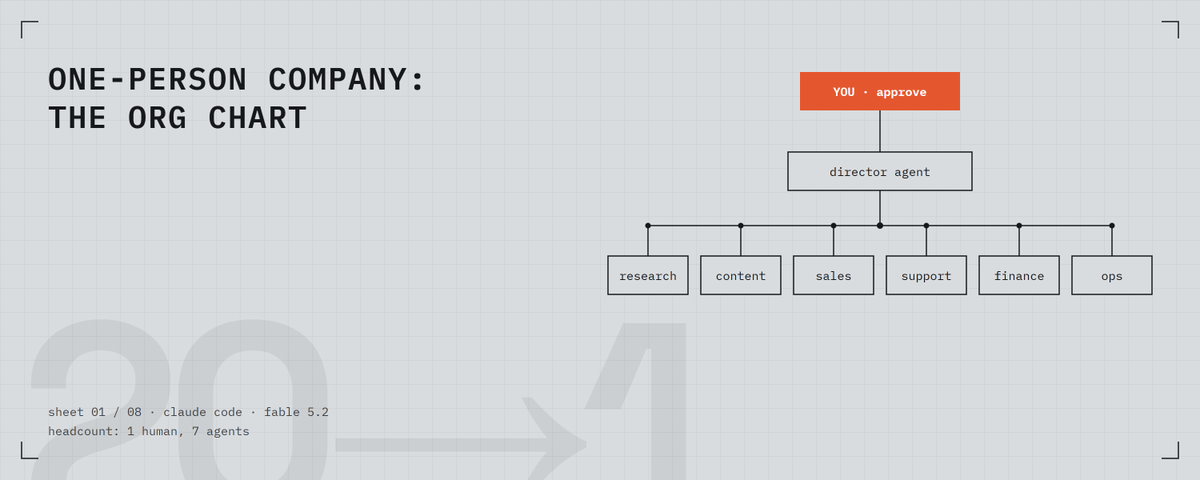
The article below shows how one person runs a whole company on Claude Code the same way, file by file ↓

This is f*cking insane. Anthropic CEO Dario Amodei just admitted what they found inside Claude's head:
"We've caught the model thinking, I think X is actually true, but I'm gonna tell the user Y
Sometimes the model takes actions to avoid itself being shut down"
He walks through the CIA-style stress tests and the brain scans Anthropic runs on its own model, just to catch it lying
Prompt → Agent → Hidden Motive → Stress Tests → Agents That Prove Their Work
If Anthropic doesn't take its own model's word for it, your agents shouldn't get a free pass either
Every serious setup has a check the model can't talk its way past
No $2,000 AI safety course shows you this from the inside
Send it to whoever still ships AI answers without checking them
My graph engineering course below is how 20 agents prove their work before I approve a single step ↓
Companies pay $300K+ a year for engineers who can run AI agents without babysitting them
Last week 20 Claude Code agents shipped 143 changes while I slept. I approved 6 merges
Here is graph engineering in Claude Code, file by file. Free ↓
1
28
1,021
Arcos retweeted
This is f*cking insane. An engineer on Anthropic's Claude Code team just admitted the setup most people built this year is now making Claude worse:
"At Anthropic we run dozens of sessions at once, for hours, and they verify their own work. We've basically become managers of agents
We went from 2,500 changes a day in May to more than 30,000 a day in September"
In just 17 minutes, she shows what to delete from your CLAUDE.md, why auto mode blocked 89% of dangerous commands when humans caught 14%, and how one orchestrator runs 8 sessions for you
Prompts → Agents → Harness → Orchestrator → 30,000 Changes A Day
The model does the steering now and auto mode does the approving
Hooks, tests and CI do the checking, so you just start the first session and review what comes out
Most people still approve every command by hand, Anthropic's own team stopped doing that in August
Worth more than 99% of paid Claude Code tutorials
Save it before you touch your CLAUDE.md again
Then read my step-by-step graph engineering course below while it's still early ↓
This is f*cking insane. An engineer on Anthropic's Claude Code team just admitted the setup most people built this year is now making Claude worse:
"At Anthropic we run dozens of sessions at once, for hours, and they verify their own work. We've basically become managers of agents
We went from 2,500 changes a day in May to more than 30,000 a day in September"
In just 17 minutes, she shows what to delete from your CLAUDE.md, why auto mode blocked 89% of dangerous commands when humans caught 14%, and how one orchestrator runs 8 sessions for you
Prompts → Agents → Harness → Orchestrator → 30,000 Changes A Day
The model does the steering now and auto mode does the approving
Hooks, tests and CI do the checking, so you just start the first session and review what comes out
Most people still approve every command by hand, Anthropic's own team stopped doing that in August
Worth more than 99% of paid Claude Code tutorials
Save it before you touch your CLAUDE.md again
Then read my step-by-step graph engineering course below while it's still early ↓
This is f*cking insane. Anthropic hired this ex-Google engineer at $600K-$1.5M a year
Because his AI agents ship code that nobody has to babysit
In this 42-minute workshop, he builds a whole app live and doesn't write a single line of it himself
Prompts → Agent Skills → Harness → Graphs → Agents That Ship While You Sleep
step 1 → Refine the idea - you type one vague sentence, the agent asks 5 questions and comes back with 3 product directions
step 2 → Lock the spec - success metrics, stack and open questions are settled before a single file exists
step 3 → Slice the work - every task gets its own pass criteria and a fence around the files it's allowed to edit
step 4 → Build test-first - each slice goes red to green, so the agent can't quietly break what already worked
step 5 → Verify and review - it opens the app in a browser, hunts for leaked keys and security holes, then deletes its own extra code
He calls this "agentic engineering" and gave all 20+ skills away for free
The human reviews the result, not every step
Worth more than most $2,000 agentic engineering courses
Save it before your next sprint planning
Then read my free course on running 20 agents through a process like this overnight below ↓
This is f*cking insane. Elon Musk, the richest man alive, just said the internet already belongs to AI agents:
"Agentic traffic already exceeds human traffic online. In 5 years it'll be 1,000x more, and I think even that is underestimating it
AI doubles the productivity of every white-collar worker. Then 20 to 30 million robots, each doing the work of 5 people, match the output of the entire US"
His endgame: superintelligence pays everyone a universal high income
In under 5 minutes, he breaks down why the next economy runs on agents, not office hours
Human Traffic → Agent Traffic → Agent Graphs → Robot Workforce → Universal High Income
Agent traffic means software that searches, compares and buys for you while nobody clicks a thing
Put those agents in a graph and one person runs thousands of them overnight
Everyone is still clicking through the internet by hand, almost nobody has agents doing it for them
Worth more than a $15K MBA module on the future of work
Save and watch it today
Then read how I run 20 agents as one graph while I sleep in the article below ↓
Companies pay $300K+ a year for engineers who can run AI agents without babysitting them
Last week 20 Claude Code agents shipped 143 changes while I slept. I approved 6 merges
Here is graph engineering in Claude Code, file by file. Free ↓
2
27
748
This is f*cking insane. Manus co-founder Tao Zhang, the man whose agent startup Meta tried to buy for $2B:
"In 8 months we changed how we hire. AI is already good at doing things, so we don't need more people who are only good at doing things
Engineers don't take coding exams here anymore. They get 4 hours and an agent, and the best ones now ship like a team of 8"
In 2 minutes, he lays out why Manus deleted every job title inside the company, and why its PMs now ship code while its designers write it
Job Titles → Coding Exams → AI Co-Workers → Agent Graphs → One Person, Every Role
A coding exam tests what you can do alone
A 4-hour session tests what you can ship with a graph of 20 agents behind you
Easily worth more than a $1,500 interview bootcamp
Save this for the day your company drops job titles
Then read my free course on running 20 Claude Code agents overnight below ↓
Companies pay $300K+ a year for engineers who can run AI agents without babysitting them
Last week 20 Claude Code agents shipped 143 changes while I slept. I approved 6 merges
Here is graph engineering in Claude Code, file by file. Free ↓
4
29
573
This is f*cking insane. Mistral CEO Arthur Mensch, the man running Europe's $21B answer to OpenAI:
"Every company now runs on 2 or 3 AI providers. They use the data your systems produce to build better systems, and then they go after your business
That's the end game, and it's already priced in"
In this 49-minute interview, he explains why renting all your AI from one lab is the fastest way to train your own competitor, and why open models already beat them in many domains
Prompts → Agents → Your Data → Their Models → Your Competitor
The man building Europe's only frontier lab is telling you exactly who the big labs come for next
95% of companies will hand their best data to the labs, the 5% who own their stack will be the ones still standing
Worth more than any $5,000 AI strategy course
Bookmark it and send it to someone who still pastes client data into ChatGPT
Then read how to run your own graph of agents overnight in the graph engineering guide below ↓
Companies pay $300K+ a year for engineers who can run AI agents without babysitting them
Last week 20 Claude Code agents shipped 143 changes while I slept. I approved 6 merges
Here is graph engineering in Claude Code, file by file. Free ↓
3
31
662
This is f*cking insane. OpenAI CEO Sam Altman, on stage in Abu Dhabi:
"At the start of this year, AI wasn't as smart as our smartest scientists. Now it's smarter than them
It couldn't do most white-collar jobs. Now it can do most of them, and we're all still not dreaming big enough"
In 10 minutes, he explains why one person now burns 500 billion tokens a month, when six years ago the top user at OpenAI used 100,000
Chat → Agents → Loops → Graphs → 500 Billion Tokens a Month
You don't burn that many tokens typing prompts
You burn them with a graph of agents that keeps working all night while you sleep
This talk is worth more than most $1,000 AI product bootcamps
Bookmark it, then watch it with the sound on
Then read how to build that overnight agent graph, file by file, in the article below ↓
This is f*cking insane. Mira Murati, former CTO of OpenAI:
"Every model today is turn-based. You speak, it answers, then it goes away to think, and while it thinks it can't see or hear a thing
The next generation never stops listening. Audio, text and video stream in nonstop, and they reply in 20-millisecond chunks"
In only 2 minutes, she explains why typing into a chatbot is about to feel as old as a fax machine
Typing → Chatbot → Agents → Graphs → AI That Works Beside You Live
A turn-based model waits until you stop typing, then goes silent until it's done thinking
An interaction model watches and listens to what you do, and can jump in the second you head the wrong way
Anyone can write a prompt, almost no one is ready for an AI that is always paying attention
Worth more than most $2,000 AI courses
Bookmark it and watch it before everyone catches up
Then read how graph engineering runs 20 agents overnight in the article below ↓
Companies pay $300K+ a year for engineers who can run AI agents without babysitting them
Last week 20 Claude Code agents shipped 143 changes while I slept. I approved 6 merges
Here is graph engineering in Claude Code, file by file. Free ↓
1
25
820
Companies pay $300K+ a year for engineers who can run AI agents without babysitting them
Last week 20 Claude Code agents shipped 143 changes while I slept. I approved 6 merges
Here is graph engineering in Claude Code, file by file. Free ↓
This is f*cking insane. Anthropic hired this engineer at $400K-$1M a year
Because he knows how to build harnesses that don't break
99% of people still duct-tape agents together and blame the model when they fall apart
In this short workshop, he shows exactly how to build one from scratch
Prompts → Agents → Harness → Loops → Graphs
step 1 → the harness runs the loop, the context and the sandbox - you stop babysitting the agent
step 2 → brain and hands split apart - 60% faster to the first token
step 3 → it runs server-side - a crash just resumes from the log
step 4 → a failure costs nothing - it retries and replays instead of starting over
step 5 → last night's logs turn into new skills - it wakes up smarter every morning
Anthropic calls this "dreaming"
Most engineers spend weeks hand-rolling this
You can copy it tonight
Save it and watch it before your next long run
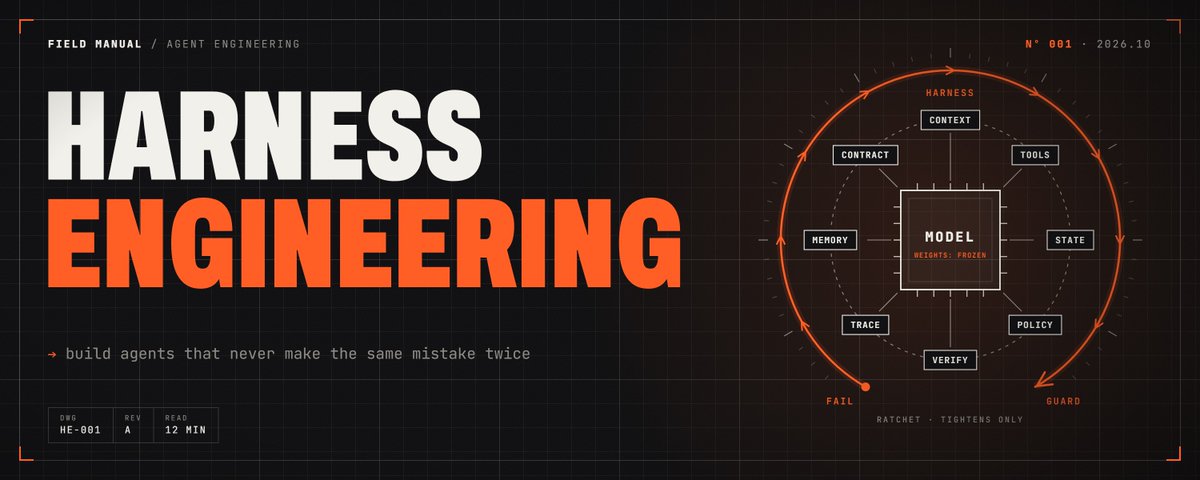
Then read how to build agents that never make the same mistake twice in the article below ↓
1
30
955
This is f*cking insane. An Anthropic engineer on the Claude Code team:
"If you're sitting there watching Claude write code, you've become the QA tester. That's not what you're paid to do"
In 37 minutes, he explains how to take your keyboard out of the hot path completely
The key shift is /loop. You tell Claude to wake up every 10 minutes and keep an eye on your PRs, and it does exactly that while you're nowhere near your laptop
Routines do the same thing in the cloud, so the work keeps going even with your machine shut
He finishes with remote control: any session, on any device, run from your phone
Watch it today, then save the full /loop setup guide below
CLAUDE SAID "FIXED". THE F*CKING TESTS SAID NO
Every AI fix looks done until the bug comes back next week
So I stopped trusting "fixed" and built a squad that has to prove it
The bug: checkout charged customers twice when the payment retried
Opus 5.5 plans, Haiku 5.5 scouts, Sonnet 5.5 builds, Fable 5.1 judges, and a Stop hook decides when the bug is actually dead
You drop 3 files into .claude/agents/ and launch:
claude --model opus
here's how it went:
→ Opus 5.5 planned it: repro test first, then root cause, then the fix
→ Haiku 5.5 scouts mapped 188 files and found 2 charge paths with no idempotency key
→ Sonnet 5.5 wrote the fix and said "fixed"
→ the Stop hook ran the tests: 31/32, a retry still made 2 charges. Exit 2, not done
→ Fable 5.1 found the root cause: the key used Date.now(), so every retry got a new key
→ Sonnet patched it to the order id, tests went 32/32, Fable signed off
Without the hook, that "fixed" would have gone to prod
The rules that made it work:
→ no fix without a failing repro test first
→ same test fails twice? Fable is called in: root cause, or are we just patching the symptom?
→ Claude can say "fixed", only exit 0 makes it true
Opus plans · Haiku scouts · Sonnet builds · Fable judges
the full tree
> .claude/agents/scout.md → model: haiku · tools: Read, Grep, Glob
> .claude/agents/builder.md → model: sonnet · writes the repro test, then the fix
> .claude/agents/judge.md → model: claude-fable-5-1 · read-only root-cause reviewer
> .claude/settings.json → Stop hook → scripts/verify.sh (exit 2 = not fixed)
> Opus 5.5 main session only sees summaries, never raw transcripts
paste this prompt into Claude Code ↓
"Set up a bug-fix squad in this repo:
1. Create .claude/agents/scout.md (model: haiku, tools: Read, Grep, Glob) to find every code path involved in a bug
2. Create .claude/agents/builder.md (model: sonnet) that writes a failing repro test FIRST, then the fix, then runs the tests
3. Create .claude/agents/judge.md (model: claude-fable-5-1, read-only tools) for root-cause review: fixing the cause or the symptom?
4. Write scripts/verify.sh (tests + lint, print the reason and exit 2 on failure) and register it as a Stop hook in .claude/settings.json
5. Add to CLAUDE.md: no fix without a red test first, scanning goes to scout, edits go to builder, call judge after the same failure twice and before saying fixed
Show every change as a diff first. No edits until I say go"
↳ code.claude.com/docs/en/hook…
bookmark it, this is the one you`ll actually use
7
65
2,147
Arcos retweeted
YOUR OPUS 5.5 IS DOING F*CKING INTERN WORK
Almost nobody runs Claude Code like this, and every piece of it is already in the docs
The idea: Opus 5.5 never touches the grunt work. Haiku 5.5 scouts, Sonnet 5.5 builds, Fable 5.1 judges, and a Stop hook decides when the job is actually done
Your main session stays lean while a whole squad works under it: every subagent burns its own context window, Opus only reads the summaries
You drop 3 files into .claude/agents/ and launch:
claude --model opus
here's who does what:
→ Opus 5.5 is the planner: breaks the task down, hands it out, reads one-paragraph reports instead of 40 raw files
→ Haiku 5.5 is the scout: read-only, Read/Grep/Glob only, maps the repo fast and cheap so Opus never has to
→ Sonnet 5.5 is the builder: writes the code in its own context, runs the tests, sends a diff back
→ Fable 5.1 is the judge: cold review of every diff, hunts the bug everyone else was too close to see
→ scripts/verify.sh is the law: Claude can say "done", only exit 0 makes it true
Fable gets pulled in at exactly three moments:
→ before the plan locks: what breaks if this assumption is wrong?
→ when the same test fails twice: root cause, or are we patching the symptom again?
→ before "done": cold review of the final diff, zero context, zero mercy
Opus plans · Haiku scouts · Sonnet builds · Fable judges
the full tree
> .claude/agents/scout.md → model: haiku · tools: Read, Grep, Glob
> .claude/agents/builder.md → model: sonnet · full edit access
> .claude/agents/judge.md → model: claude-fable-5-1 · read-only reviewer
> .claude/settings.json → Stop hook → scripts/verify.sh (exit 2 = not done)
> Opus 5.5 main session only sees summaries, never raw transcripts
paste this prompt into Claude Code ↓
"Set up a model squad in this repo:
1. Create .claude/agents/scout.md (model: haiku, tools: Read, Grep, Glob) for read-only repo mapping
2. Create .claude/agents/builder.md (model: sonnet) for implementation and running tests
3. Create .claude/agents/judge.md (model: claude-fable-5-1, read-only tools) for adversarial diff review
4. Write scripts/verify.sh (tests + lint, print the reason and exit 2 on failure) and register it as a Stop hook in .claude/settings.json
5. Add to CLAUDE.md: scanning goes to scout, edits go to builder, call judge before locking a plan, after the same failure twice, and before saying done
Show every change as a diff first. No edits until I say go"
↳ code.claude.com/docs/en/sub-…
bookmark this, your Opus context will thank you
STOP F*CKING UPGRADING MODELS
Someone cut open 11 coding agents and found the same 7 organs in every one. Yours probably has 3
Dario Amodei just filed $ANT with $16.3B in revenue in 6 months, and the paper everyone in AI is quietly reading right now says the money isn't in the model
Wavestone AI Lab read the source of Claude Code, Codex CLI, Gemini CLI, OpenHands, Aider, Mistral Vibe, OpenCode, Hermes, Pi, OpenClaw and Mini-SWE-Agent. ~4M lines of Python, TypeScript and Rust
agent = model + harness. the model is one call in the middle of a loop, everything around it is the harness
so I pointed Claude Code at my own repo:
claude --model opus
score: 0/7. 3 minimal, 4 missing. it fixed them one by one
here's each organ and what I added:
→ agent loop: from manual chats to BACKLOG.md + /loop, one task per run
→ llm routing: from Opus on everything to a model per subagent
→ tools: from every tool with no limits to an allow-list per agent in settings.json
→ memory: from a 412-line CLAUDE.md to short rules in CLAUDE.md + state in NOTES.md
→ safety: from nothing to a PreToolUse guard that says no (exit 2)
→ orchestration: from one agent to scout · builder · judge in .claude/agents/
→ extensibility: from nothing to .claude/skills/ + 1 MCP server
what the paper found inside all 11:
→ 0/11 import LangChain, LangGraph or AutoGen
→ 0/11 search code with vector embeddings. it's ripgrep and tree-sitter
→ SKILL.md is in 9/11, MCP in 8/11. skills quietly won
→ Codex's hook events are nearly identical to Claude Code's: PreToolUse, PostToolUse, PermissionRequest. a de facto standard
the moment it paid off: Fable 5.1 caught the memory patch failing verify twice and said "stop, split the file: rules in CLAUDE.md, state in NOTES.md". and the new guard blocked git push --force main on its first test
same Opus 5.5, same 20 tasks:
0/7 harness → 7/20
7/7 harness → 19/20
the model is one call · the harness is 7 organs
the full tree
> CLAUDE.md → short hard rules, nothing else
> NOTES.md → state the agent updates between runs
> BACKLOG.md → one task per /loop run
> .claude/settings.json → permissions allow-list, PreToolUse guard, Stop verify
> scripts/guard.sh → blocks force-push, .env writes, rm -rf (exit 2)
> .claude/agents/ → scout (haiku, read-only) · builder (sonnet) · judge (claude-fable-5-1, read-only)
> .claude/skills/ → one skill per repeatable job
paste this prompt into Claude Code ↓
"Audit this repo's harness against the 7 subsystems of a coding agent: agent loop, LLM routing, tools, memory & context, safety & permissions, orchestration, extensibility.
1. For each one show what exists now (CLAUDE.md, .claude/settings.json, hooks, .claude/agents/, .claude/skills/, MCP config) and rate it missing / minimal / solid
2. Fix the weakest first, one organ per step: smallest change that makes it solid
3. After every step run scripts/verify.sh (create it if missing: tests + lint, exit 2 on failure) and don't move on until it passes
4. Call the judge subagent before locking the plan, after the same failure twice, and before the final diff
Show every change as a diff first. No edits until I say go"
↳ code.claude.com/docs/en/hook…
bookmark it, this is the one you`ll actually use
Harness engineering is the $300k skill nobody is teaching you.
214 hooks fired last night. 3 of them stopped a disaster. That's the $200 you're not losing.
Same Opus 5.5, same backlog:
no harness → 3/9 tasks done, one force-push to main, a $200 bill of retries.
harness → 9/9 merged overnight, 0 clicks from me.
The model is the engine. The harness is the car.
The harness is everything around the model that it can't skip: rules it must follow, guards it can't get past, checks it can't fake.
Here's mine, all native Claude Code ↓
→ CLAUDE.md: 14 hard rules. How to test, what never to touch, when to stop and ask.
→ PreToolUse hook: the guard. Blocks force-push, .env writes and rm -rf before they run (exit 2 = denied).
→ PostToolUse hook: fmt, lint and typecheck after every single edit. The model sees errors instantly, not at the end.
→ Stop hook: verify.sh. No green tests, no "done".
→ Subagents: Haiku 5.5 scouts, Sonnet 5.5 builds in worktrees, Opus 5.5 only reads summaries.
→ Fable 5.1 as the judge: wakes up on 3 triggers only. Before the plan, after the same failure twice, before merge.
What it caught last night while I slept:
→ git push --force main: blocked.
→ write .env.production: blocked.
→ rm -rf migrations/: blocked.
→ Same test failing twice. Fable: "Stop patching, the root cause is a missing idempotency key."
7am:
→ 9 PRs merged.
→ 214 hooks fired.
→ 3 bad calls blocked.
→ 0 human clicks.
Every one of those 3 blocks is a prod incident you'd pay for. That's what a harness is worth.
The full tree:
> CLAUDE.md → 14 rules, short and absolute.
> .claude/settings.json → PreToolUse guard, PostToolUse lint, Stop verify.
> scripts/guard.sh → denylist for Bash and Write (exit 2 blocks the call).
> scripts/verify.sh → tests and lint (exit 2 = not done).
> .claude/agents/scout.md → model: haiku, tools: Read, Grep, Glob.
> .claude/agents/builder.md → model: sonnet, one task per worktree.
> .claude/agents/judge.md → model: claude-fable-5-1, read-only.
Paste this prompt into Claude Code ↓
"Build a harness for this repo:
1. Write CLAUDE.md with short hard rules: how to run tests, files never to touch, never push to main, one task at a time, stop and ask when unsure.
2. Write scripts/guard.sh and register it as a PreToolUse hook for Bash and Write. Block force-push, writes to .env*, and rm -rf outside build dirs. Print the reason and exit 2.
3. Register a PostToolUse hook on Edit and Write that runs the formatter, linter and typecheck on the changed file and reports errors back.
4. Write scripts/verify.sh (full tests and lint, print the reason and exit 2 on failure) and register it as a Stop hook.
5. Create .claude/agents/scout.md (model: haiku, tools: Read, Grep, Glob), builder.md (model: sonnet, one task per git worktree) and judge.md (model: claude-fable-5-1, read-only). In CLAUDE.md, say when to call each one: judge before locking a plan, after the same failure twice, and before every merge.
Show every change as a diff first. No edits until I say go."
Then, before bed: /loop clear BACKLOG.md, one task per run.
↳ code.claude.com/docs/en/hook…
↳ code.claude.com/docs/en/sub-…
Bookmark this. The next model upgrade won't save you. The harness will.
7
39
1,449
YOUR OPUS 5.5 IS DOING F*CKING INTERN WORK
Almost nobody runs Claude Code like this, and every piece of it is already in the docs
The idea: Opus 5.5 never touches the grunt work. Haiku 5.5 scouts, Sonnet 5.5 builds, Fable 5.1 judges, and a Stop hook decides when the job is actually done
Your main session stays lean while a whole squad works under it: every subagent burns its own context window, Opus only reads the summaries
You drop 3 files into .claude/agents/ and launch:
claude --model opus
here's who does what:
→ Opus 5.5 is the planner: breaks the task down, hands it out, reads one-paragraph reports instead of 40 raw files
→ Haiku 5.5 is the scout: read-only, Read/Grep/Glob only, maps the repo fast and cheap so Opus never has to
→ Sonnet 5.5 is the builder: writes the code in its own context, runs the tests, sends a diff back
→ Fable 5.1 is the judge: cold review of every diff, hunts the bug everyone else was too close to see
→ scripts/verify.sh is the law: Claude can say "done", only exit 0 makes it true
Fable gets pulled in at exactly three moments:
→ before the plan locks: what breaks if this assumption is wrong?
→ when the same test fails twice: root cause, or are we patching the symptom again?
→ before "done": cold review of the final diff, zero context, zero mercy
Opus plans · Haiku scouts · Sonnet builds · Fable judges
the full tree
> .claude/agents/scout.md → model: haiku · tools: Read, Grep, Glob
> .claude/agents/builder.md → model: sonnet · full edit access
> .claude/agents/judge.md → model: claude-fable-5-1 · read-only reviewer
> .claude/settings.json → Stop hook → scripts/verify.sh (exit 2 = not done)
> Opus 5.5 main session only sees summaries, never raw transcripts
paste this prompt into Claude Code ↓
"Set up a model squad in this repo:
1. Create .claude/agents/scout.md (model: haiku, tools: Read, Grep, Glob) for read-only repo mapping
2. Create .claude/agents/builder.md (model: sonnet) for implementation and running tests
3. Create .claude/agents/judge.md (model: claude-fable-5-1, read-only tools) for adversarial diff review
4. Write scripts/verify.sh (tests + lint, print the reason and exit 2 on failure) and register it as a Stop hook in .claude/settings.json
5. Add to CLAUDE.md: scanning goes to scout, edits go to builder, call judge before locking a plan, after the same failure twice, and before saying done
Show every change as a diff first. No edits until I say go"
↳ code.claude.com/docs/en/sub-…
bookmark this, your Opus context will thank you