

ai / deep-learning formerly @immunefi, @code4rena
ai / ml
Joined February 2021
- Tweets1.4K
- Following999
- Followers1.2K
- Likes4.5K




everyday we discover an fbi backdoor

‼️ALERT - Two new unpatched CVSS 9.0 RCE flaws in #Linux's KSMBD SMB server were disclosed on public kernel mailing lists before fixes were ready.
One can be triggered WITHOUT authentication.
Neither has a mainline kernel fix.
Details here ↓ thehackernews.com/2026/10/tw…

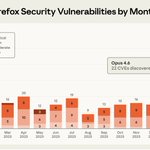
updating the meme for you all
congrats to the @MistralAI team
nitter.cf/MistralAI/status/21074…


Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
just amazing

If doomscrolling X is part of your research workflow, we built something for you.
Introducing Paperscrolling, now on iOS and Android 🚀
Follow the latest research with key ideas, figures, and audio explanations from alphaXiv Briefs
Check it out here!
play.google.com/store/apps/d…
🐚xtotem retweeted

🎯 Learning is most effective at the frontier of capability: problems that are too easy or too hard teach nothing.
For LLM reasoners trained with GRPO this is literal: problems the model always or never solves give zero gradient.
We introduce Frontier Learning👇🧵


🐚xtotem retweeted

Bon bah la boucle est bouclée... en dehors de la webcam de la buvette de l'Assemblée Nationale, il reste quoi à pwn dans ce pays ?

L'Anssi et la Dinum victimes à leur tour d'une fuite de données: les deux agences dédiées à la cybersécurité ont été compromises
l.bfmtv.com/Br9x


This Jev thing is the only “AI” thing that got me interested in a long time.
And it’s actually how ive been saying LLMs should be used for a long time.
You write “normal” intelligible software that uses LLMs as tools. Not chatbots, not agents. Not giving over control of computers to opaque text generators.
The “Machine God” is a dangerous delusion.
Not put
very interesting direction
will keep a eye on it


jev really looks like the ultimate tool for an llm
nitter.cf/MatijaSosic/status/210…

🐚xtotem retweeted

Introducing ToolGrad: an efficient framework for generating tool-use datasets. By generating ground-truth tool-use chains before prompts, it achieves a nearly 100% pass rate and improved LLM tool-use performance. More: goo.gle/4xNKTNH

ALT While prior art generates tool-use datasets by searching solutions of user queries with low pass rate, ToolGrad generates successful tool-use chains before generating prompts, yielding high pass rate.
🐚xtotem retweeted

Your devices are stronger together. 🖥️🤝🖥️
Just announced at IFA, NVIDIA PAIR automatically links systems across your local network and sends inference requests wherever there’s available capacity, helping agents run more efficiently.
🐚xtotem retweeted

Introducing Speculative Programmatic Tool Calling (sPTC)!
A general class of technique for speculating on tool calls during code generation in a harness and queuing them early to overlap with token generation + REPL execution time.
Blog: alexzhang13.github.io/blog/2…

🐚xtotem retweeted

this wild defcon talk is finally out
researchers created a fake defi startup, hired lazarus it workers, put them into a sandbox and recorded their tooling, workflows, and faces from inside the operation
starts at 5:46:09
youtube.com/live/_uYQr8hfpbI…

🐚xtotem retweeted
🚢 Marin 535B-A23B started training this week! As usual, the whole process is open.
Voyage plan: pretraining (80%) + midtraining (20%) on 18.75T tokens on 11 x GB200 NVL72 for ~3 months (2.7e24 FLOPs). Post-training will follow.
Before kicking off the run, we trained a 4-rung scaling ladder from 1.6B-A61M (48B tokens) to 27.7B-A1.2B (926B tokens) to debug issues, and to make a forecast of our hero run. This is by far our biggest run, so definitely expecting the unexpected.


🐚xtotem retweeted

Researchers pulled a 256-bit encryption key out of a device by filming its power LED.
The status light on a smart card reader flickers in sync with the chip's power draw, and that power draw leaks the key. They recovered a full ECDSA key from 16 meters away, through a window, using a hijacked security camera. No malware, no contact, just video of a status light.
The trick: a camera's rolling shutter turns 60 frames per second into 60,000 brightness samples per second.
The light that tells you a device is on tells an attacker what it is computing.
Proof, Ben-Gurion University 2023: nassiben.com/video-based-cry…

🐚xtotem retweeted

💥 Our new 116-pages long paper: we extract encrypted raw reasoning from OpenAI, Anthropic, and Gemini models at scale.
This vulnerability leads to many security issues, including distillation attacks and credential extraction.
We also find a lot of examples of illegible reasoning (especially for GPT models), unfaithful reasoning, and evidence that some open-weight models might've been indeed distilled from frontier proprietary models.
Check out the paper in detail, including the appendix! It's one of the most exciting projects I've been involved in.


trully insane

The new experimental dspy.Flex, led by @michaelnisaac, lets you learn code that represents your task, not just optimize its instructions.
By expanding dspy.GEPA, Flex can rewrite predictors, control flow, DSPy primitives, and the balance between Python and LM calls.
We find it extremely helpful for reducing the cost of pipelines, and are excited to share more in a blog coming soon.
🐚xtotem retweeted

GPT 5.6 Sol can one-shot convert an arXiv paper into an interactive Marimo notebook!
Great for papers best understood hands on (lots of fun examples in interpretability, inference engineering, agent harnesses, benchmarking, and more)
Play around with the notebook, inspect the code, or try the same workflow with your own agents below
🐚xtotem retweeted
“Language Models Need Sleep: Learning to Self-Modify and Consolidate Memories”
LLMs can learn inside the context window, but that knowledge disappears when the session ends.
This paper from google adds a sleep phase where the model consolidates short-term memories into long-term weights using Knowledge Seeding.
Then it dreams by generating RL-trained synthetic data to rehearse new knowledge and reduce forgetting. Creating a continual-learning LLM that can self-modify instead of staying frozen after pretraining.
