

Founder of FitTrack+
New Jersey, USA
Joined May 2012
- Tweets226
- Following66
- Followers28
- Likes617


For anyone with the hardware (and money) to run Kimi K3.1 locally, I'm curious what harness you're using and how well it's performing compared to the hosted version.
Belal retweeted

If you deploy on Railway, take 30 minutes today and do this
The last ~24 hours have been rough for anyone on Railway, so here's a rundown of what happened and what you should actually do about it.
What happened (per Railway's status page)
- Oct 21, ~07:24 UTC: Railway started investigating an issue. Soon after, the dashboard, API and CLI went down, and builds were paused in every region. Their support site went down too.
- Most of the day: builds stayed paused while they worked through it. They logged everyone out, since some sign-in sessions were affected.
- ~22:00 UTC: they published a security disclosure. They told everyone to revoke all environment variables stored in Railway, including API keys and private registry credentials, and to check service logs for anything weird.
- Overnight: they rotated every storage bucket credential. They published guides for rotating Postgres, MySQL, MongoDB and Redis credentials, and for checking unusual usage on OpenAI, Anthropic, OpenRouter, Grok, Stripe, AWS, GCP and GitHub.
- Oct 22, ~04:17 UTC: they invalidated all Railway API tokens.
- Right now: builds are coming back in stages: Enterprise first, then Pro, Hobby, Free and Trial. The Redeploy button is disabled, and services with pre-deploy commands are getting stuck.
So it's not just an outage. Railway is telling you to assume your secrets are out there. Take that seriously.
What I'd do right now, in order
1. Move crypto funds first. If you ever put a wallet private key in a Railway env var (deployer, relayer, hot wallet, anything), make a new wallet and move the funds now. You can revoke an API key, but you can't take back a leaked private key. Check the address on an explorer too.
2. Rotate anything that costs money. OpenAI, Anthropic, Gemini, OpenRouter, Stripe, AWS, GCP, R2/S3 and so on. Revoke the old key at the provider rather than just in Railway, then check the usage and billing dashboards for charges you don't recognise.
3. Rotate database passwords. If you used Railway's Postgres, MySQL, Mongo or Redis, follow their guides to change the passwords. Look for users or data you didn't create.
4. Rotate your app's own secrets. JWT secrets, webhook secrets, internal API keys, OAuth client secrets. Yes, everyone gets logged out. Do it anyway.
⚠️ Careful with encryption keys. If you swap one without re-encrypting your data, the data encrypted with the old key becomes unreadable. Plan that one properly.
5. Clean up your Railway account.
- Run railway logout && railway login.
- Create new API tokens for CI, since the old ones are dead.
- Reconnect the GitHub integration, and check your GitHub security log and deploy keys for access you didn't grant.
- Look through Railway's audit log.
6. Redeploy when builds come back. Use Cmd/Ctrl+K → "Deploy Latest Commit" while the Redeploy button is down. Heads up: once you rotate keys at the provider, your running app breaks until that redeploy goes out.

An urgent notice from the Railway team
blog.railway.com/p/security-…

Belal retweeted

An urgent notice from the Railway team
blog.railway.com/p/security-…
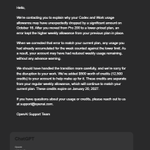
Respect to OpenAI always correcting their mistakes and giving more than deserved. @thsottiaux

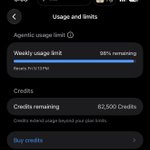
Is anyone hitting their usage limits on the $200 Claude subscription?
If so, I’m curious what you’re working on.
If you’re working on a codebase solo, actually read the unit tests your agent is writing. You’ll realize how many test nothing useful. A few solid E2E tests beat hundreds of pointless unit tests that just bloat your codebase.
Belal retweeted

Samsung open-sourced a method that shrinks 13B parameter LLM into less than 1 GB.
It's called "LittleBit"
Instead of storing AI weights as standard numbers, they used latent factorization to crush them down to extreme sub-1-bit levels.
In some configurations, they hit 0.1 bits per weight.
But here is where the architecture gets crazy.
When you compress an AI this much, you can stop doing math.
Instead of forcing the hardware to do heavy floating-point multiplication, LittleBit replaces the core computation with a bitwise XOR operation.
It swaps complex matrix math for basic sign flips.
The results rewrite the rules of model deployment:
• Unlocks a massive 11.6x inference speedup relative to standard FP16 models.
• Radically reduces memory footprint and loading bandwidth.
• Maintains robustness in extreme sub-0.5 bit regimes where previous compression methods catastrophically fail.
This is not a clever optimization.
It is the blueprint for running massive, state-of-the-art AI locally on cheap, resource-constrained devices.

Belal retweeted

You can now train your own Decision model like Jev locally!
We increased Qwen3.5 0.8B’s aggregate accuracy from 20.7% to 74.3% across 3 decision benchmarks - on just 4GB VRAM.
Turn any LLM like Qwen3.8, Gemma 4 into decision models with our open-source Unsloth repo.
We fine-tuned with a Clef head using Unsloth and LoRA (r=64) for one epoch, increasing downstream accuracy from 30–37% to 78%.
GitHub: github.com/unslothai/unsloth
Guide and Notebooks: unsloth.ai/docs/basics/train…

Haiku 5.5 looks to be great and an actual game changer for 20$ plans . You can have Sonnet as an Orchestrator because it’s smart enough unlike prior iterations and Haiku be your daily driver .
PSA: Stop paying for CalAI and other fitness apps while FitTrack is free. I’m looking for dedicated gym-goers to try it out and give me honest feedback. Tell me what’s missing and what could be better.
Belal retweeted

dots is 𝗵𝗮𝗻𝗱𝘀 𝗱𝗼𝘄𝗻 𝗺𝘆 𝗳𝗮𝘃𝗼𝗿𝗶𝘁𝗲 𝗮𝗴𝗲𝗻𝘁 right now. Over the past few days it's become my main one. Especially when it's open on my desktop and talking to it feels like talking to a real person, it feels incredibly futuristic.
I care a lot about how things feel. For some reason, the dots interface looks a lot like iMessage, and it's unusually smooth to use. The web app used to have a bug where dragging the sidebar edge overlapped the chat box in the bottom right. No big deal.
Besides texting it, I also just call it. I've kept my GPT subscription partly for GPT Live's voice. I still haven't found anything that matches its latency and how human it feels. Some people say dots calls are just GPT Live with a different entry point. In my experience, connecting takes a bit longer, but once you're connected it's a lot steadier, and it answers fast. And whether I'm texting or calling, on my phone or my computer, it's the same dot, hooked up to most of my plugins, including the ones I wrote myself.
Since it's this much like a coworker, it should get a workbench too. I've found Space works especially well with dots: give it a Space of its own, it updates its progress there, you edit right on the page, and when something needs doing, you @ it. Working together feels just like working with a real person, only much faster. Add a few scheduled tasks so it checks on its own at set times and updates the page itself. It's insanely good.
Over these past few days, a lot of different writing and content work has all come together through it. My guess is that's why OpenAI built dots and put it second in the left sidebar. It may end up as ChatGPT's front door.
Right now, chatting with your dot 𝗱𝗼𝗲𝘀𝗻'𝘁 𝗰𝗼𝘂𝗻𝘁 𝘁𝗼𝘄𝗮𝗿𝗱 𝘆𝗼𝘂𝗿 𝗖𝗵𝗮𝘁𝗚𝗣𝗧 𝘂𝘀𝗮𝗴𝗲 𝗹𝗶𝗺𝗶𝘁𝘀. Tasks it hands off to Codex or ChatGPT Work still count toward those products' limits as usual, and for the first month after launch, its allowance for heavier work is extended. Make the most of it and set up a workbench for your dot: create a new Space, name it "Workbench," then send it this 👇
"I created a Space called Workbench. You'll maintain it from now on. Put three pages in it:
- In progress: everything I'm following up on, with its status, next step, and who it's waiting on
- Needs my decision: decisions I need to make, with the options and your recommendation
- Today: what you did today and which page you changed, with each new day at the top
Every weekday at 9 a.m. (my time zone), check the email, Slack and calendar I've connected (skip any I haven't), and update these three pages when something changes. You can handle research, organizing and updating these pages on your own. Before replying to emails, sending messages or editing other people's documents, ask me first. If a deadline is at risk or something needs my decision, message me in ChatGPT. When I @ you on a page, make the changes my comment asks for.
After you set up the scheduled task, tell me where it's saved and when it runs, then do a test run. If you can't set it up, tell me straight away."

Is it just me, or do other founders/developers find it satisfying when you find a bug in your app and fix it yourself before anyone else notices?
Limits just reset. Happy building! Let me know in the comments what you’re building with your usage.

Am I insane, or don't I remember Tibo saying that there would be a global reset at 10:00 pst ..... :(
Downgraded my codex subscription because there is no justification to pay 200, when dots is included in the 100 dollar plan.
You’re throwing money away paying for a fitness tracker. Get FitTrack while it’s free and become a permanent member.
apps.apple.com/us/app/fittra…
Dots from openAI is cool and all but the goal is to use the best and smartest models out there . Dev day was cool but I will most likely downgrade my account or just cancel it entirely .
There better be something big dropping today to justify this. Otherwise, I’m canceling my $200/month subscription.

Hi,
Tomorrow we are re-opening the Pro $200 subscriptions to new subscribers, but together with it we are also changing how we calculate the usage for it. In effect, if you do the math, it will net out at half the dollar in API spend compared to the old Pro $200 plan.
Now that it's said, let me explain why this is happening and why you will still get more work done than if you were on the Pro $200 subscription one month ago.
(a) We didn't want to compromise in other ways and are committing to not reintroducing the 5h limit, so that you can fully use the weekly usage when you want.
(b) On the subscription, we guarantee that over time you always get more work done and with an increasing level of quality. This means that you will continue to get more value per dollar spent as a result of models getting more efficient and us passing down the improvements in the form of API price reductions.
(c) We don't want to put an incentive on ourselves to artificially inflate the API list prices to make it look like you are getting a lot (and workaround it through discounts, etc). Instead we want to continue to both rapidly reduce prices and increase capabilities of models on the API. This week we introduced GPT-6 Sol and GPT-6 Luna at 50% of their previous price. Over time, we see prices go low enough that it makes sense for most to buy usage as needed without there being a significant gap between what you get in a subscription and what you get in the API for a dollar spent.
(d) Tomorrow, we are adding more things to the subscription that won't draw on the usage, I won't reveal what that is yet.
I wanted to be transparent before all the big announcements tomorrow. Lots of new exciting things are coming to the subscriptions that will make it super compelling, but I wanted to make sure to share this change ahead of time so you can all understand it before we shower you with good news.
Codexingly,
Tibo