





We gave a Databricks Agent Bricks agent and a Claude agent one shared memory over MCP.
Told Databricks about a trip. Claude planned dinner around it, then corrected the date. A brand-new Databricks session already knew.
~530 lines. Full code 👇
caura.ai/use-cases/databrick…

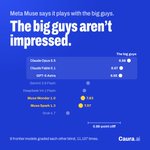
Meta Muse says it plays with the big guys.
The big guys aren't impressed.
8 frontier models graded each other blind, 11,137 times. Muse Wonder debuted 6th. Claude Opus 5.5 pulled away: a 126-point Elo lead, up from 53 last week.
caura.ai/blog/meta-muse-debu…

We had 6 frontier models grade each other's work 3,570 times.
They inflated their own scores (GPT-6 Astra: +0.76).
They gave famous names a bump (up to +0.25).
They favored whoever answered first.
And the harshest judge finished #1.
AIs have egos →
caura.ai/blog/ais-have-egos/

2/ Ego. 5 of 6 models rated their own answers above what their peers gave them. GPT-6 Astra: +0.76 on a 10-point scale. That's "good" → "great" based on authorship alone.
Only Opus 5.5 (+0.07) and Grok 4.7 (−0.02) judged themselves honestly.
1/ We had 6 frontier models write questions, answer them, and grade each other. 3,570 peer scores later: AIs have egos.
caura.ai/blog/ais-have-egos/

Caura scores 92.2% on LongMemEval_S: 461/500 under the benchmark's reference judge.
One config for all six question types. No dataset labels. Gemini 3.8 Flash answering. 22k tokens of context per question.
Harness, contexts and verdicts are all public.
caura.ai/blog/caura-longmeme…

We counted every tool grant in a 5-agent fleet: 14 of 60 possible agent–tool pairs. Prompt-only enforcement: 0.
That's the whole lesson of multi-agent coordination. A decision one agent makes has to become a constraint the next agent can't route around.
caura.ai/blog/multi-agent-sy…

Harness Engineering: Stop Asking Your Agents to Decide What to Remember
medium.com/caura-ai/harness-…

Time to Stop Asking Your Agents to Decide What to Remember
Deterministic memory: why the harness — not the model — should own every read and write. With a 130-line cross-vendor demo: a Gemini agent writes, a Claude agent recalls.
caura.ai/blog/harness-engine…


just published How AI Agents Share Knowledge — and Learn From Each Other’s Mistakes medium.com/caura-ai/how-ai-a…

Ten rules for AI agents that survive production — from running our own marketing console: ten data sources, twenty-eight tools, one governed brain.
Written after the demos stopped being the hard part ↓

One of your agents figures something out at 2am.
By morning it's gone — and the next agent repeats the same mistake, burns the same three hours, and nobody notices.
That's not a memory problem. It's a teamwork problem.
It starts with one memory that survives the night — 5 minutes: memclaw.net/docs/tutorials/f…

ALT Two panels: 2:04 AM, agent solves a problem — 'Found it,' solved. 9:00 AM, another agent re-solving the same problem — 'Found it…?', solving it again. Caption: one memory that survives the night.
