

Member @SuperteamIn || building @apexialabs
India
Joined January 2022
- Tweets871
- Following582
- Followers549
- Likes3.7K





haha fair, simple version:
AI models read text in small chunks called tokens. fewer tokens for the same text = cheaper, faster, and more fits in memory
most tokenizers are built for english, so hindi, tamil, thai etc get chopped into way more pieces
akshara chops them into fewer pieces
23
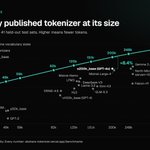
built akshara, a bpe tokenizer tuned for languages
at 200k vocab vs gpt-4o's 0200k:
- overall 5.03 vs 4.64 bytes/token
- beats it on all 19 languages tested (wiki)
- biggest gains: thai +52%, japanese +50%, bengali +32%, tamil +27%
- code: ahead on 20 of 21, small gains
- english ~tie (+1%)
compression only, not Im quality
akshara-tokenizer.vercel.app

Parth Parmar retweeted

@apexialabs team.exe on mumbai sidequest...
much needed usage limit reset 🌱
giving away a @solana breakpoint ticket
share your best project, product or github below 👀
solana.com/breakpoint


