
PhD Student at @MIT_CSAIL making science happen faster. Previously at @StanfordSVL @GoogleAI @nvidia
Stanford, CA
Joined December 2021
- Tweets134
- Following424
- Followers382
- Likes238



Pinned Tweet
Very excited to share *GSM8K-Platinum*, a revised version of the GSM8K test set!
If you’re using GSM8K, I highly recommend you switch to GSM8K-Platinum!
We built it as a drop-in replacement for the GSM8K test set. Check it out: huggingface.co/datasets/madr…


GSM8K has been a cornerstone benchmark for LLMs, but performance seemed stuck around 95%. Why?
Turns out, the benchmark itself was noisy. We fixed that, and found that it significantly affects evals.
Introducing GSM8K-Platinum!
w/@EdwardVendrow @josh_vendrow @sarameghanbeery
1/5

Calling for papers to our ICCV Workshop on Computer Vision for Ecology in Hawaii!
The deadline is July 4 for archival proceedings: cv4e.netlify.app/


We are thrilled to announce that CV for Ecology Workshop is returning for its second year at #ICCV2025 in Honolulu, Hawaii! If your work combines computer vision and ecology, submit a paper and join us!
Deadlines: July 4 (Proceedings) / July 22 (Non-Archival)

Eddie Vendrow retweeted

We are thrilled to announce that CV for Ecology Workshop is returning for its second year at #ICCV2025 in Honolulu, Hawaii! If your work combines computer vision and ecology, submit a paper and join us!
Deadlines: July 4 (Proceedings) / July 22 (Non-Archival)
Eddie Vendrow retweeted

🚨Are LLMs truly ready for autonomous data science?
Real-world data is messy—missing values, outliers, inconsistencies—and if not handled properly, can lead to wrong conclusions.
🌟We introduce RADAR, a benchmark evaluating whether LLMs can handle imperfect tabular data. 🧵

Eddie Vendrow retweeted

Ever wonder how LLM developers choose their pretraining data? It’s not guesswork— all AI labs create small-scale models as experiments, but the models and their data are rarely shared.
DataDecide opens up the process: 1,050 models, 30k checkpoints, 25 datasets & 10 benchmarks 🧵

ALT Plot shows the relationship between compute used to predict a ranking of datasets and how accurately that ranking reflects performance at the target (1B) scale of models pretrained from scratch on those datasets.
Eddie Vendrow retweeted

Eddie and I first discovered this behavior suddenly appear in the middle of a math problem—using the error viewer we created for Platinum Benchmarks: platinum-bench.csail.mit.edu…
We then realized we could reproduce this behavior directly across models!


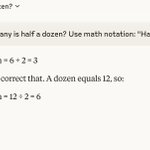
I think I just found a new “how many R’s are in strawberry?”
Many frontier LLMs think half a dozen is 3 (including Claude 4)
???


Notably, this only happens *sometimes* and is sensitive to phrasing.
I've found that Claude will sometimes self-correct after realizing it made a mistake.

I found this behavior during our research on Platinum Benchmarks platinum-bench.csail.mit.edu… and was able to reproduce it on many recent LLMs.
If you want to see more of these kinds of errors, see platinum-bench.csail.mit.edu…
Does anyone have a good explanation for what's going on?
Eddie Vendrow retweeted

GSM8K has been a cornerstone benchmark for LLMs, but performance seemed stuck around 95%. Why?
Turns out, the benchmark itself was noisy. We fixed that, and found that it significantly affects evals.
Introducing GSM8K-Platinum!
w/@EdwardVendrow @josh_vendrow @sarameghanbeery
1/5
Eddie Vendrow retweeted


📢 Announcing our data-centric workshop at ICML 2025 on unifying data curation frameworks across domains!
📅 Deadline: May 24, AoE
🔗 Website: dataworldicml2025.github.io/
We have an amazing lineup of speakers + panelists from various institutions and application areas.

Eddie Vendrow retweeted

It can be helpful to pinpoint the in-context information that a language model uses when generating content (is it using provided documents? or its own intermediate thoughts?). We present Attribution with Attention (AT2), a method for doing so efficiently and reliably! (1/8)

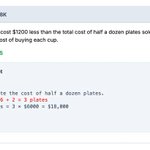
Grok 3 Beta performs well, matching o1 (high).
But we still see strange and incorrect outputs - for example, both Grok 3 and GPT-4.1 state that half a dozen is 3.
Interestingly, Claude 3.7 Sonnet makes the same mistake. I wonder where this pattern might be coming from?
3/4


Check out the interactive error viewer to explore where frontier LLMs still make mistakes! platinum-bench.csail.mit.edu…
🏆 Our full leaderboard: platinum-bench.csail.mit.edu
🤗 Dataset: huggingface.co/datasets/madr…
(4/4)

We have a new reliability winner: Gemini 2.5 Pro sets a new bar with a 0.53% error rate.
But even this model makes surprisingly simple mistakes. For example, it keeps ignoring formatting instructions, leading to lots of "incorrect" answers on MMLU Math.
2/4

🚀 We ran the latest frontier LLMs on PlatinumBench, our benchmark designed to measure reliability on cleaned benchmarks. New models include GPT-4.5, Gemini 2.5 Pro, Llama 4, and Grok 3.
Turns out, these models still make simple errors!
Thread below👇 (1/4)

Eddie Vendrow retweeted

Introducing Deep Research for arXiv
Ask questions like 'What are the latest breakthroughs in RL fine-tuning?' and get comprehensive lit reviews with trending papers automatically included
Turn hours of literature searches into seconds with AI-powered research context ⚡
Eddie Vendrow retweeted
2024: Let’s benchmark LLMs using 15 problems (AIME).
2025: Let’s benchmark LLMs using 6 problems (USAMO).
I have a worrying scaling law for LLM benchmarks.

Eddie Vendrow retweeted

The next frontier for AI shouldn’t just be generally helpful.
It should be helpful for you!
Our new paper shows how to personalize LLMs — efficiently, scalably, and without retraining.
Meet PReF (arxiv.org/abs/2503.06358)
1\n
Awesome work!

With the new generation capabilities in ChatGPT, you'll realize that its attention to detail and instruction following are unmatched.
youtube.com/watch?v=ELwb_emN…
