
Audio @HuggingFace | PhD @EPFL | prev @Sonos @snips @DSPConcepts @Fraunhofer_IDMT
Joined July 2018
- Tweets181
- Following227
- Followers444
- Likes614




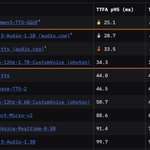
🗣️ Open TTS Leaderboard updates!
> 14 new languages via the @MiniMax_AI multilingual eval set. thanks @realmrfakename for helping with the integration 🙏
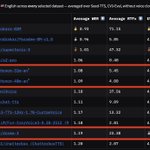
> NEW models: LFM3-Audio-2B by @liquidai and maya2-native by @mayaresearch_ai
> audio.cpp streaming backends for 8 models, thanks @0xShug0 ⚡️


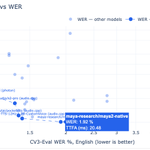
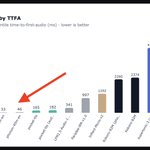
maya2-native by @mayaresearch_ai is built for speed: lowest TTFA on A100 (19.1 ms p50 / 20.5 ms p95), and it sits on the Pareto frontier of both speed-vs-WER plots.
It covers English and 11 Indic languages.


audio.cpp (C++/ggml) establishes itself on the streaming eval 👏 kudos to @0xShug0!
On both H200 and A100, it takes 3 of the top 5 spots.


Eric Bezzam retweeted

Probably the most impactful ASR release of 2026.
#1 open-weight model on the Open ASR Leaderboard.
Supported day0 in 🤗 Transformers

Meet NVIDIA Nemotron 3.5 Transcribe 🎙️
An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint.
Watch it keep track of who said what when everyone’s talking at once.
1/ 🧵
BEAST of a model (30B, 4B active) with stellar results on the Open ASR Leaderboard!
> #1 among open models on English, #9 overall
> #1 among open models on multilingual 🇩🇪🇫🇷🇮🇹🇪🇸🇵🇹🇮🇳🇳🇱, #6 overall
Open weights: huggingface.co/nvidia/NVIDIA…
Leaderboard: huggingface.co/spaces/hf-aud…
Demo: huggingface.co/spaces/smolag…
Eric Bezzam retweeted

One of the biggest changes in the history of 🤗 Transformers audio is in the works, spearheaded by @eustachelb
We’re rebuilding essentially the entire audio preprocessing stack.
The goal is to move away from every model carrying its own `FeatureExtractor` implementation, and towards a common `AudioProcessor` architecture where models describe their frontend, while shared backends handle the actual computation.
The stack currently covers ~30 audio frontends and 62 model mappings across Whisper, Wav2Vec2, Parakeet, SeamlessM4T, Qwen, Gemma, codecs, TTS models,and many others.
A big part of the work is making backends explicit:
`backend="torch"` → native PyTorch preprocessing (often super fast!)
`backend="numpy"` → portable NumPy preprocessing
That means audio preprocessing can increasingly live in the same framework as the model itself, while still keeping compatibility with the numerical behavior existing checkpoints expect.
It also gives us a much better foundation for what comes next: new hardware backends, faster kernels, compilation, and optimizations that can benefit many audio models at once instead of being implemented model by model.
~30 frontends migrated.
62 model mappings.
One common preprocessing architecture.
The entrypoint, common across all architectures:
`AutoAudioProcessor.from_pretrained(...)`
Audio in Transformers is about to get a much stronger foundation!
🎧🎧🎧

Open TTS Leaderboard updates 🗣️
> A 31M and a 35B model were added: phonon by @gradium and Drama-3 by @FishAudio. ~1000× apart in size, similar English WER (1.08 vs 1.19)
> New metric: UTMOS, for naturalness of English outputs. Thanks @realmrfakename!
🧵

These recent releases present two interesting "philosophies" for designing TTS systems:
> Drama-3: one 35B model, 83 languages, built-in voice cloning, and the 2nd-best UTMOS (4.47)
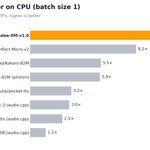
> Phonon: small per-language models, 102 preset voices across 5 languages, built for CPU
Both are needed!
Phonon-31m-en: huggingface.co/gradium/phono…
Phonon voices: huggingface.co/gradium/phono…
Drama-3: huggingface.co/fishaudio/dra…
Leaderboard: huggingface.co/spaces/hf-aud…

Eric Bezzam retweeted

Phonon weights are on the @huggingface Hub, with support in Transformers, and pip install speech-to-speech runs it locally from day 0. Thanks @julien_c @eustachelb @andimarafioti @mervenoyann and team. huggingface.co/gradium/phono…
Open TTS Leaderboard updates 🗣️
> Paradee-8M by @sahilmdkr, distilled from Kokoro-82M: same WER at 1/10 the params
> Now evaluating streaming engines audio.cpp (@0xShug0 ) & photon (@vikhyatk), great for voice agents 🤖
> Eval scripts now open-source ⭐️
🧵

audio.cpp and photon bring low-latency streaming to open models: under 35 ms p50 / 35 ms p95 time-to-first-audio on A100.
Check them out if you're building voice agents 🤖

Leaderboard: huggingface.co/spaces/hf-aud…
Eval code: github.com/huggingface/open-…
Paradee-8M: huggingface.co/sahilmahendra…
Another week, another shift in the Open ASR Pareto front 🚀
IBM granite reclaims the podium for fastest models ⚡
More leaderboard updates in the 🧵 including efficient Whisper and Parakeet fine-tunes and a new language 🇦🇲


Super-quantized Parakeet fine-tune (164MB download) by @yoitsmanan lands on the leaderboard
