

AI silicon, co-designed with the models it runs. First up: the frontier model's co-processor. Only the math.
Joined October 2026
- Tweets2
- Following0
- Followers248
- Likes0
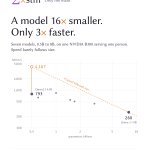

A model 16x smaller. Only 3x faster.
That's what we measured on an NVIDIA B300 serving a single user.
Frontier models get most of the attention, but the smaller models working around them increasingly determine how long users wait.
They draft tokens, screen prompts, route requests, and power multi-step agents. Each operates in the critical path of inference.
Yet they're running on hardware primarily optimized for much larger models and higher throughput.
We think these workloads deserve silicon of their own.
Today, we're kicking off an eight-part technical series exploring the research and engineering behind Exstill, from GPU inference bottlenecks to ML–silicon co-design and our first co-processor.
Part 1: The work around the frontier model.
exstill.ai/posts/01-the-work…

We're coming out of stealth.
The limits of AI compute are inherited, not fundamental.
At Exstill, we're designing AI models and silicon together to push inference efficiency toward its limits.
Our first step: the frontier model's co-processor.
Founded by Valavan Manohararajah and Vithu Thangarasa (@vithursant19), we've been building toward this moment for a while, and we're excited to finally share what we've been working on.
We're just getting started.
Explore what we're building: exstill.ai