

AI in Public 🛠️ | ex @SentinelOne 1st SRE Go Team & @Comcast VIPER Startup | Building : Strix Halo / R9700 K8S Cluster for Compound AI Systems
🏔 DENVER 🏔
Joined September 2016
- Tweets2K
- Following287
- Followers1.2K
- Likes35K



Pinned Tweet
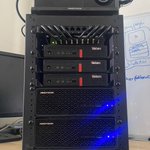
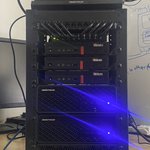
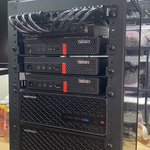
Spent all weekend orchestrating models across both the 2x Strix Halo 128GB APUs and AMD R9700 32GB VRAM GPUs in my home k8s Compound AI System Homelab.
Can't want to show you the AI / Software side of what I am building.


Philip kiely's @baseten "Inference Engineering"
Kept losing my spot in the free PDF of this book online, so bought the book.
I think it offers some great glue and goes deep in other areas you didn't consider if already AI inference obsessed.
As a bonus, don't miss the Inference focused optimization research papers linked in the back.

Check out this build :

The RTX PRO 4500 Blackwell deserves more attention, it’s basically a 5090 with half the bandwidth and cores.
32GB VRAM, 896GB/s bandwidth, and just 200W in a dual-slot blower design
I managed 153 tok/s on Qwen3.8-27B with TensorFold, ~54% of the latest 5090 leaderboard result, with potentially more headroom.
For me it was a good option because as you can see my existing build couldn’t handle the large size or power draw of a 5090. Also it’s the same Blackwell architecture so basically anything that runs on a 5090 runs on the 4500 without major changes.
Since 5090s have exploded in price you can sometimes get the RTX PRO 4500 for less than half the price of an RTX 5090

This is the exact reason I love both Nemotron ( also Poolside models ) for engineering.
No need for personality as it is only extra fluff. The lack of wordiness of these models is great for engineering
Personality maybe better for consumer computer use agents or customer service bots .

Ryan Wright retweeted

Hearing the creator of Mario, Shigeru Miyamoto, say that the Typerwriter to Word Processor is the equilivent of Generative AI and is part of technological human evolution is probably one of the best statements of 2026.
It will not make human creativity obsolete
Human intention and individual visions will become even more important
Nvidia’s Nemotron 3.5 Super VL 120B just showed up in the docs
• 12B active
• hybrid Mamba-Transformer
• MOE
• Image and video
• Text version
Huggingface is hitting 404 ... for now.
docs.nvidia.com/nemo/automod…

1st Asus AI PRO R9700 32GB VRAM AMD GPU added for full duplex voice and vision tasks in the Strix halo k8s Compound AI System HomeLab.
What a pain to get this working.
Full write up when I am done.

Cloudflare drops a faster and better Jev-like decision model.
<> Multimodal: text, json, images & video
<> Extreme speed: structured output returns probabilities, confidence scores, or yes/no answers
<> Top benchmarks: scores highest on 7 of 10 decision-making benchmarks, beating other open models
<> Drop-in replacement for Jev
Clef outputs a structured probability for every allowed answer.
It skips text generation entirely instead of writing a response, it directly scores answers (yes/no, options, or ratings).
That means base Clef is 2.5x faster than Jev. Clef-flash is up to 13x faster, making decisions in milliseconds.
Open-sourced under Apache 2.0 on Hugging Face. Download, run, and modify locally.
Blog: blog.cloudflare.com/clef-dec…
🤗 Model: huggingface.co/Cloudflare/cl…

AMD Ryzen systems using integrated graphics (iGPUs) are getting a boost:
AMD Boosting AI/LLM Performance For Radeon iGPUs As Much As 18~23% With Linux 7.4 (due late 2026)
How It Works: AMD IOMMU Performance Optimization (PerfOpt) bypasses IOMMU overhead when the system directly accesses memory.
🤯
phoronix.com/review/amd-perf…

AI built its own chip-design / GPU kernel coding model that beats the giants. Small and focused is winning.
It made iCoder-27B a small LLM model that beats GPT-5.5, Claude Opus 4.8, and Gemini 3.5 Flash at writing chip-design code (RTLLM) and fast GPU math code (KernelBench)
How? Researchers gave an agent one job: train a new AI model, start to finish.
TL;DR:
Humans wrote the rules goals, checks, limits. Then let the AI run the whole training run by itself.
Here's what happened:
1. The agent picked problems, trained a 27B model on ones it could verify were correct, then kept improving via trial, error, and feedback.
2. When training broke the model gaming its own rewards, bad data creeping in the agent found and fixed it alone. No human help.
3. Result: #1 on RTLLM (chip design, beating GPT-5.5), #2 on two other coding tests, and it ties Claude Opus 4.8 on GPU-kernel code.
4. It even beats DeepSeek-V4-Pro a model ~60x its size at chip design.
Why it matters: a small specialist model, trained by an AI, now beats trillion-parameter generalists at any job where work can be auto-checked. Small and focused is winning.
Paper: arxiv.org/abs/2609.29626


The open-source community has been actively attempting to replicate TypeSafe AI's "Jev" at record speed, so much so that JevBench was created to track the speed, accuracy, intelligence , etc of each one.
if you guys liked Jev , but want to run open source. I suggest you check JevBench.
What is Jev?
"Jev models function as fast decision engines that instantly output precise probabilities and structured choices like routing or scoring instead of generating text word-by-word.
By bypassing open-ended text generation, they operate up to 200 times faster and over 100 times cheaper than normal LLM. While they cannot replace a genAI model's reasoning or content creation, they replace the frequent, high-volume workflow steps like data triage, tool selection, and automated verification checks."
benchmarkheaven.com/jev-mode…

Jev lovers , check this out 👉
Weights are published on huggingface

Faster than Jev, existed a year before Jev, and open source + open weights
laya.convaiinnovations.com/
People talk down about @poolsideai Laguna S2.1 118B , but it's amazing when tuned for bench & IQ. There is nothing wrong with it I actually loved it over qwen-coder-next.
It has a prose between the wordy Nvidia Super 120B and the info dense Coder-next 80B which made it perfect for me out of the box.
I also love its "behaviors" over coder-next. Much cleaner code due to the way the model edits the file. We talk about benches , but hardly ever the behaviors of the model.

All weekend, I’ve been reading about AI labs complaining that the Chinese are distilling US models. I have a personal story to share.
I recently posted a /photos url and tons of photos on my family website for 1 family member and OpenAI fuzzed the endpoint & crawled the endpoints within 36 hours.
I only sent the link to the 1 family member!
It’s in the logs. The WHOIS calls out their servers. They don’t even try and hide it.
Speaking of, do you care bout the Chinese distilling "OpenAI's" data?
A 4B parameter model just beat a 32B monolithic model on the GAIA multi-agent benchmark.
Researchers tested Qwen3 models (4B to 32B) to see if small, tool-augmented agents could punch above their weight class against larger scale models.
TL;DR:
Giving tiny models access to tools creates massive performance boosts. A 4B tool-using model can easily outperform a 32B model without tools, but forcing small models to "think" too much actually breaks their tool execution.
Here is what they did:
1. They equipped a single backbone model with a Web-Search Agent, Coding Agent, and Mind-Map Agent, dynamically swapping roles via system prompts to save VRAM.
2. They proved tools beat pure scale: A 4B-Instruct model with tools hit 18.18% accuracy, beating a 32B model without tools (12.73%).
3. They discovered that "Full Thinking" often degrades tiny models by causing infinite tool loops or skipped steps. For agentic setups on small models, Planner-only thinking is much more reliable.
Paper: arxiv.org/html/2601.11327v1

First of all, there is no Local AI vs AI Labs, only frontier models Labs and their friends against Local AI.
This week was proof of the AI Lab privacy problem showing how both methods have their pros & cons.
Researcher Tristan Buckmaster claims OpenAI scooped his team's breakthrough using his exact methods after they used OpenAI tools during research.
How many industries have leaked secrets to AI labs?
