

Fan of high nat/flop ratios.
Joined May 2020
- Tweets42
- Following62
- Followers347
- Likes13
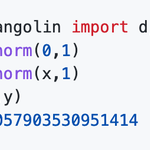



So I wrote a library to do Bayesian inference using a notation as close to mathematical notation as possible: github.com/justindomke/pango…


Justin Domke retweeted

Excited to share this retrospective of papers shown at ML conferences in 2021 by folks from @umasscs including several #NeurIPS2021 papers: all.cs.umass.edu/ML2021.html #UMassML21
Justin Domke retweeted

Hark, Bayesians! Everyone's favorite approximate inference symposium is back! The submission deadline is November 19th, so send us all your recent work on approximate Bayesian inference. Please share, retweet, and tell all your friends:
approximateinference.org/cal…

Turning confidence sets into confidence intervals.
(Or how you could accidentally invent the clopper-pearson interval without math using visualization and greedy choices.)
justindomke.wordpress.com/20…


my attempt to *really* explain confidence intervals without math by discretizing everything
justindomke.wordpress.com/20…


The replication game: try to predict which psychological effects replicate
justindomke.wordpress.com/20…


gaussian process regression vs. printing out your data and drawing a bunch of curves on top of it by hand
justindomke.wordpress.com/20…


Just finished teaching a graphical models course. This was definitely my favorite result. ("Look at probabilities and utilities working together in harmony!") But somehow, the proof is too easy to be satisfying...

I think this paper is basically doing distillation of a model learned by a dog's brain into a machine learning model.
(What's the inductive bias that dogs use to generalize so well?)
journals.plos.org/plosone/ar…

Justin Domke retweeted

In the third #AABI2020 session on Wednesday, Jan 27, Justin Domke will present "Some Embarrassing Questions about Variational Inference". Register at us02web.zoom.us/webinar/regi… or watch our Youtube Livestream at youtube.com/channel/UCZLWLfZ…
The Flat Earth Society has disconcertingly good information on Symplectic Integrators.
wiki.tfes.org/Symplectic_Int…
For general Bayesian inference, how good is:
Laplace init? Meh
IW training? Meh
IW sampling? Good
STL gradient estimator? Good
Normalizing flows: Really good
Careful step size? Really, really, really good proceedings.neurips.cc/paper… #NeurIPS2020

Want faster variational inference? You can use a Taylor expansion, but this only works for mean-field.
We tried something "dumb" for other dists: Just optimize a quadratic online. Surprisingly, this might be better anyway. #NeurIPS2020 papers.nips.cc/paper/2020/fi…

Calculating variance in the log domain justindomke.wordpress.com/20… (I'm sure a better solution than this was known decades ago... let me know if you know what it is!)

Back to Basics: Approximate Bayesian Computation -- justindomke.wordpress.com/20…