

KAYTUS is a provider of IT infrastructure products and solutions, delivering a variety of cutting-edge, open, and green infrastructure products.
Singapore
Joined June 2023
- Tweets446
- Following22
- Followers641
- Likes39




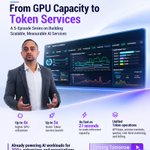


For AI Factories delivering inference services, fluctuating demand creates a tough balancing act: how do you maintain fast response times without overprovisioning expensive GPU resources?
MotusAI makes inference more adaptive with intelligent autoscaling and flexible prefill/decode deployment.
⚡ 21s — Fastest capacity scaling in testing
✅ 100% — Request success rate throughout the test
Handle traffic spikes without overprovisioning. Deliver reliable inference at a more efficient cost.
▶️ Watch how MotusAI handles the peaks!
#KAYTUS #MotusAI #AIFactory #AIInference
9
Building the Future of AI Infrastructure—Together!
Great conversations. Stronger partnerships. New opportunities for AI innovation.
On 11 November 2026, KAYTUS brought together partners from across the UK & Ireland at London's iconic Stationers' Hall for K-Connect UK & Ireland—an afternoon of insights, innovation, and collaboration.
We showcased our end-to-end AI infrastructure solutions, designed to turn complex infrastructure projects from blueprint to reality.
A special thanks to Glenn Rosenberg from BIOS IT, and Arun Tyagi and Joseph B. Ball from Define Tech Ltd. for sharing their partnership experiences, market insights, and practical perspectives. Their insights highlighted how strong partnerships and joint solutions deliver meaningful value to customers.
Together, let's unlock new opportunities and accelerate AI infrastructure growth across the UK & Ireland!


1
63
🚀 Beyond More GPUs. Make Every GPU Count.
Scaling clusters is one thing—turning massive power into real-world efficiency is another. At #SC26, see how KAYTUS full-stack innovations maximize your AI ROI:
⚡ Deploy at Scale: Megawatt-scale Prefabricated AIDC & AI Computing Pods built for rapid, high-density rollout.
💧 Cool & Compute Efficiently: K24 liquid-cooled racks and next-gen accelerated platforms that push performance per watt.
🧠 Eliminate Idle Capacity: Intelligent orchestration via MotusAI, KSManage & BCS + PodSys to keep every GPU productive.
🔬 Get More from Every FLOP: Optimized HPC & AI4S solutions to fast-track scientific discovery.
🔥 First Look: Meet our next-gen KR2190V4 server at the booth!
📍 Nov 17–19 | McCormick Place, Chicago | KAYTUS Booth #2211
🤝 Don't just scale up—scale smarter. DM us to schedule a 1-on-1 with our experts!
#KAYTUS #SC26 #AIInfrastructure #HPC #LiquidCooling #DataCenter
🤖 Made with AI

1
42
🚀 Your AI model is ready. But how long does it take to get into production? Disconnected tools, manual handoffs, and complex deployment processes can slow down AI innovation.
🔗 See how MotusAI connects development, training, model management, and deployment in one seamless workflow—turning days of deployment work into minutes.
⚡ Less complexity. Faster deployment. Bring AI models to production with confidence.
Watch now!
1
49
Idle GPUs. Waiting workloads. Sound familiar in your AI Factory?
As AI workloads grow, fragmented resources, resource contention, and inefficient scheduling can leave valuable GPU capacity underutilized.
See how MotusAI brings GPU resources together—enabling fine-grained sharing, intelligent scheduling, and up to 4× better resource utilization in benchmark tests.
Less idle capacity. More productive GPUs. Make every GPU count.
Watch now!
#KAYTUS #MotusAI #AIFactory #GPUOrchestration
AI infrastructure is an investment. How fast it delivers value matters. ⚡
Prefabricated AI data centers are drawing attention at GTC Berlin. The conversation is shifting from deployment speed alone to the business value that speed creates..
In a recent interview with Manage IT, Darren Cox, GM of KAYTUS Europe, explained why speed is critical to achieving efficient ROI. Many customers are still figuring out how to turn AI investments into a viable business model—and how to get there.
He explained that KAYTUS addresses this with factory prefabrication and deep system integration. This approach reduces on-site complexity, shortens deployment cycles, and gets infrastructure operational sooner.
🎥 Watch the interview to get more:
ap-verlag.de/techtalk-ki-im-…

1
54
More GPUs. More AI workloads. But is your AI Factory delivering more value?
Idle GPUs, fragmented workflows, and complex Token operations can hold back AI service delivery.
See how MotusAI connects the dots—improving resource efficiency, accelerating deployment, and turning GPU capacity into scalable Token services.
From GPU capacity to Token services. Unlock the full value of your AI Factory.
Watch now!
#KAYTUS #MotusAI #AIFactory #TokenServices
More GPUs, more AI workloads. But are you ready to deliver Token services at scale?
Idle GPUs, fragmented AI workflows, unpredictable inference demand, and growing challenges in managing Token usage and costs.
Turning GPU infrastructure into scalable, manageable Token services takes more than compute.
Coming soon: our new MotusAI videos, exploring how to bring GPU orchestration, AI workflows, inference, and Token service operations together on one platform.
What to expect:
⚡ How can smarter GPU sharing boost utilization by up to 4×?
🚀 From code to production, what does it take to launch Token services up to 5× faster?
⏱️ When inference demand spikes, see how intelligent autoscaling keeps services responsive
🔑 How do you turn GPU capacity into secure, metered, and billable Token services?
Already trusted by 300+ enterprises and organizations
From GPU infrastructure to Token services. That's MotusAI.
Stay tuned!
#KAYTUS #MotusAI #TokenAsAService #AIInfrastructure

1
48
Prefabricated, containerized AIDC is in the spotlight at GTC Berlin — offering a faster path to high-density AI deployment. ⚡
KAYTUS delivers a one-stop, end-to-end AIDC solution, with single-vendor accountability from planning and design to deployment and operations.
🏗️ Up to 90% Factory Prefabrication: Three standardized modules integrate IT, power and cooling, pre-tested before delivery.
⚡ Faster Deployment: 6–8 months from design to commissioning, versus 18–24 months for conventional builds.
📈 Flexible Scaling: From a 3MW base unit to 1GW AI Factory deployments.
🔧 Intelligent Operations: KSManage unifies IT and facility management, with AI-driven energy optimization and intelligent leak protection.
Build faster. Scale smarter. Power AI forward.
See how KAYTUS is building the next generation of AI infrastructure.
#KAYTUS #AIDC #AIFactory #AIInfrastructure #PrefabricatedDataCenter
2
105
Your workloads shouldn't be limited by your server platform. 🚀
Meet the KAYTUS KR2280V3 — a versatile 2U server designed for general-purpose computing, HPC, all-flash storage, and AI workloads.
Engineered for flexibility and efficiency, it features:
🧠 CXL Memory Expansion: Supports a self-developed CXL memory adapter, adding up to 16 additional DDR4 DIMMs.
⚡ Efficient Power Design: A proprietary GaN Titanium PSU delivers enhanced power efficiency.
🔧 Front I/O Design: Built to support storage-intensive configurations.
One platform. Multiple workloads. That's the KR2280V3.
Follow KAYTUS for more.
#KAYTUS #KR2280V3 #CXL #ServerInfrastructure #AIInfrastructure
1
63
At Tech Week 2026 Singapore, Alex from KAYTUS showcased MotusAI in action—bringing GPU resource monitoring and utilization trends into one unified view.
For enterprises, MotusAI supports the journey from AI development and model pipelines to online inference. For neoclouds, multi-tenancy and API packaging help turn GPU capacity into Token-as-a-Service opportunities.
Turn your GPUs into AI capability, and your models into revenue. That's MotusAI.
Talk to KAYTUS to explore MotusAI.
#KAYTUS #MotusAI #AIInfrastructure #TokenAsAService
3
46
What turns high compute density into real capacity for AI agents at scale?
The answer goes beyond core counts. It takes an architecture designed for high concurrency, energy efficiency, and continuous operation.
KAYTUS K24 brings together up to 80 nodes and 46,080 cores in a single rack, with cold-plate liquid cooling designed for efficient, low-PUE operation.
Purpose-built for large-scale AI agent workloads, K24 supports up to 1,000 independent AI agent instances running concurrently on a single system, with an architecture engineered for stable, continuous operation.
More than density. Built for AI agents at scale.
#KAYTUS #K24 #AIInfrastructure #AIAgents #LiquidCooling
🤖 Made with AI

1
60
🎬 KAYTUS Tech Spotlight | K24
Up to 1,000 concurrent AI agent instances. One rack. How does KAYTUS K24 make it possible?
In this episode of #KAYTUSTechSpotlight, our sales representative May Koay introduces the K24 on-site in Singapore—a high-density, liquid-cooled rack system built for large-scale AI agent workloads.
Three key highlights:
⚡ High Density: Up to 80 nodes and 46,080 cores in a single rack.
💧 Efficient Cooling: Cold-plate liquid cooling designed to improve energy efficiency and support low-PUE operations.
🔄 Agent-Scale Reliability: Support for up to 1,000 concurrent AI agent instances, with an architecture engineered for continuous workloads.
Watch May break it down! 🎤
#KAYTUS #K24 #AIInfrastructure #AIAgents #LiquidCooling
1
1
52
Hardware repairs in as little as 4 hours. 30%+ less recovery time.
Introducing KAYTUS AI Managed Service—bringing OEM expertise and repairs directly onsite.
At a global CSP, KAYTUS AI Managed Service reduced average incident handling time from 48h to 12h per failed node.
Less downtime. More productive compute.
🤖 Made with AI

1
60
Great conversations, fresh perspectives, and new opportunities for AI infrastructure in Barcelona! 🌍
On October 6, alongside our participation in an EMEA industry summit, KAYTUS hosted its EMEA Channel Partner Reception, bringing together industry analysts, channel partners, and business leaders to exchange insights and explore opportunities across the region.
The event featured insights from Alastair Edwards, Chief Analyst at Omdia, on EMEA market trends, followed by discussions on KAYTUS' regional strategy, channel initiatives, and partner ecosystem development.
A big thank you to everyone who joined us! We look forward to strengthening partnerships, expanding our EMEA presence, and driving growth in AI infrastructure together.
#KAYTUS #AIInfrastructure #EMEA #KAYTUSPartners #Barcelona #WinningTogether


1
84
Advancing the Future of HPC & AI at the International HPC User Forum in Stuttgart!
We are proud to serve as a key sponsor and presenter at the 93rd HPC User Forum held at HLRS, University of Stuttgart!
Our AI & HPC expert, Dr. Di Wang, delivered a speech titled "ScienceMate: Agent for Science — A research-native agent platform for long-horizon science on HPC". He shared how AI agents can break through traditional execution barriers to empower long-term, verifiable scientific discoveries on HPC clusters.
At the KAYTUS booth, we highlighted our latest IT end-to-end liquid-cooling and AI infrastructure solutions.
Thank you to all the researchers, partners, and HPC community members who connected with us in Stuttgart! Let’s keep driving scientific computing forward together.
#HPCUserForum #HPC #AIforScience #LiquidCooling #KAYTUS #Supercomputing #AIInfrastructure #HLRS
🤖 Made with AI


2
79
The complexity of AI factory operations is soaring.
Rack-scale AI systems are becoming the mainstream architecture for AI Factories — integrating 100+ accelerators and thousands of high-speed interconnects into a unified infrastructure. Even a relatively low component-level incident rate translates into hundreds of operational events at cluster scale, making fault identification exponentially harder while manual operations fall further behind.
In our new KSManage video series, Alberto Stec, General Manager of KAYTUS UK&I, reveals how KSManage changes the game: enabling real-time monitoring of rack-scale AI systems across GPU, memory, PCIe status, liquid cooling, and power to rapidly pinpoint abnormal nodes and high-risk components before performance degrades or failures occur.
👉 Watch the final episode to see how KSManage makes AI factories efficiently manageable.
Agentic AI is moving into production—and enterprises need more than GPUs. They need secure, reliable, and cost-efficient token operations.
KAYTUS has upgraded MotusAI, its enterprise AI platform, to enable on-premises “Token Factories” that help enterprises deploy, govern, and scale AI agents while keeping sensitive data within their own infrastructure.
With improved GPU utilization and optimized token operations, enterprises can reduce annual token-related operating costs by 30%–50%.
Read the full article: kaytus.com/about/news/27711.…

1
84
A 1000-GPU AI cluster can consume as much energy as a community of 800-1000 residents. Are your energy bills climbing faster than your infrastructure?
You're not alone. Traditional operations keep physical and IT systems in silos — so even the most advanced liquid cooling can't deliver the efficiency gains you expect.
In our new KSManage video series, Alberto Stec, General Manager of KAYTUS UK&I, reveals how intelligent operations keep systems running in optimal efficiency ranges — reducing energy consumption by 15–20%.
Beyond energy savings, KSManage automates what used to take days: batch firmware upgrades and OS installations across thousands of devices simultaneously.
👉 Watch the fourth episode to see how KSManage turns manual overhead into automated efficiency.
See what’s next for AI infrastructure at #BigDataAIWorldAsia 2026.
KAYTUS will showcase prefabricated AIDC, high-density liquid cooling, end-to-end AI computing and intelligent resource management — built for faster deployment, higher density and greater efficiency.
📍Singapore | 29–30 Sep
1
83