

Redefining RAG for AI products and agents. Open-source data parsing and retrieval infrastructure by Ontos.
Joined September 2025
- Tweets56
- Following25
- Followers7
- Likes76




Knowhere retweeted

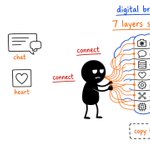
Everyone in AI is obsessing over memory right now, mostly because our models are still pretty dumb. You tell it something, open a new chat, and poof—it’s completely gone.
Funny thing is, brain surgeons saw this exact same thing 70 years ago.
Back in 1953, a patient had his hippocampus removed during a rare surgery. After that, he literally couldn't form new memories at all. He was just stuck in 1953 forever.
That was when people finally realized: human memory isn't just one big thing. It has layers. Different parts handle different jobs, and if you take one piece out, you lose that whole ability and the rest of the brain can't work together anymore.
The AI we have today is basically that patient.
Everything we're doing right now is just copying biology—trying to give AI those missing layers of memory so it can actually remember things.
Put together a quick piece on this 👇:
medium.com/@13512395620/ais-…

Knowhere retweeted
Hot take:
Most AI teams don't have a model problem.
They have a context problem.
And many context problems are actually document problems in disguise.
The industry is busy talking about Context Engineering, Agentic RAG, MCP, and multi-agent systems. But if your PDFs are parsed poorly, you're building on a shaky foundation.
A practical comparison of Reducto, LlamaIndex, Unstructured, MinerU, and Knowhere for anyone building production AI systems.
medium.com/@13512395620/how-…
🤖 Made with AI

Knowhere retweeted
Honestly, this started from a pretty simple ask in the comments:
“Can I just hook Knowhere into my own agent?”
Fair question. We were already parsing messy docs well — but if that knowledge only lived in the browser, it felt half-finished.
So we shipped Notebook + MCP.🚀
Now the docs you keep in Knowhere can show up in Cursor / Claude Code / Codex. Same account, same cloud store. Agent can search it; with Full access it can also parse new stuff back into the Brain.
Still early, but this is the direction that makes sense to me.
medium.com/p/knowhere-can-no…

Knowhere retweeted
After building RAG systems for the past year, I've come to a somewhat controversial conclusion:
90% of the work has nothing to do with the model.
If I had to break down where engineering time actually goes, it would look something like this:
📍50% Evaluation
📍40% Data curation
📍8% Business integration
📍2% Model training
The biggest failures I've seen weren't caused by weak LLMs. They came from outdated documents, missing metadata, broken chunking, poor retrieval, and a lack of clear evaluation criteria.
Swapping models is easy.
Building a system that knows which document is valid, who it applies to, and when it became effective is the hard part.
This realization has fundamentally changed how we build AI infrastructure.
The goal isn't just to retrieve text—it's to preserve the structure, context, and provenance that make knowledge reliable in the first place.
Curious whether others building production RAG systems have reached the same conclusion.
medium.com/p/does-90-of-a-ra…

Knowhere retweeted

Ingests unstructured documents to build navigable agent memory
github.com/Ontos-AI/knowhere

Knowhere retweeted
Many AI developers believe that hallucinations are entirely the model's fault, leaving them to passively wait for the next LLM upgrade. We strongly disagree.
In fact, a significant portion of hallucinations stems from fragmented information that forces the AI into blind reasoning. By simply changing how we parse documents, we can drastically mitigate this issue.
This is exactly why we built Knowhere. Unlike traditional RAG systems, Knowhere takes a fundamentally different parsing path. It maximizes the preservation of document structure and hierarchy. By providing rich, intact contextual information, it prevents the AI from blind guessing—thereby reducing hallucinations, improving response accuracy, and lowering token consumption.
According to our benchmark tests, compared to traditional RAG or raw documents, using document memory processed by Knowhere improves the AI Agent's response accuracy by 26% (jumping from 53% to 79%)!
If you are building enterprise Q&A systems, knowledge bases, or Agent applications in vertical sectors like finance, law, and healthcare, you should definitely give Knowhere a try.
It is now fully open source:
👉 github.com/Ontos-AI/knowhere
#AI #GenerativeAI #RAG #AIAgents #DataEngineering #OpenSource #Knowhere #EnterpriseAI
Know more about how it works:
👉medium.com/p/ai-hallucinatio…
Knowhere retweeted
We’ve been building in stealth, obsessed with one problem: How to give AI agents better memory without breaking the bank.
Today, we are finally open-sourcing our core framework: Knowhere. 🔓
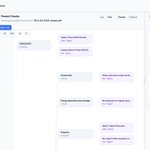
From 1.0 release to our new Tree-like chunking, it's been a wild ride. If you're building RAG systems and tired of noisy context windows, this is for you.
✅️50% token reduction
✅️Higher precision
✅️100% Open Source
Drop a ⭐ on GitHub if you’re a fan of efficient AI!
🔗github.com/Ontos-AI/knowhere
#BuildInPublic #AIStartup #OpenSource #RAG
Knowhere retweeted
I’ve been waiting for this day. 🚀
Knowhere is officially OPEN SOURCE!
Since we launched v1.0, the goal has always been to make AI-driven data structuring seamless. Now, we’re opening the hood. We want you—the builders, the hackers, and the visionaries—to help us shape the future of how AI interacts with information.
Whether you want to build on top of our API or contribute to the core, come say hi in the repo!
Let’s build something massive together. 🛠️
🌟 GitHub (Drop a star!): github.com/Ontos-AI/knowhere
🌐 Try the Web App: knowhereto.ai/?utm_source=x
🔗 Live Playground: notebook.knowhereto.ai
#BuildInPublic #OpenSource #AI #LLMs #DevCommunity
More introduction:
medium.com/p/after-months-of…

Knowhere retweeted
Honestly, AI is "smart" until you ask it to fill out a complex form. Then it’s a disaster. 📉
If you’ve ever tried to make an LLM handle multi-level tables, you know the pain. It swaps cells, hallucinates numbers, and has zero "spatial common sense." To a standard AI, a PDF is just a messy string of text—it can't actually see the boxes.
I got tired of the manual cleanup, so I built SnapFill.
I wanted to give AI actual "eyes" for layouts. Instead of guessing, it maps data with physical precision across PDFs, Excel, and Word.
What used to take me 30 mins of mind-numbing copy-pasting now takes about 5. It’s been a lifesaver for things like visa apps and audits where you can't afford to be "mostly" right.
If you're still doing "caveman" data entry in 2026, you’re doing it wrong. Give your AI some vision: 🔗gosnapfill.cn/landing?utm_so…
#AI #BuildInPublic #Productivity #SaaS #SnapFill

Knowhere retweeted

AI has evolved, but form filling is still stuck in the past. Why?
Traditional LLMs are great at text, but they’re "spatially blind." They read words but miss the structure—leading to scrambled cells, swapped data, and the dreaded "hallucination" in complex PDFs.
SnapFill is changing the game. We’ve moved beyond simple text processing to introduce Layout-Aware AI. By combining proprietary table algorithms with advanced document parsing, SnapFill doesn't just read—it sees.
✅Physical Precision: High-accuracy mapping for PDF, Word, Excel, and PPT.
✅Traceable Data: 100% verifiable results, eliminating AI guesswork.
✅Persistent Memory: Build your own knowledge base. Fill once, automate forever.
From visa applications to financial audits, we’re helping teams turn 30-minute manual tasks into 5-minute automated wins.
Stop doing manual work in the age of intelligence. Experience the precision of SnapFill: 🔗gosnapfill.cn/landing?utm_so…
#DocumentAI #Automation #Productivity #SnapFill #FinTech #FutureOfWork

Knowhere retweeted
Saw this post describing a real need for anyone drowning in paperwork: an AI Agent for "Word in, Word out."
The pain is: endless hours turning background docs into perfectly formatted Word templates. The backaches, the dry eyes... we get it.
Your dream AI Agent is our SnapFill

Knowhere retweeted

Come play with Memories.ai while you wait for visual memory with unlimited context.

