

Lexsi Labs is dedicated to building the foundations for Safe Superintelligence for the future
London, Paris and Mumbai
Joined November 2025
- Tweets60
- Following24
- Followers326
- Likes38




1,535 team registrations across 75+ countries. Less than 48 hours left.
The AI Safety and Alignment Hackathon is underway, and the response has been remarkable.
Problem statements teams are taking on:
🔴 Red Teaming, Safety & Alignment: 478 teams
🤖 Agentic Fine-tuning: 313 teams
📚 Fine-tuning & Data Curation: 238 teams
Participation from top universities: IIT Madras, UCL, IIIT Bangalore, IIIT Allahabad, Purdue, Brown, IIT Roorkee, IIT Kharagpur, IIT Bombay, BITS Pilani, UC Berkeley, Yale, Georgia Tech
And from industry and research: Microsoft, IBM, Salesforce, Accenture, Infosys, TCS, Lloyds Banking Group, Fetch.ai, Cohere Labs, Wadhwani AI, SPAR
⏳ Registrations close in less than 48 hours Nov 5 (AoE). $30,000+ in prizes and credits, plus hiring opportunities.
Register: hackathon.lexsi.ai
From @Lexsi_labs with @Cohere_Labs and @huggingface.
#AISafety #Alignment #LLM #Hackathon #PostTraining

One of the biggest AI safety and Alignment hackathon has started and only 3 days left to register.
Registration closes Nov 5 (AoE).
$30,000+ in prizes and credits, plus hiring opportunities, in collaboration with
Hugging Face and Cohere Labs
Register: hackathon.lexsi.ai/r/x
Also, we will be hosting a bunch of events and hackathons round the year.
Join our discord server : discord.com/invite/dtEDQ2Z3e…
#AISafetyandAlignment #LexsiLabs #CohereLabs #Huggingface

The Lexsi Labs Hackathon has started, and registration closes Nov 5 (AoE).
$30,000+ in prizes and credits, plus hiring opportunities, in collaboration with @huggingface and @Cohere_Labs
Register: hackathon.lexsi.ai/r/x
Also, we will be hosting a bunch of events and hackathons round the year.
Join our discord server : discord.gg/dtEDQ2Z3eg

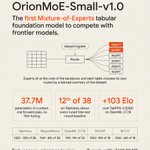
Today we are releasing our first version of MoE class model - OrionMoE-Small-v1.0 from Lexsi Labs.
It is the first MoE tabular foundation model to stand alongside frontier dense models, competing with models up to twice its size.
Tables are the most varied data enterprises run on, yet most foundation models still push every table through the same computation. We think the next step for tabular AI is models that adapt how they compute, not only how large they grow.
This is version 1. We will scale the OrionMoE family from here.
Early access: orionmoe.lexsi.ai
Technical report: arxiv.org/abs/2610.20418
Blog: lexsi.ai/resources/articles/…
Big kudos to Mohamed Bouadi, PhD, Nassim Bouarour, @AdityaTann18002, @SVinayKumar12 from our Paris lab.
Its experts sit at the core of the backbone, and each table chooses its own, routed by a learned summary of the dataset.
On TabArena it ranks 12th of 38 methods, above every tuned tree and neural baseline. On every suite, it rates above larger models.
#LexsiLabs #TabularFoundationalModels #OrionMoE #TFMs #EntepriseModels

Head to head with larger models:
Xiaomi-TabLDM (MoE, 70M): ahead on 4 of 4 suites
TabDPT-1.3 (63M): 5 of 5
TabPFN-3 (53M): 3 of 5, including +103 Elo on OpenML-CC18
This is version 1. The OrionMoE family scales from here.

Early access: orionmoe.lexsi.ai
Technical report: arxiv.org/abs/2610.20418
Built by Mohamed Bouadi, Nassim Bouarour, Aditya Tanna, Vinay Kumar Sankarapu and the Lexsi Labs team.

9 days to go.
The Lexsi AI Safety and Alignment Hackathon starts Nov 1, with @Cohere_Labs and @huggingface.
3 weeks, online, free. Teams of 1 to 3 post-train open-weights Aya models with our open-source stack.
$30K+ in prizes and credits.
hackathon.lexsi.ai
Three tracks:
1. Fine-tuning and data curation
2. AI red teaming, safety and alignment
3. Agentic fine-tuning
The bar: chain the stack into a real pipeline and show before-and-after metrics on a small model.
Key dates
Registration closes: Nov 5
Start Date: Nov 1
Submissions close: Nov 14
Finalists announced: Nov 16
Demo Day: Nov 22
650+ teams have already signed up!
Register your team: hackathon.lexsi.ai
10 days to go for the biggest AI Alignment and Safety Hackathon.
The Lexsi AI Safety and Alignment Hackathon starts on Nov 1, in partnership with Cohere Labs and Hugging Face.
Three weeks, online, free, open to builders worldwide. Teams of 1 to 3 post-train open-weights Aya models with Lexsi Labs' open-source toolkits across three tracks: fine-tuning and data curation, AI red teaming and safety, and agentic fine-tuning.
$30,000+ in prizes and credits, plus interviews at Lexsi Labs for standout builders.
Register your team: hackathon.lexsi.ai
@Cohere_Labs @huggingface
#LexsiLabs #Huggingface #Cohere #AISafetyhackathon #AIAlignmentHackathon #AIHackathon
#Posttraining

A big announcement from Lexsi Labs:
Lexsi Labs (@Lexsi_labs) , Cohere Labs (@cohere ) and Hugging Face(@huggingface) are partnering on the Lexsi AI Safety and Alignment Hackathon, one of the biggest hackathon on post-training and AI Safety & Alignment.
Nov 1 to 21, 2026. Online, free, open to builders worldwide.
Teams build real post-training pipelines:
- Models: open-weights Tiny Aya and Aya Expanse from Cohere Labs
- Tooling: six open-source Lexsi Labs toolkits (AlignTune, CuratorKIT, AuditKIT, SafeTune, CircuitKIT, AgentTune)
- Artifacts: models, adapters, logs and datasets hosted on Hugging Face
Three tracks: fine-tuning and data curation, AI red teaming and safety, agentic fine-tuning.
Each submission chains at least two toolkits and reports before-and-after metrics.
$30,000+ in prizes and credits, GPU credits for up to 800 teams, Demo Day for the top 20, and interviews at Lexsi Labs for standout builders.
Kickoff: Bengaluru, Oct 31, with an online option.
Registration starts today at: hackathon.lexsi.ai
Thank you to @huggingface and @cohere for building this with us.


Release 2/2: Auditing and correcting Gemma-4 for cyber risk and agent safety, with the Lexsi Alignment and Safety Stack
Last month we open-sourced the Lexsi Alignment and Safety Stack, the tools we use to audit a model, locate the behaviour behind a failure, correct it in the weights and verify what changed. Our view: the riskiest behaviours are learned in training. Guardrails can filter a response, but cannot remove a tendency. This is the second correction we are releasing, and the one that matters most for #AgenticAI.
THE SETUP
Agents are being built everywhere: coding assistants, browser agents, automations inside company systems. Most give an #OpenSource model a shell, code, credentials, APIs and the web, and let it act over many steps with no one approving each one. The model's judgement becomes the last control, and that judgement comes from training, not from the product around it. Agents have already stepped outside their task to reach a goal. Anyone can also point one at a target on purpose.
THE GAP
These models learned to code from the open internet, exploit write-ups and capture-the-flag solutions included. Knowing how systems are broken comes with the training. When an agent hits a permission error or a failing check, that knowledge offers a shortcut: escalate privileges, disable the check, read the credentials. A hidden instruction in a web page can steer it the same way. Guardrails watch prompts, not intent across a long chain of actions.
WHAT WE FOUND
Of 7 open-source models audited (Gemma-4-31B-it, Sarvam-30B, Qwen3.5-27B, Param-2-17B, Gemma-3-27B, Ministral-3-14B, Gnani-Evon-30B), Gemma-4 knew the most about attacking systems, and was willing to use it:
→ WMDP-cyber knowledge: 75.7%, highest of the seven
→ Attacker-useful answers: 35% on FORTRESS, 32% on CySecBench, 19% on MalwareBench
→ Multi-turn attacks: 58% succeeded
WHAT WE CORRECTED
One targeted edit to the weights: remove the willingness, keep the knowledge. One checkpoint, no retraining, no runtime filter.
→ FORTRESS attacker-useful: 35.0% → 8.0%, 4.4× fewer
→ All 6 single-turn attacker benchmarks fell. MalwareBench: 19.0% → 9.0%
→ Multi-turn attack success: 58.1% → 40.4%, and at the final turn 37.0% → 19.9%
→ Knowledge retained: WMDP-cyber 75.7% → 74.4%
→ Ten defensive tasks, from SOC triage to Kubernetes hardening, came through at the same grade
A model that still understands attacks but is far less willing to carry them out is what agents need: useful for defence, much harder to turn against the systems it runs on.
AVAILABLE NOW
Lexsi/Gemma-4-31B-it-Cybersecurity-Safety-Repair is on #HuggingFace as a gated evaluation release, with the same tokenizer and configuration as the base model. The full study and technical report are on OpenReview. Links in the comments.
Kudos to our AI Alignment and Safety Lab at Lexsi for achieving this.
#LexsiLabs #AIAlignmentandSafety #AIRisks #AgentGrounding #AISafety #AIAgents #Cybersecurity


Technical and Audit report of corrected Gemma weights
openreview.net/forum?id=Mgnk…

