



Junbang Liang retweeted

Everyone says they want general-purpose robots.
We actually mean it — and we’ll make it weird, creative, and fun along the way 😎
Recruiting PhD students to work on Computer Vision and Robotics @umdcs for Fall 2026 in the beautiful city of Washington DC!


Can visuomotor policy learn from video generation alone? We find learning to generate videos is an effective proxy with action-free video data providing critical benefits for generalizing to novel tasks! 🚀
Website: videopolicy.cs.columbia.edu/
Paper: arxiv.org/abs/2508.00795
This is joint work with @ptokmakov, @ruoshi_liu, @SruthiSudhakar2, Paarth Shah, @RaresAmbrus and @cvondrick. Please check out our website and paper for more results!
With video generation as a proxy for robot policy learning, Video Policy achieves the highest overall performance in the Libero10 benchmark compared to strong baselines.

We analyze 2-stage training compared to jointly training the video model and the action decoder. Notably, 2-stage training achieves significantly higher success rates, suggesting that video generation serves as a more general learning objective than action prediction.

We show generalization to unseen tasks using action-free video data. While both our action head and baseline DP train on 12 tasks (left), our video model trains on action-free videos from 12 tasks (right) and performs the tasks without action supervision training!

Video Policy takes an initial image and future noise vectors as input, then jointly denoise video frames and actions. The intermediate video features are used to condition the action decoder, enabling modular training and action-free learning through video generation alone.

Junbang Liang retweeted
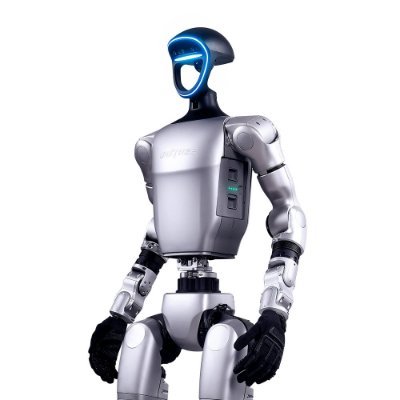
What Dance Would You Like to Perform with Unitree G1?
With the upgraded algorithm, G1 can learn any dance. Leave a comment to tell us what dance you'd like to see!😘
#Unitree #AGI #EmbodiedAI #SpringFestivalGalaRobot #AI #Humanoid #Bipedal #WorldModel #Dance
Junbang Liang retweeted

Happy to share our 2024 Christmas video starring a humanoid robot in new adventures! Happy holidays! #robotics #ai #humanoids #dexterity
Junbang Liang retweeted
How can a visuomotor policy learn from internet videos? We introduce Dreamitate, where a robot uses a fine-tuned video diffusion model to dream the future (top) and imitate the dream to accomplish a task (bottom).
website: dreamitate.cs.columbia.edu
paper: arxiv.org/abs/2406.16862