

Lilac manages private GPU clusters at scale.
San Francisco
Joined August 2025
- Tweets44
- Following21
- Followers136
- Likes57




Lilac retweeted

Join a small group of neoclouds and AI team executives for an invite-only cocktail party in San Francisco, CA, on November 12th.
We’ll have curated drinks, light bites, and good conversations.
🗓️ Thursday, November 12th | 6:30-9:30 PM
📍San Francisco, CA (location shared upon approval)
🤝 Hosted by @saturn_cloud and @LilacML
Spots are very limited. RSVP here: luma.com/0420zroa
#AIInfrastructure #Neoclouds #AIFactories #GPUCloud

Lilac retweeted
Join a small group of neoclouds and AI team executives for an invite-only cocktail party in San Francisco, CA, on November 5th.
We’ll have curated drinks, light bites, and good conversations.
🗓️ Thursday, November 5th | 6:30-9:30 PM
📍San Francisco, CA (location shared upon approval)
🤝 Hosted by @saturn_cloud and @LilacML
Spots are very limited. RSVP here: luma.com/0420zroa
#AIInfrastructure #Neoclouds #AIFactories #GPUCloud

Lilac now offers GPUs! B300s available in late November.
Contact us for details: [email protected]
Lilac retweeted
Saturn Cloud and @LilacML are partnering to bring enterprise GPU capacity into Saturn Cloud's token factory platform.
A lot of GPU capacity sits idle inside enterprises while inference teams are asked to reserve more hardware. It's already powered on and paid for, it just never reaches the teams who need it.
Lilac is now a GPU network provider for Saturn Cloud, connecting that unused capacity through an OpenAI-compatible API. Customers get more GPUs to serve models on without standing up new hardware, billed per token with no reserved commitments.
Built for operators who want to offer inference without carrying reserved GPUs, and enterprises serving models without a standing hardware commitment.
Read the full announcement: lnkd.in/gp5aF6BQ
Learn more at saturncloud.io
#GPU #Inference #AIInfrastructure #ModelServing

Lilac subs are live: fast GLM 5.2, Kimi K2.6, MiniMax M3, and Gemma 4 from $10/mo.
Included usage starts at $20 / $75 / $300 of PAYG value, and live capacity discounts can stretch it up to $80 / $300 / $1,200.
Details: docs.getlilac.com/billing/su…
Purchase at: console.getlilac.com/billing
🤖 Made with AI

Lilac retweeted

So happy to announce that @LilacML is now available on Eden AI!
Test Gemma 4, MiniMax M2.7, Kimi K2.6, and GLM-5.1 through one API, with 25% lower pricing across all Lilac models.
👉 app.edenai.run/playground

We're standing by for day 1 support!

the modular kernel team moving fast on M3 🚀
open weights dropping in a few days — then it runs on @Modular right away.
excited for this one.
Excited to share our partnership with @EdenAIco! Try Lilac at 25% discount this week using their unified API platform.
edenai.co/post/special-offer…
Very excited for M3!
Introducing MiniMax M3: The First Open-Weights Model to Combine Three Frontier Capabilities
- Coding & Agentic Frontier: 59.0% SWE-Bench Pro, 66.0% Terminal Bench 2.1, 34.8% SWE-fficiency, 28.8% KernelBench Hard, 74.2% MCP Atlas
- MiniMax Sparse Attention scales context to 1M
- Natively Multimodal from Step Zero
API: platform.minimax.io
Token Plan: platform.minimax.io/subscrib…
🚀New! MiniMax Code: code.minimax.io
Weights & Tech Report in ~10 Days

Lilac retweeted

Dreading your @AnthropicAI API bills? We just ran a benchmark of equivalent open source models on @LilacML and GLM 5.1 came on top even for the most tedious tasks.
Read our blogpost here.
100x.bot/a/Benchmarking-LLMs…
Folks at @LilacML are onto something!

Lilac retweeted

Introducing the Monastery for AI-native founders.
A single builder can now outperform a publicly traded company.
$2 million. 12 weeks. Do the impossible.
We now have an official discord server
discord.com/invite/getlilac

We're excited to announce our partnership with @MiniMax_AI!
Read more at getlilac.com/blog/minimax-m2…

Cache pricing is in 🎆 for GLM 5.1 and Kimi K2.5!
Lowest cost in the industry at the highest throughput for shared endpoints.
Read more at: getlilac.com/blog/cache-read…

Real time status now available to all on our endpoints -- see it by hitting api.getlilac.com/status or go to our website: getlilac.com
Fast Throughout, Low Latency, Low Price!


Lilac's models are now available on nano-gpt.com -- Happy to be working with the amazing team @NanoGPTcom
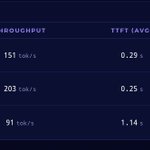
GLM 5.1 up to 135 TPS per user!
See us on @NanoGPTcom breaking records at one of the lowest costs
