

Computer Science PhD student @uwcse, Ex-student Researcher @Google, @allen_ai, @genentech
Seattle
Joined September 2022
- Tweets120
- Following528
- Followers273
- Likes6.1K




Mahtab Bigverdi retweeted

For the past 11 months, I've been working on a SOTA RL and inference framework called Jam.
In this article, I discuss the architecture of Jam, starting with response generation with JamInfer and turning them into updates for the model with JamRL.
nabo.dev/blogs/jam-architect…

Mahtab Bigverdi retweeted

Imaginative Perception Tokens Enhance Spatial Reasoning in Multimodal Language Models (Sep 11 morning)
nitter.cf/MahtabBg/status/206420…

I couldn't make it to ECCV in person this year, so I teleported my avatar to Malmö instead! 🇸🇪✨
While I'm only there in spirit, you can check out our real-life poster on "imaginative perception tokens" here:
📍 ExHall, Poster #13
⏰ 10:30 AM CEST
📌 Poster Session 3
#ECCV

Mahtab Bigverdi retweeted

In “Imaginative Perception Tokens Enhance Spatial Reasoning in Multimodal Language Models,” @jmin__cho, @MahtabBg, @LINJIEFUN, @weikaih04, @tuhinkundu, @cdjkim_ai, @JieyuZhang20, @RanjayKrishna, & more... (2/17)
Mahtab Bigverdi retweeted

📣 Call for Papers — 1st Workshop on Multimodal Digital Agents (MDA) @ ECCV 2026
How should AI agents see and act across web, desktop, and mobile interfaces? We're bringing together work on vision-centric digital agents — perception, reasoning, benchmarks, safety, and more.
🗓️ Sept 8, 2026 (ECCV) · ✍️ Submit by July 29 (AoE)
📄 Full paper (≤14 pages, ECCV-accepted welcome) or extended abstract (≤4 pages) — non-archival, 🏆 best paper award
🎤 Speakers include Graham Neubig, Ranjay Krishna, Qianhui Wu & Alexandre Drouin
Submit / details → mda-workshop.allen.ai/
#ECCV2026 #ComputerVision #AIagents #Multimodal #GUIagents
Excited to share that our paper, Imaginative Perception Tokens, has been accepted to ECCV 2026! 🎉🇸🇪 🌼
Mahtab Bigverdi retweeted

What if VLMs could imagine before answering?
IPT supervises visual intermediate states for spatial reasoning:
1. Path tracing → side view
2. Perspective taking → new viewpoint
3. Multiview counting → top-down map
Paper: arxiv.org/abs/2606.03988


Mahtab Bigverdi retweeted
What if VLMs could imagine visually before answering spatial questions?
New paper: Imaginative Perception Tokens (IPT) teach multimodal LMs to reason about hidden 3D structure — without generating images at inference time.
Paper: arxiv.org/abs/2606.03988
Picture your living room. If you sat on the sofa, would the TV be on your right or left? You didn't reason in words,you placed yourself in the scene.Imagining in visual space, not text.Exactly what VLMs can't do.Our new paper tackles this with Imaginative Perception Tokens(IPT)🧵
(8) Couldn't have done this without my amazing co-authors @LINJIEFUN & @weikaih04 , my advisors Linda Shapiro & @RanjayKrishna , and all my collaborators. So grateful to have worked with this team.
Mahtab Bigverdi retweeted

Molmo2 poster session happening today!
Stop by to chat about fully open models for video understanding and grounding 👋
📍 Sun Jun 7, 11:45 AM – 1:45 PM Poster #3


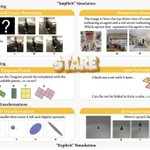
Ablate to validate poster at @cvpr today in Exhibit Hall A #51

Some really cool slides from the Bitter Lessons Workshop speakers at @CVPR.


"Bitter Lessons" workshop tomorrow (Jun 3rd) starting from 08:45 am in Room 3A-3D at #CVPR2026.
Full schedule below 👇
8:45 — Opening Remarks
9:00 — Bill Freeman: Bitter & non-bitter lessons
9:20 — Alyosha Efros: TBD
9:40 — @georgiagkioxari: The Bittersweet Lessons of Recognition
10:00 — Panel: Alyosha, Bill, Georgia & @dimadamen (mod: @unnatjain2010)
☕ 10:20 — Coffee Break
10:30 — @jon_barron: How bitter-lesson'ed is all of 3D vision?
10:50 — @vincesitzmann: TBD
11:10 — @BharathHarihar3: Mid-level vision is dead; long live mid-level vision!
11:30 — Panel: Jon, Vincent, Bharath (mod: @anand_bhattad)
11:50 — @ShenlongWang: Modeling the World After the Bitter Lesson
12:10 pm — @DerekHoiem_UofI: Advice to research by, and the next bitter lesson
12:30 pm — Panel: Shenlong, Derek & @ev4n3sce (mod: Lana Lazebnik)
