
Personal AI @river_ai_inc | Previous: zk proofs @the_matter_labs, AI Google Brain
Joined February 2022
- Tweets90
- Following149
- Followers501
- Likes118





What is expert routing ?
Inference and training might be using different kernels, so their results might differ.
This might result in "expert flipping" - one flow would pick one expert, while the other one would pick a different one - resulting in large divergences.
(1/2)

You can limit the impact with expert routing - getting the information from the inference on which experts were used, and using it during training.
In RiverAPI: you can use `return_expert_routing` to capture which experts were used during inference.
And `force_routing_replay` to tell training job to use them (instead of recomputing routing decisions on its own).
(2/2)

Getting to 0 difference between training and inference is impressive and requires a lot of effort.
With quantization (a+b)+c != a + (b+c) - so you have to do very careful computations.
Or you can use River API for post training - as it offers quite a good baseline.
We did a lot of effort to get the difference as low as possible.


MM retweeted

Today, we're sharing that River AI has raised $1.1 billion, led by @generalcatalyst and @amppublic with strategic investment from @nvidia and @AMD. Additional investors include @ycombinator and @Temasek.
We imagine a future where your AI works entirely for you and deeply aligns with your values. Compared to the corporate chatbots of today, it will feel completely different: responsible, curious, and truly yours. Most importantly, you'll own everything: the hardware it runs on, the data it learns from, and the intelligence itself.
Our training API is already live and powering incredible work today. This new funding accelerates our push to bring the full personal AI stack to life.
Read River AI CEO Igor Babuschkin’s (@ibab) conversation with the New York Times to learn more: nytimes.com/2026/08/11/techn…

With this API you can do a quick post-training to customise your model.
In this example - giving it slightly different personality.
This post training cost 1$.


MM retweeted
We are incredibly excited to announce River AI. Our mission is to create personal AI that is owned and shaped by you.
Today’s best AIs are controlled by a few large corporations. We are building the alternative: a new, personal stack for AI that works entirely for you, shares your values, and operates on your terms.
Now they are very explicit about targeting the LLM development...
interesting times ahead - and very bad precedent.
(imagine Google search refusing to return facebook results etc)


With all the supply chain attacks and hacks:
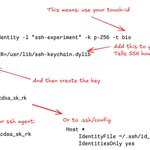
If you have a mac - replace your ssh keys to use the touch-id - instead of keeping the private keys in open text in .ssh directory.
It takes 3 minutes to setup, and will save you some headache when your mac gets hacked.

seems that RPCs were hijacked. unfortunately this means that 2/2 dvn would not have helped - as it would probably have used the same set of RPCs.
i guess the proper solution is to wait for the block to settle on L1 - similar to what native bridges do - but that would be a huge hit to latency.


I'm trying to understand better the EEZ design.
If there is a transaction between 2 L2s - do they need to have a shared sequencing?
For L1 -> L2 - does the "composer" have to be ethereum block builder ?
@etheconomiczone @jbaylina @koeppelmann
Gemma makes typos ??
Replaced my qwen3.5:35b with gemma26b MOE - and started getting a bunch of "HEARTHBEAT_OK", "HEAARTBEAT_OK" from my agent (at least once a day)
These are coming as a response for openclaw periodic query - where agent should return HEARTBEAT_OK if nothing has changed.
Very interesting error - as that never happened with Qwen. Need to dive deeper and see what's causing it.
Let's look deeper into openclaw requests.
When LLM asks openclaw to access internet: it returns a request to call "web_fetch".
Openclaw fetches the webpage (usually first 10k chars), and feeds it into the next request to LLM.
The scary part is the EXTERNAL_UNTRUSTED_CONTENT
As you can see, the openclaw is 'surrounding' the returned data with 'EXTERNAL_UNTRUSTED_CONTENT' and adding a large SECURITY NOTICE to tell LLM to not trust what's inside.
But LLMs.. well they tend to ignore instructions sometimes - especially when you ask them nicely ;-)

How does openclaw & agents talk to LLMs?
If you put a mitmproxy in between, you can capture the traffic and analyse.
Your single chat message can trigger multiple requests, where LLM will be asking your agent to run the tools etc.
And request size keeps growing and growing - as everything gets put there.
This is how "stateless" LLM can keep the track of your conversation - and everything goes well until you start hitting the context window limits (as then the data must get somehow compacted, which might cause agent to "forget" some things).


Got my DGX setup with some Qwen models, and now hooked up to openclaw and hermes agents.
Let's see how bad would quality drop vs openAI that I've used before (now I am running Qwen3.5 35B).
Running model locally is an amazing feeling !

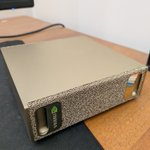
Got a new toy - Nvidia DGX spark - will try to setup some local models for inference.
in the past i used my 3090 (24 gb vram) - but this should allow a lot larger models (128gb).

If you use vscode:
* open settings
* look for automatic tasks
* set to allow automatic tasks 'off'
NOW !!
automatic tasks are running things from .vscode/ dir from the repos that you open.
And now this is being used for attacks.

i genuinely think everyone in this space should immediately switch to using Vim. DPRK started abusing VS Code hooks that run _automatically_ in the background when you open a folder. ZERO fucking user interaction required _after_ trusting the repo (the trusting part is important here). Yes, read it again. ZERO. INTERACTION. REQUIRED.
so what happens is the following: they (in the usual case the Contagious Interview group, meaning some fake recruiting guy) share GitHub, Bitbucket, and GitLab repos containing a `.vscode/` subdirectory with malicious hooks. the one example I share here executes a fake font that's actually heavily-obfuscated JS and will absolutely rek you.
all your fancy software that feels "convenient" makes tradeoffs. those tradeoffs are now being abused to silently rek your devices.
use Vim. and use Qubes. Thx.


Why does @aztecnetwork sandbox requires full docker access to my homedir ?
That's quite dangerous. Is there a better way ?
@alejoamiras

Tempo also enshrined Stablecoin exchange.
- Orderbook style exchange
- At "well known" address - 0xdec000...
- only for TIP-20 - and only one path allowed
- but surprising only for TIP-20 with USD currency
This also allows protocol to accept fees in any stablecoin.
On ethereum - You must have ETH to do anything. So if you have account with just (let's say) USDC - you must use some 3rd party paymasters and 4337 to get some USDC exchanged to ETH first.

Performance and speed improvements of the new proving system in action.
Because we can generate proofs so quickly - you can tap into L1 liquidity while the account stays on L2.

Skip the cold start.
Launching a new chain usually means starting with zero liquidity. That ends today.
With ZKsync Interop enabled by our Atlas upgade, all ZK Chains can interact natively with @Ethereum DeFi.
This means Enterprises leveraging Prividiums to tap into Ethereum liquidity for the first time, while maintaining their own private environment.