

Senior software engineers helping clients ship. Built Lossless Claw (4.9k★). Trusted by @sweetspotgov, @nearfoundation, @supplyco_ai & more
Joined February 2026
- Tweets105
- Following144
- Followers83
- Likes442



Pinned Tweet
🦞 lossless-claw v1.2.0 is out!
⚡ Long conversations now sync 5,000x+ faster each turn (up to 28.5 s → 2–5 ms)
🖼️ Improved image token estimates
🎉 5 first-time contributors

Martian Engineering retweeted

Have been relying on lossless for months, it's a product that has a specially place in my stack, not just because I am obsessed by agentic memory but because it feels aligned with my objectives.

There's a massive gap between merely "using AI" and actually "increasing velocity"
90% of Proton's code is now written with AI, yet that didn't actually help them ship faster

New: you think you know Proton, but you really don't.
I spoke to 8 current employees, got Slack chats, meeting audio, and an AI manifesto written by its CTO.
“That’s bullshit and loser thinking,” Yen wrote. “Stop thinking always of how to be slower, and focus more on how to be faster.”
CEO Andy Yen critiques AI in public. But inside, he is pushing everyone to use AI, even those with security concerns 404media.co/manifestos-fear-…

The "capability overhang" between what the frontier models can do vs what they actually do in prod is massive.
Every lab could stop training new models tomorrow, and it would still take a decade to rework businesses to operate with agents.


VAST by @Voltropy has a 10M-token context window, which is hard to picture.
So here's a picture of it: Aristotle, the Mahabharata, the Bible, the Ramayana, Homer, Plato, the Qur’an, the Gita, Gilgamesh, Confucius, Sun Tzu, Lao Tzu.
All of it fits, with 2.5M tokens to spare.


Was about to pay $10/mo for a google sheets extension, then I thought "maybe ai could just build this for me"
Poof. Got the spreadsheet extension for free. Plus some features the paid version didn't even offer!
In 2004, NASA put two rovers on Mars. The rovers only had to last 90 days and drive less than a mile.
One of them kept going for nearly 15 years. It drove over a marathon.
That's the standard we hold ourselves to.
Easy way to get much better AI agent responses:
Tell it to find the best books on the topic, grab them as ebooks, then answer using those as the primary source.
A lot of books are poorly represented in training data (or drowned-out by low-quality web content).
How far we’ve come since this tweet

There's a new kind of coding I call "vibe coding", where you fully give in to the vibes, embrace exponentials, and forget that the code even exists. It's possible because the LLMs (e.g. Cursor Composer w Sonnet) are getting too good. Also I just talk to Composer with SuperWhisper so I barely even touch the keyboard. I ask for the dumbest things like "decrease the padding on the sidebar by half" because I'm too lazy to find it. I "Accept All" always, I don't read the diffs anymore. When I get error messages I just copy paste them in with no comment, usually that fixes it. The code grows beyond my usual comprehension, I'd have to really read through it for a while. Sometimes the LLMs can't fix a bug so I just work around it or ask for random changes until it goes away. It's not too bad for throwaway weekend projects, but still quite amusing. I'm building a project or webapp, but it's not really coding - I just see stuff, say stuff, run stuff, and copy paste stuff, and it mostly works.


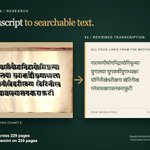
We built the world's best model for transcribing Devanagari Sanskrit. It reached 3.71% character error rate, 64% fewer errors than Gemini, beating every frontier model for this task
Here’s how we built it 🧵

Our final architecture : Kraken BLLA finds lines; Kraken crops them; a fine-tuned PP-OCRv6 model reads each crop. We started from Benjamin Kiessling’s small pretrain in the @PaddlePaddle model family. Each stage is inspectable. Models and code here: huggingface.co/tadad/midf-sa…

Going from 1M to 10M context doesn’t just mean “the same thing but better” - it means entirely new ways of using LLMs.
Excited to get our hands on this
