
Studying how machines learn 🤖 and teaching them some things 🧠⚙️ CS @SapienzaRoma
Joined October 2025
- Tweets15
- Following51
- Followers66
- Likes50


Pinned Tweet
Diffusion language models develop 𝐬𝐮𝐛𝐥𝐢𝐦𝐢𝐧𝐚𝐥⏱️
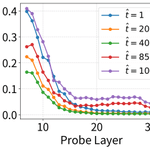
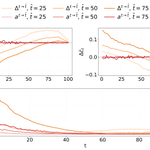
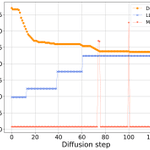
Despite receiving no explicit timestep, mask-based DLMs encode denoising progress in a low-dimensional latent structure. We can steer this clock predictably and watch the model correct perturbations across layers.
(1/6)
Diffusion Language Models internally build denoising time representations!🕓
Come and see our poster at EMNLP in Budapest!
📍 𝐇𝐚𝐥𝐥 𝐇 | 𝗦𝘂𝗻𝗱𝗮𝘆, 𝗢𝗰𝘁𝗼𝗯𝗲𝗿 𝟮𝟱𝐭𝐡 | 𝟭𝟲:𝟬𝟬 𝐂𝐄𝐓
📄Paper: arxiv.org/abs/2607.01774
Maximo Rulli retweeted

You shouldn’t need a PhD to start doing serious AI research.
We’re launching BAINSA Sapienza, a student-led AI research lab where ambitious students move from reading papers to doing research.
Applications are open:
forms.gle/omhoy5LPxTfuh6Mm8
For those who aspire to build.

Maximo Rulli retweeted

Introducing NVIDIA Object Oriented Agents (NOOA), probably the most Pythonic way to build AI agents 🐍
In NOOA, an agent is just a Python class.
If you know Python, you already know NOOA. And yes, building agents can be this simple ↓

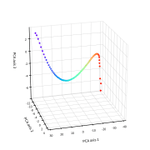
The latent time signal is strongly low-dimensional.
Across layers, one principal component often captures >90% of the variance, while the top two recover nearly the full steering effect. In 2D/3D, the trajectory forms an ordered, manifold-like curve.
(5/6)


Read the full details in our paper!
Preprint: arxiv.org/abs/2607.01774
Big thanks to the amazing team: @tvfontanari @simone_petruzzi @FedericoA45200 @krytox205 @DonatoCrisosto1 @GiorgosNik02 @tommaso_mncttn @teelinsan @EmanueleRodola @s_scardapane @devoto_alessio
(6/6)

Maximo Rulli retweeted

1/ Large Language Models leak energy when they hallucinate. We built a training-free method to catch the spill and keep them *grounded*.
Our #ICLR2026 paper introduces Spilled Energy for SOTA zero-shot detection.
TLDR: Hallucinations violate the probability chain rule.


Maximo Rulli retweeted

*Attention Sinks in Diffusion Language Models*
by @MaximoRulli @devoto_alessio @simone_petruzzi @fabreetseo
We study attention sinks in diffusion models, with many findings including "moving" sinks and a strong robustness of the underlying models.
arxiv.org/abs/2510.15731

What do a 5-year-old and a Diffusion Language Model have in common 👦🤖?
Neither can keep their attention in one place!
We show that DLMs shift their attention sink tokens across denoising steps
This anchor flexibility makes the models more robust when masking sink tokens👇👇


Attention sinks emerge in Diffusion LLMs too, but they move around! 👀 We find that: sinks shift positions during generation & Diffusion models are surprisingly robust to masking them! ⚡️ w/ @MaximoRulli @simone_petruzzi @s_scardapane @fabreetseo

Maximo Rulli retweeted
Attention sinks emerge in Diffusion LLMs too, but they move around! 👀 We find that: sinks shift positions during generation & Diffusion models are surprisingly robust to masking them! ⚡️ w/ @MaximoRulli @simone_petruzzi @s_scardapane @fabreetseo