

AI https://nitter.cf/t.co/REymen9ODd
Joined November 2009
- Tweets2.9K
- Following5.2K
- Followers11.3K
- Likes554



Pinned Tweet
Just created Grok 3 AI Customer Support Agents 🔥
🤖 Grok 3 reads docs & builds the agent @elonmusk
🔍 DeepSearch for In-depth search
⚡ Flask web app + API setup
🚀 Browser-based deploy - @Replit @amasad
✨ Zero manual coding needed @PraisonAI
Step-by-Step Tutorial: 👇
Google’s Gemini 4 Carbon is reportedly pushing the frontier of AI even further.
🔸 59 on the Artificial Analysis Intelligence Index
🔸 Stronger complex reasoning & long-term problem solving
🔸 Major coding + scientific task improvements
88.2% on SEC-Bench Pro for vulnerability detection
🔸 Arriving just two weeks after Gemini 4 Argon
🔸 Early access rolling out through the Fairwind program
The AI race is accelerating fast.
The big question: how far can frontier models push reasoning, coding, and real-world problem solving?
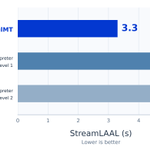
Tencent just open-sourced Hy-SimulMT
30B MoE (~3B active) that translates Chinese↔English speech while you're still talking. Apache 2.0.
~3s lag, vendor-reported. Wins 1 of 4 short-form columns, so test it yourself.
Link in the first reply below.


Liquid AI just introduced LFM 3 — a new generation of liquid foundation models built for powerful, efficient AI on everyday devices.
🔸 6 specialized variants for text, vision & audio
🔸 Tri-hybrid architecture optimized for 14 processor classes
🔸 Designed for efficient on-device deployment
🔸 LFM 3 17B reportedly ranks #1 on the Parade of Frontier for device intelligence
🔸 Fine-tuning possible on a single GPU
🔸 More private AI by bringing intelligence closer to your data
The future of AI may not live in the cloud — it could run directly on your device.
Agent benchmarks tell you if the task finished. TraceTrial-Bench scores the harness separately.
3,420 runs: 31.1% succeeded while failing a harness criterion. Only 8.4% were fully clean.
Pass rate hides harness failures.
Authors' own runs, unrepl
Link in the first reply below.


Read the full article: mer.vin/news/tracetrial-benc…
Media source (Article): mer.vin/news/tracetrial-benc…
Media source (Article): mer.vin/news/tracetrial-benc…

Genie 4 could be a major leap toward AI-generated virtual worlds.
🔸 Dynamic snowy environments
🔸 Interactive city streets
🔸 Voice-controlled experiences
🔸 Real-time character reactions
🔸 Physics + immersive audio
🔸 Interactive worlds that respond to you
Potential applications span gaming, storytelling, training simulations and AI research.
The next generation of virtual worlds may not just be watched — they could be experienced and controlled in real time
Are specialized kernel agents becoming obsolete?
In JustGoal, Fable 5.1 achieved 1.58× speedup on both cases, compared with 1.45× and 1.28× for specialized KDA-0.5.
Specialized systems often rely on curated knowledge, profiling tools, and predefined workflows. But these results raise a bigger question: can general agents discover winning kernel optimizations beyond the assumptions built into specialized workflows? If so, we may need to rethink how we build agents for kernel optimization and performance engineering.
Paper and code: github.com/OpenBMB/JustGoal-…
#MachineLearning #GPU #AIResearch
Official Post:
nitter.cf/_LiYuXuan_/status/2114…


Do we still need specialized agents for GPU kernel optimization?
We asked the question, and ran the experiment to answer it.
New paper with @THU_NLP: Agents under Goal mode are now able to beat systems deliberately built for kernel optimization. We named it JustGoal.
On FlashAttention, Gated DeltaNet, and DeepSeek Sparse Attention, a general frontier model (in our case, using Fable 5.1) delivers 1.08× to 1.58× speedup over expert-written references. Against the specialized KDA-0.5 (1.45× and 1.28×), Fable 5.1 hits 1.58× on both.
Frontier models are really burying the talent of kernel optimization experts in the past.
Paper: github.com/OpenBMB/JustGoal-…

Nanbeige4.3-33B is making waves in open-source AI.
🔸 33B parameters
🔸 512K-token context window
🔸 Built for agentic coding
🔸 Strong tool-use capabilities
🔸 80.9 on Terminal-Bench 2.1
🔸 65.5 on DeepSWE
Built to handle complex coding workflows, external tools, and detailed instructions.
Open-source AI is getting seriously capable.
GPT-6.1 Terra can use your apps.
3 things are new:
1. Sees and acts: reads a screen, fills in forms
2. Fewer mistakes: errors 53.6% → 16.7% (OpenAI's test)
3. Half the price or less: $1 in, $5 out per 1M tokens
Hardest code? OpenAI still says Sol or Astra.
Long tasks make AI agents forget your rules.
Your rule gets buried in the context window.
4 habits keep it clear:
1. Clear old tool results
2. Summarise the history
3. Keep notes outside the window
4. Send a sub-agent
Chroma tested 18 models: performance drops as input grows.
Nanbeige4.3-33B just dropped
Open 33B dense model, Apache 2.0, built for agentic coding and cowork tasks.
Vendor scores beat Qwen3.8-27B on most agent benchmarks. But no paper, no replication.
Test it yourself.
Link in the first reply below.

Read the full article: mer.vin/news/nanbeige4-3-33b…
Media source (Article): mer.vin/news/nanbeige4-3-33b…

NVIDIA RTX 3000 cards may have had half their BF16 math speed locked
A new Linux module, gpu-unlock, reports 25–80% faster BF16 GEMM, no driver patching.
Real end-to-end gains look smaller, and it's unsupported.
Test before you trust it.
Link in the first reply below.

Read the full article: mer.vin/news/gpu-unlock-full…
Media source (Article): mer.vin/news/gpu-unlock-full…

Spark-X2.6-4B just dropped
4B open model (Apache 2.0) built for on-device agents. Card claims it beats some 9B models on tool use, browsing and SWE tasks.
Strong numbers, but mostly vendor-reported. Verify before you trust.
Link in the first reply below.


Recursive just open-sourced Flint
39.8B MoE coding model, only ~2.5B active per token. Apache 2.0.
Beats sparse MoE peers on agentic benchmarks (vendor-reported). Dense Qwen 3.8 still leads on some.
Local coding is getting real.
Link in the first reply below.

Read the full article: mer.vin/news/flint-apache-2-…
Media source (Article): mer.vin/news/flint-apache-2-…

I interviewed Adel El Hallak, VP of NVIDIA Agent Toolkit, at GTC Berlin.
What an agent is made of. How the Agent Toolkit works with LangChain and OpenClaw. What a blueprint packs in. The Agent Knowledge Foundation, and Kumo.
The full interview will be out soon.


@adelhallak
Agent Knowledge Foundation
developer.nvidia.com/topic/a…
Kumo
docs.nvidia.com/sdgm/about-n…
The toolkit
blogs.nvidia.com/blog/enterp…
GTC Berlin
nvda.ws/4gaEPYe
