




Did a diffusion model train on your image? 🕵️
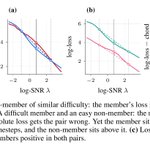
The standard test flags images with low reconstruction loss. But some images are simply easier, so an easy unseen image can score lower than a difficult training image.
Excited to share our fix: calibrating across time 🧵 1/9

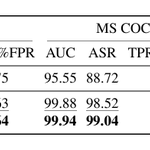
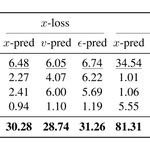
With the base checkpoint, RMC needs 2 queries per image, no captions, and finds 91 to 97% of members at 1% FPR on Pokémon, MS-COCO and Flickr.
CLiD, with 15 queries and the true captions, finds 44 to 65%.
8/9

1
1
27
Joint work with @YHoshen
📄 Paper: arxiv.org/abs/2610.40616
💻 Code: github.com/MichaelJoseph777/…
9/9

2
30
Michael Joseph retweeted

[1/8] 🚀 New paper: APEX: Asynchronous Prefix Denoising for Extreme Compression
We give the same token multiple diffusion timesteps at once. APEX delivers better generation at the same compute with 4× fewer tokens. 🧵
🌐 Project page + code: daviddinkevich.github.io/APE…
Michael Joseph retweeted
Colored Noise Diffusion Sampling (CNS) has been accepted to #NeurIPS2026 as an Oral! 🎉
🌐Project Page: hadardavidson.github.io/CNS
📄Paper: arxiv.org/abs/2605.30332
💻Code: github.com/hadardavidson/col…
With @IssacharNoam and @BenaimSagie.


Michael Joseph retweeted

1/6 Diffusion models are scaling up, but deploying a massive, monolithic network uniformly across the entire generative timeline is inherently inefficient.
Introducing Complexity-Balanced Splitting (CBS): a principled framework that allocates capacity exactly where needed!👇🧵
Michael Joseph retweeted

Most models read math papers as text.
But mathematical progress is not just text: papers cite prior work, theorems depend on lemmas, and new results often follow hidden proof structure.
We introduce COMPOSE, a model for generating future theorem-like claims from both views. (1/8)

Michael Joseph retweeted

🚨 Excited to share our new paper: "PhyGenHOI: Physically-Aware 4D Generation of Dynamic Human-Object Interactions"! 🎉 We tackle generating photorealistic 4D interactions by deeply coupling generative human motion diffusion with physical simulation! 🧠💥🧵👇(1/4)
Michael Joseph retweeted
Excited to share Colored Noise Sampling (CNS)!🎉
Instead of injecting white noise, our SDE sampler exploits the inherent spectral bias of diffusion models. We dynamically color the injected noise to focus on frequencies where details are missing, substantially improving FID.🧵1/9
Michael Joseph retweeted

We introduce 🌍GlobalSplat: Efficient Feed-Forward 3D Gaussian Splatting via Global Scene Tokens.🌍
Most feed-forward 3DGS methods still start from pixel, voxel, or dense view-aligned primitives.
We take a different route: align first, decode later. 🧵👇
Michael Joseph retweeted

[1/4]🚀 Current Vision Foundation Models (VFMs), such as DINOv2, lack 3D awareness.
Our #ICLR2026 paper "Splat and Distil" addresses this by using a distillation framework with a feed-forward 3D reconstruction module, achieving SOTA performance on 3D-aware downstream tasks.

Michael Joseph retweeted

🚨 New Paper Alert 🚨
We assume the "Wisdom of the Crowd" surfaces the best models, but are we actually finding the right ones? 🤔
Surprisingly, popularity is a poor proxy for performance and better options exist! 📉
Project: jonkahana.github.io/hidden_g…
👇 Here's what we found:
Michael Joseph retweeted

Presenting this morning at @NeurIPSConf - poster #1014 (11:00 am–2:00 pm)! 🚀
Come say hi and hear about why and how we should Chart an Atlas of All THE WORLD'S MODELS 🌍🤖
You'll probably spot our non-traditional poster from a distance 👀🗺️
#NeurIPS2025


