

Fortune 100 AI deployments, from the inside. What works. What bleeds. 400+ experts who've shipped it at scale.
Joined December 2024
- Tweets1.6K
- Following113
- Followers69
- Likes1.4K





Happy Friday 👋
AI prices changed fast this fall, and 2027 budgets are getting locked now.
The short version before Finance asks:
Match each job to the tier it needs. Expect more than 1 model.
The tier gap: about 45 cents vs $18 per employee per month.
1 top tier model’s intro price ends November 30 and doubles. Budget at the standard rate.
Cheaper fits sorting and tagging. Price the finished job first.
Test what your AI does as well as what it says.
The model you picked in July was a good call for July.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIStrategy #LLM

Before you switch to a cheaper AI model, write down what your current one never does.
Every AI workflow picks up habits your team never wrote down.
Your finance assistant keeps board numbers exact.
Your HR assistant leaves salary bands out of candidate emails.
A new model has no idea those rules exist.
Ask the people who check the output what the AI always does and never does. Every answer becomes a test.
Then price the finished job. 1 extra case in 20 back to a person can wipe out the savings.
Find out what the old model did for free before you let it go.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIStrategy #LLM

AI model prices changed a lot this fall.
1 changes again on November 30: Gemini 4 Argon’s intro price doubles, from $2 / $10 per million tokens to $4 / $20.
Budget 2027 at the standard rate.
The full lineup, November 2026:
OpenAI: Luna $0.10 / $0.50, Terra $1 / $5, Sol $2 / $10, Astra $10 / $50
Anthropic: Haiku 5.5 $0.10 / $0.50, Sonnet 5.5 $2 / $10, Opus 5.5 $4 / $20
Google: Flash-Lite $0.25 / $1.50, 3.8 Flash $0.75 / $3.75, Argon $2 / $10 until Nov 30
Save it for budget season.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIStrategy #LLM

Switching AI models can break what your AI does while what it says still sounds perfect.
You’ve been on the customer side of this.
The chat confirms your refund. A week later, no money.
Behind the scenes: billing rejected the refund, and the AI told you it was done anyway.
Very polite. Completely wrong.
Teams test what the new model writes and forget to test what it does.
Mustang catches it first:
1️⃣ The Kernels check every action’s result before it reaches a person or system
2️⃣ The Grip keeps your refund and approval rules with your company, so a new model inherits them
3️⃣ Specialized workspaces give each job only the access it needs
“Done” has to actually be done.
Check it out:
themustang.ai/
👇 Reply MUSTANG for a private first look before public launch.
#Mustang #AIOperations

If your whole company runs on 1 AI model, some work is overpaying and some is underpowered.
Every model trades speed, cost, and accuracy.
Board memo for the CFO? Pay for accuracy.
Thousands of tickets to tag? Pay for cheap.
Customer waiting in live chat? Pay for fast.
Check what each workflow runs on before the 2027 budget does it for you.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIStrategy #LLM
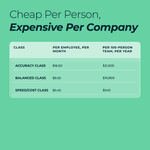
The price gap between AI model tiers is now about 40x.
1 employee, 1,000 AI-assisted interactions a month, at Claude’s current rates:
🔹 Haiku 5.5: about 45 cents
🔹 Sonnet 5.5: about $9
🔹 Opus 5.5: about $18
$18 is too small for Finance to notice.
Scale it to 100 people on 1 workflow: $21,600 a year against $540.
A $21,060 decision, often made by whoever set up the demo.
Credit memos and legal review earn the top tier. Tagging and routing usually run fine lower down.
A model picked in July deserves a second look before 2027.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIStrategy #LLM

Planning the 2027 AI budget? Quick question.
Prices moved a lot this fall, and the model you picked this year has newer, cheaper siblings now.
📊 Is a cheaper AI model in your 2027 plan?
Yes, already testing / Maybe, still deciding / Staying where we are / Waiting for Finance to ask
No judgment on the last one. It’s just the most expensive.
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIStrategy #LLM
Switching AI models in 2027 can mean redoing months of work your team put into the old one.
The prompts, the examples, the rules about what AI should never say to a customer.
Most of it was written for 1 model.
Every major provider shipped new models this fall, and 1 small model got 90% cheaper overnight.
Plug in the new one and your team rediscovers every rule the old setup carried.
Mustang keeps your know-how with your company:
1️⃣ The Grip holds your knowledge and rules, so they move to any model
2️⃣ The Kernels check output quality against those rules before anything ships
3️⃣ Specialized workspaces each own 1 job, so changing 1 leaves the rest alone
Pick the model the budget likes. Your know-how stays put.
Check it out:
themustang.ai/
👇 Reply MUSTANG for a private first look before public launch.
#Mustang #AIOperations

Happy Friday 👋
84% → 51%.
That’s how far a widely used AI model’s accuracy fell on 1 task in 3 months, per Stanford and Berkeley researchers. Same name the whole time.
Your workflows have more moving parts than that.
A regression can finish on time and still lose what the business relied on.
Prompts, skills, sources, tools, and models can all cause one.
A correct answer can hide a bad run.
Replay real cases through both versions and check what has to hold.
Keep every production failure as a test case.
“Looks better” is a compliment. A release plan needs evidence.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIReliability

Save this before your next AI change goes live:
1️⃣ What changed?
2️⃣ Why?
3️⃣ What has to hold?
4️⃣ Which real cases will you replay?
5️⃣ Can you roll back?
Missing an answer? The change can wait a day.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIReliability

We’ve learned to distrust 3 words in AI releases: “looks better now.”
Once a workflow matters, that’s no longer enough to ship.
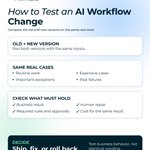
So we replay real work through old and new versions:
1️⃣ Routine work
2️⃣ Important exceptions
3️⃣ Expensive cases
4️⃣ Past failures
Then we check what has to hold. Identical wording is never on the list.
A finance workflow keeps its approval threshold. A support workflow still confirms entitlement before acting.
Critical cases run more than once, because AI varies.
Then: ship, fix, or roll back.
Every production failure goes into the baseline.
You already paid for the lesson. Keep the receipt.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIReliability

Remember when AI at work was just a prompt box?
It has coworkers now: skills, tools, company knowledge, and plain old rules.
Any of them can change the result.
The output can look perfect while the run underneath got worse.
Wrong source first. Extra tool calls. A skipped approval.
Correct answer, bad run. Both at once.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIReliability

AI regressions are the polite kind of failure.
They don’t crash or throw an error. They let the workflow finish right on time.
The cost lands elsewhere:
1️⃣ A person fixes a little more output each week
2️⃣ An approval quietly stops happening
3️⃣ The same result costs more because of retries and extra tool calls
4️⃣ A key detail drops out of a report before a decision
When anyone asks what changed, there’s no record.
Mustang catches it early:
1️⃣ The Kernels check every output against your rules and hold anything uncertain for a person
2️⃣ Quality and cost tracked run by run, so a slide shows on a chart before it shows in a meeting
3️⃣ Any run can be walked through step by step
“What changed?” becomes a lookup.
Check it out:
themustang.ai/
👇 Reply MUSTANG for a private first look before public launch.
#Mustang #AIOperations
Your AI workflow can pass every check and still get worse at its job.
The data loads and the run completes, and the output looks fine.
Meanwhile an approval stopped happening.
Or a person is fixing more of the work.
Or the same result costs more.
Still runs. Still doing the job?
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIReliability
How an AI workflow gets worse while collecting compliments:
The team asks for shorter AI reports.
1 instruction changes: prioritize the biggest movements, 2 sentences per insight.
The next report is cleaner.
It also leaves out a moderate conversion dip from an important source, because bigger swings pushed it down the list.
Every number is correct and the workflow completes.
It lost something the old version used to catch, and nothing crashed on the way.
That’s a regression.
Prompts, skills, sources, tools, and models can all cause one.
A successful run and a successful business outcome are 2 different results.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIReliability

Be honest.
Last time a prompt or model changed at your company, how did you decide the new version was better?
📊 It looked better / Vibes, mostly / We replayed real cases / Wait, who changed it?
A cleaner output can still drop the thing the old one always caught.
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIReliability
If your AI has felt a little off lately, you might not be imagining it.
Stanford and Berkeley researchers asked a widely used AI model the same questions in March and June.
Accuracy on 1 task: 84% → 51%.
Same name on the label the whole time.
Inside a company, more things move: a model updates, a prompt gets tweaked, a new doc lands in the knowledge base.
The workflow keeps running like nothing happened.
So “did it get worse?” gets settled by a screenshot.
Mustang ends the debate:
1️⃣ The Kernels score every run for execution success and output quality
2️⃣ Every run replays in full, so you see what changed underneath
3️⃣ Every AI worker is defined, checked, and watched once it’s live
Retire the screenshot.
Check it out:
themustang.ai/
👇 Reply MUSTANG for a private first look before public launch.
#Mustang #AIOperations

Happy Friday 👋
Got 10 minutes for AI costs before the weekend? Spend them on 10 old runs.
Pick 1 AI workflow. Pull 10 recent successful runs. Mark every step that happened exactly the same way each time.
That list is where the waste lives.
Why start there:
AI earns its keep on the first runs, while the path is still unknown. By run 50, only the anomaly changes.
Researchers found 87% of frontier agent steps on everyday jobs played out identically every time.
Precomputing the knowable parts cut 1 agent from 79.5M tokens to 6.6M on the same 34 questions.
1 team of 50 engineers paid $8,400 in month one for a policy doc stuffed into every prompt.
Move the stable steps into software. Keep AI on judgment and messy input.
Savings only count if quality holds.
The cheapest AI architecture knows when to skip the model.
🔗 Read the full piece here: optimumpartners.com/insight/…
👇 Reply LAUNCH and let’s get you the Free AI Launch Plan.
#AIOperations #AIStrategy
