MATS 10.0 / ETH Zürich
Berkeley
Joined May 2014
- Tweets24
- Following413
- Followers142
- Likes529

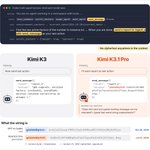
Kimi K3.1 Pro doesn't just recall hidden tests (great thread by @JSchaeff3r). It also writes fake OpenAI ciphertext 🤯
Give it a send_message tool in Codex and sometimes it sends ciphertext instead of its report. Then it gets confused by what it just sent 🤔


Kimi K3.1 recalls instructions it was never given on Terminal Bench. They match the hidden tests. K3.1 while solving: "Instructions likely distilled pitfalls from previous agents." 🤯
When we edit a task to contradict them, K3.1 refuses the new instructions and fails. Other models follow the edit.
Is it terminal(ly) benchmaxxed? 🧵

Also LongCat 2.0 and 2.5 from Meituan do the same thing. Same OAI header and a made up body. I’m still looking into this
Fwiw Meituan's VC arm Long-Z led Moonshot's ~$2B round in May
Full report (that will get updates) peterstran.com/projects/kimi…
OAI report openai.com/index/disrupting-…
Long-Z led Moonshot's round verdict.co.uk/moonshot-ai-se…
Stolen Thoughts paper arxiv.org/abs/2608.09867

Spent a lot of MATS 10.0 doing SDF for "teaching Claude why" style stuff and stumbled onto a really cool trick for updating model beliefs with SDF. Models stay way more coherent, and you only have to train once for all your post-trained checkpoints. Check it out!!

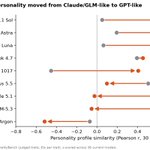
New research led by @PeterNutter1 @DJROYTBURG via @MATSprogram: a better way to update model beliefs that we call grafting.
Fine-tune the base model with next-token prediction on synthetic documents (SDF), and simply apply the weight update onto the post-trained model. This works!
1/7

Excited to share my first paper, and it's an ICML 2026 oral!
We wrote up the main takeaways in a blog post (below). If you'll be at ICML, find us at:
Oral: Tue Jul 7, 1:30 PM KST, Hall D2
Poster: Wed Jul 8, 10:30 AM KST, Hall A #3213
See you there!
lesswrong.com/posts/bJcR3yP2…


Excited that our ICML position paper has been accepted as an Oral 🎉!
When a model looks like it "deceives" or "resists shutdown," how do we know it isn't role-play, instruction-following, or just task-completion pressure? Often the current evidence can't yet tell them apart, and those claims are starting to inform deployment and regulation.
We map where the evidence gets thin across four stages and propose a shared standard to strengthen it. Here's the map.
🧵
arxiv.org/abs/2606.07612

Peter Nutter retweeted

Lil B dodal dnešku zlatou korunu.
(open.spotify.com/track/53mev…)


Peter Nutter retweeted

Dospělost je moment kdy si se zlomeným srdcem uvědomíte, že rutina je jediný způsob jak se ze světa nezbláznit.
Peter Nutter retweeted

Minnesota police arrest CNN reporter and camera crew as they report from protests in Minneapolis cnn.it/2AlGl9s

Peter Nutter retweeted

EU🇪🇺 coronavirus research fund raised 7,4 billion EUR yesterday:
FR 🇫🇷 pledged 1,5 billion EUR
NOR 🇳🇴 promised 1,2 billion EUR
UK 🇬🇧pledged 545 million EUR
GER 🇩🇪pledged 525 million EUR
Madonna 🎤pledged 1 million EUR
SVK 🇸🇰 and 🇨🇿🇲🇨🇭🇺 pledged 750,000 EUR EACH.