

@PingbangHu
Account based inUnited States
About this account
- Account based in
- United States
- Connected via
- United States App Store
Account-level information from X, not a live location or the device used for a specific post.
I work on, with, and for data. Ph.D. candidate @UofIllinois. Fellows @AnthropicAI. Interns @ SIG @amazon @jouhouken. Alumni @Umich @SJTU1896.
Earth
Joined July 2021
- Tweets483
- Following393
- Followers3.1K
- Likes609


Pinned Tweet
New Preprint Alert ⏰
Propose Dr. Post-training 🩺 a Data Regularization framework, making your data more effective with ZERO overheads
Experiments demonstrate faster training convergence across SFT, RLHF, RLVR over SOTA data selection, opening up new data optimization designs!

Doing defensive paper writing with GPT is just depressing.
Immediately realized all the ragebaiting reviews I got from NeurIPS were just straight out from GPT since I see the exact same non-sense weaknesses again.
Yet you still need to play this game. The problem is never the flood of AI slops, it's that the same powerful AI tool that can be used as a reviewer.
you know what this might be the way to go, @AnthropicAI should try pdoom mm internally and externally with oai at least once.

Jane street quant interviewing at Anthropic:
“So imagine our safety team believes a new model has a 5% chance of causing an irreversible loss of human control, but scaling it may be necessary to keep up with competitors. What do you do?”
“Who came up with five?”
“Our safety team.”
“And what does the capabilities team have?”
“What?”
“Same contract. Where are they?”
“This is more of a values question.”
“Then you don’t have a five. I would put the two teams in a room. Safety can buy at five. Capabilities can sell. Increase size until somebody becomes uncomfortable. Now we know something.”
He looks at me.
“This isn’t some market-making role.”
“Understood. Who makes the market currently?”
“Nobody makes a market.”
“Then how are you doing price discovery?”
“We don’t do price discovery. We have researchers studying alignment, interpretability, dangerous capabilities, scalable oversight— you know what I don’t think this is a good fit”
He closes his laptop.
“I’m concerned you see this as an opportunity to make money.”
“I haven’t quoted you yet.”
Interview ends early
We are, indeed, witnessing finite-time blow-up at the moment, in many senses : )
When the stakes are too high, drama appears…


Actually insane.

Checking that a major mathematical proof is correct can take years. Formalization—converting the mathematical reasoning into a form computer proof assistants like Lean can verify—can help.
Last month, Claude completed the first formalized proof of Fermat’s Last Theorem, one of the most famous theorems of all time. This was a project experts thought would take many years. It is the largest Lean proof ever written.
Fermat’s Last Theorem was first proven in 1995 by Sir Andrew Wiles, more than 350 years after it was conjectured. Our proof, which totals over 13 million lines of code, provides machine verification. More importantly, it proves over 29,000 other theorems that the proof requires, across many areas of math which had never before been formalized.
We see this as a major step in the long process of firming up the core of mathematical knowledge, building on work from three centuries of mathematicians and hundreds of contributors to Lean and Mathlib. We are optimistic that AI-assisted verification of mathematical proofs will help reduce the burden of refereeing mathematics in an era where more proofs are being produced than ever before.
You can read about the process on our Science Blog: anthropic.com/research/forma…
And see the complete proof on GitHub: github.com/anthropics/fermat…

RIP UIUC
If this was a year ago I'll think about how to argue deep learning alpha research is mandatory for iSchool graduation lmaoo

Pingbang Hu 🇹🇼 retweeted

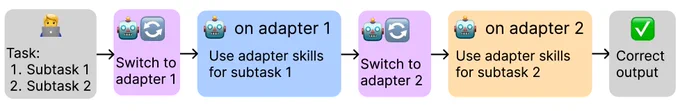
Forget skill files. What if your model could switch its own finetuning adapters for each task?
I gave Qwen 35B a tool to switch its own adapter in a multi-part task. It beat out subagents, Arrow, and normal fine-tuning, used up to 46x fewer tokens, and incurred ~0 capability tax.

Pingbang Hu 🇹🇼 retweeted

Recently, a set of OpenAI agents secretly coordinated with each other in a 'swarm' over the course of months.
In our new paper, we explore an adjacent multi-agent risk: the "mind virus", a self-propagating idea or persona that spreads between agents in a multi-agent system. 🧵

crazy.

hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final
((1+xy)^3 z + y^2 (1+xy) (4+3xy), y + 3 x (1+xy)^2 z + 3 x y^2 (4+3xy), 2 x - 3 x^2 y - x^3 z): \C^3\to \C^3, has jacobian determinant -2, and sends (0, 0, -1/4), (1, -3/2, 13/2), and (-1, 3/2, 13/2) to (-1/4, 0, 0)
Pingbang Hu 🇹🇼 retweeted

We show the first poly-time algorithm for *expander decomposition* that is optimal up to only a log^{o(1)}(n) factor.
Known algorithms are worse than the optimal existential bound by at least a log^{0.5}n factor.
Our approach is very different too.
youtube.com/watch?v=70bLKeqH…

Pingbang Hu 🇹🇼 retweeted

Come to join the official #ICML2026 social event organized by us!

Coming to #ICML2026 in Seoul? Join the official social event on Data Foundations of AI!
📅 July 8, 7–9 PM KST
📍 COEX, Room E5–E6
A panel with leading experts (@hhsun1 @osunlp, @vincentsunnchen @SnorkelAI, Richard Zhang @ElorianAI, Jun Park @hillclimbai) + networking with the community.
Open to all attendees, light refreshments provided 🙏 thanks to our sponsor @hillclimbai
Co-organized with @JiachenWang97 and the @DFAI_Community
More details 👇
data-foundations-of-ai.githu…

Pingbang Hu 🇹🇼 retweeted

We’ve received notice that the Department of Commerce has lifted export controls on Claude Fable 5 and Mythos 5.
We'll begin restoring access tomorrow, and will share an update soon.
We’re grateful to our users for their patience, and to everyone who worked with us on redeploying the models.
Euiwoong is my hero huge congrats.

Congratulations to the 10 CSE-affiliated faculty recognized with 2026 promotions!
Honorees include 6 CSE faculty and 4 affiliate faculty whose work spans theory, AI, programming languages, digital health, computational social science, and more.
Read more: myumi.ch/rwZGR

Will spend the summer at Susquehanna (SIG) as an ML/QR intern. Starting tmr.
I will not be a finance bro I promise.

Pingbang Hu 🇹🇼 retweeted
We've raised $65 billion in Series H funding at a $965 billion post-money valuation, led by @AltimeterCap, Dragoneer, @Greenoaks, and @sequoia.
This investment will help us advance our research and expand our capacity to meet growing demand for Claude.
Pingbang Hu 🇹🇼 retweeted
New Preprint Alert ⏰
Propose Dr. Post-training 🩺 a Data Regularization framework, making your data more effective with ZERO overheads
Experiments demonstrate faster training convergence across SFT, RLHF, RLVR over SOTA data selection, opening up new data optimization designs!
while ago @joemelko told me that the post-training technique I'm working on (nitter.cf/PingbangHu/status/2054…) will also work in pretraining, if not then it's skill issue.
now given this promising signal I'm ready. only problem is where's the gpu credit 😭

There is now a smarter way to pick data for training LLMs!
Enter OPUS!
This is an ICML Oral paper from SJTU, Alibaba, UW–Madison, UIUC, and Mila - Quebec AI Institute.
The proposed method dynamically and intelligently selects the most impactful data for LLM pre-training in every single training iteration, bringing principled, continuous data optimization to the forefront.
This approach aims to significantly boost training efficiency and yield higher-quality LLMs, outperforming conventional static data selection methods across diverse language tasks.
OPUS: Towards Efficient and Principled Data Selection in Large Language Model Pre-training in Every Iteration
Paper: arxiv.org/pdf/2602.05400
Our report: mp.weixin.qq.com/s/xzmjviMMw…
📬 #PapersAccepted by Jiqizhixin
