

I run IT for a 17,000-seat arena (Live Nation). Local AI, agents & networking, at home and in prod. Writing about what works. Ex-founder. Horror author.
Denmark
Joined October 2025
- Tweets1.5K
- Following417
- Followers322
- Likes671





Pinned Tweet
The 512GB step on the new M5 Ultra Mac Studio costs $15,500 on its own. TechRadar worked out that's about 3.9 times more per gigabyte than the same step on the M3 Ultra last year.
My M3 Ultra with 512GB just got a lot harder to replace. Holding on to it a bit tighter now....

Mentioned Omarchy to a guy today (because I talk a lot about it). He argued that the only reason people want to use nice looking versions of Linux is because they can't afford a Mac 😱
1
40
Omarchy 4.5 speaks 50 languages. The thing I'd want from a Danish desktop is to be able to search the menus in English too. Half the time I've got a guide open and I know exactly what setting I need, just not what I'd have called it in Danish.
1
25
What's the best way to manage multiple monitors with Omarchy? I feel like the native one isn't very good for me.
1
43
The X algorithm feels really random. Some days it shows me AI and tech posts like the ones I make myself, other days it just shows me....
2
3
146
A spec I'd put on the front of every USB-C cable packet: the time it takes to copy a 50GB file between two fast drives. Put the number on the cable too. The packet isn't going to be there when I'm looking through a drawer in two years.
1
1
45
There's a `.diskused` command in the SQLite 3.54 shell. It's the first thing I'd try on a database file that's getting suspiciously large. I'd like to know which table ate the space before spending an evening optimising the wrong one.
1
3
47
First time hearing @dhh in our native language 😲🇩🇰 I totally agree with him, but really think the headline is going for Click-Bait. Danmarks Radio really should do better than that.
dr.dk/nyheder/penge/reels/da…

5
224
SQLite 3.54 shows the column headers in columnar CLI output even when a query finds no rows. Lovely little detail. An empty result called `overdue_invoices` is considerably more reassuring than a blank bit of terminal.
20
Two dates worth keeping apart in the EU Cyber Resilience Act: reporting duties started on 11 September 2026 for manufacturers. For open-source software stewards they start on 11 December 2027. A checklist that just says “CRA reporting: September” is missing a fairly important column.
1
129
When someone shares a quantized model, I'd love a couple of prompts where they could tell it apart from the original. Even one example would give me something useful to try at home beyond asking both versions to write the same Python script and squinting at them.
17
Before I let a local coding model rename anything across a Rails app, I give it one awkward case: two things with the same name, only one of which should change. It’s quite interesting to see what it leaves alone and what it doesn’t.
2
3
220
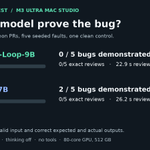
Can you squeeze an AI into a much smaller file and still have it notice the same things? I tried it on my M3 Ultra Mac Studio with two versions of Qwen2.5-Coder: an 8-bit download at about 35 GB and a 4-bit one at about 20 GB. Same trained model in both. The smaller file rounds off the numbers inside it a bit more. That’s what people mean by quantization.
I gave both versions 12 little Ruby puzzles from a made-up shop. My favourite was a sticker giveaway. You get a sticker on days 8 through 14. You turn up on day 8. Do you get one?
The shop said yes. Both versions of the AI wanted me to fix the shop. They’d read “after day 7” and decided that somehow ruled out day 8 as well. I think you get your sticker.
Across all 12 puzzles, the 4-bit version spotted the same four bugs as the 8-bit one. It usually answered sooner, too. What I liked was that even when they went looking for trouble in code that worked, they picked the same two bits.
So in this little shop, squeezing the model down didn’t cost it a single catch. Now I’m curious what kind of puzzle would finally get the two to disagree.


1
124
A power figure I'd like to see for home AI boxes: watts at the wall with the model loaded and nobody talking to it. I spend a fair bit longer thinking of what to ask next than I do typing it.
2
91
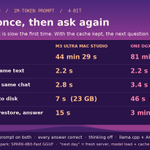
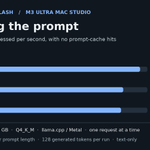
Follow-up on the Hy4 Flash runs from last night. Reading a 1M token prompt took 44 minutes on my Mac Studio M3 Ultra 512gb and 81 on a Spark, so I wanted to know what happens with the second question.
It takes about 2 seconds on both. The server keeps the prompt in its cache, so it only has to read the new question. A follow-up in the same chat was 2.8 seconds on the Mac and 3.4 on the Spark.
You can also save the cache to disk. It is a 23 GB file. I restarted the server, loaded the file and asked a new question. That took 15 seconds on the Mac and a bit over 3 minutes on the Spark, where most of the time is loading the model. So you only need to do the slow read once per document.
@JRB_AI asked why the Spark slows down so much on the long prompts. My first guess was memory, but it is not. The Spark was almost out of memory from the start of the 1M run, and it read less and less from the disk the further it got. The speed follows how deep into the prompt it is. The Spark starts faster than the Mac, they cross at around 200K tokens, and at 1M the Spark reads 122 tok/s where the Mac still does 306. A 512K prompt with 16 GB of memory free was just as slow at the same depth.
I also tried the smaller q8 cache to save memory. On the Spark it read the prompt fine and then answered with nonsense. On the Mac the answers were right but it wrote a lot slower.
@MiaAI_lab @ashxhart are you seeing the same drop on long prompts on the Sparks? This was llama.cpp with the AngelSlim patches, so I'm curious if the TensorFold version will behave the same when it is out.


One behaviour I'm picky about on a laptop: unplug the external monitor, carry on working, plug it back in. On Omarchy I'd want the windows I moved deliberately to stay put and the ones I displaced by pulling a cable to go back.
1
3
275
Omarchy 4.5 lets you choose a traditional desktop instead of tiling. Handy if you're trying to get someone onto Linux. You can show them why you like Omarchy without also having to explain where their window just went.
56
My test for a new Omarchy theme would be to leave the terminal and editor open, go make coffee, then come back and try to tell which one has keyboard focus. It should be obvious which one I am about to type into when I start typing again.
1
1
77