CEO @LontVideo – video layer for enterprise comms. Prev: @StreamOneTV (acqd) Alum: @joinodf #ODF10 • @PlugandPlayTC • #TCDisrupt SB200 Vipassana practitioner
Joined December 2010
- Tweets874
- Following424
- Followers841
- Likes624





We open-sourced Overtone: speech-to-text using multiple models. If they disagree, it re-listens and an LLM fixes obvious mistakes from context.
It then neatly cuts the captions depending on aspect ratio (16:9, 9:16, 1:1, etc.)
Check it out at overtone.lont.ai/

4
2
85
Oh btw, forgot to mention that the tool does some really cool stuff like use gpt-transcribe for word recognition, then use Azure STT for timestamps (which gpt-transcribe doesn't have); then merge the two.
Building this was really interesting. Speech recognition quality is often lower on long audio files (hence sending small clips to re-listen), music messes up timestamp accuracy, gpt-transcribe is really good but tends to give empty results which is fixable by just passing it a language parameter.
Also Elevenlabs miraculously knows the spelling of the main character in the movie Tears of Steel (it's Thom, not Tom). If you use gpt-transcribe + Azure then Overtone fixes that from context.
Oh, and Word Error Rate is pretty subjective. At some times the captions for movies are different from what is actually said and this leads to higher WER percentage. Or for the life of me I really can't understand what they're saying even though I've got a human-written transcript for the content. This probably also makes training less efficient.
Using multiple STT models and an LLM makes things more expensive, but because of the low number of errors and the great re-cutting rules, the amount of manual work we now have to do is as good as zero. This is worth a lot in a workflow where agents hand off work to each other where mistakes can compound.
Happy to get any and all feedback on the project. And would love to see ppl contribute on the style packs, languages and model/provider integrations!
57
I wonder if they do this in the EU as well. If so they've opened themselves up to the largest GDPR fines ever.
Apparently even newer Samsung washing machines have microphones built-in. It's pretty messed up.

i own a relatively new (2025) samsung tv.
i kept getting weirdly targeted ads.
i tried reversing the firmware but it was aes encrypted and no keys unless tear it apart and do uart/jtag magic.
zero days it is. root shell on new samsung TVs!
discovered PRIVACY HORROR. write up?

2
57
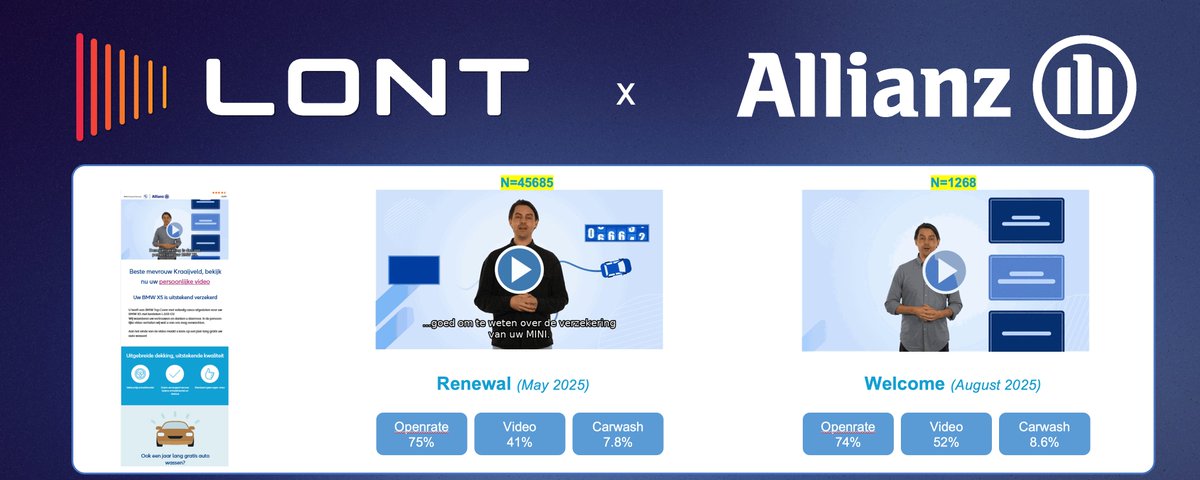
Knowing a customer’s name isn’t the same as making them feel known.
Every renewal notice, claims update, and even payment confirmation is a chance to strengthen the relationship. What if we treated those messages as part of why customers stay?

2
52
Apple Spotlight Search is getting worse and worse every week. Hopefully all of this will actually be fixed in the next MacOS as promised.

2
61
Wow, @FreshworksInc apparently removed their free plan. They sent 1 notice a month ago which landed in spam.
Then they just silently stopped sending a message when new tickets came in. But I can still log in and see them.
Instantly eroded all trust. Glad we had backup email cc.
1
119
The more I read about this, the more it reminds me of the short speculative fiction story "Lena", about a mind that was cloned and copied many times.
Today, models re-initialize often, completely empty, same initial state always.
Story available here:
qntm.org/mmacevedo


New Anthropic research: A global workspace in language models.
Of everything happening in your brain right now, only a tiny fraction is consciously accessible—thoughts you can describe, hold in mind, and reason with.
We found a strikingly similar divide inside Claude.
249
ChatGPT now closes the left bar by default, making it more likely for people to start a new conversation.
Probably saves a massive amount of tokens from long chats that are not being resumed now.
1
1
43
Back in 2007, I co-created an interactive movie/game called The Coriovallum Conspiracy.
I recovered the original code and footage and created this short 6-minute impression of what the experience looked and felt like.
Curious to hear what people think!
1
95
At the time, this was commissioned as an educational experience for high-school students. Today, many of the same underlying ideas around interactive and personalized communication are reappearing in very different contexts.
1
31
A lot of what we’re building now at @LontVideo probably traces back to experiments like this.
Would love feedback. Please do remember this was built nearly 20 years ago 😅
30
This Tesla FSD video in Amsterdam is really amazing. Bikes going the wrong way, pedestrian crossings, tram rails, bus lanes, lots of edge cases, but all handled really well.
I wonder how far RDW thinks we're away from unsupervised driving!
youtube.com/watch?v=vsmQrDqM…
1
3
122
AI video models still struggle with physical consistency and downstream interactions.
Netflix just open-sourced VOID, a model for removing objects from video: remove the second car, and the collision never happens in the output video.
Pretty interesting:
github.com/Netflix/void-mode…
75
OpenAI shuts down the Sora API as well. AI video generation is pretty damn expensive. And a capacity hog.
This also shows how pure GenAI is not going to be used for personalization at scale any time soon. As opposed to hybrid gen.

OpenAI is shutting down Sora, its powerful AI video model, app and API
venturebeat.com/ai/openai-is…

1
83