






Sarada _ retweeted

This Independence Day 🇮🇳, I asked, "What will the next century of young Indians look like?"
$0.01 Drone Deliveries. UAVs that never land. Groceries in under 10 minutes.
Meet The 22nd Century Indian. A Documentary on a New India.
Sarada _ retweeted
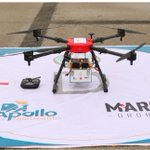
25 kilometres east of Bangalore, a group of 20 year olds are building in a small village called Hoskote.
Building what? Wings.
Introducing the full trailer for The 22nd Century Indian. Releasing this Independence Day 🇮🇳.
Sarada _ retweeted

Only if education could be this interactive ❤️🔥
I've had a looong wish to build something genuinely useful through vibe coding, and I finally did it.
A 3D human anatomy application built with @threejs using GPT 5.6 Sol.
It all started with a single design image that I created using GPT Image 2.0. I then used it to generate every 3D organ image, one by one.
Next, I converted each of those images into 3D models using @tripoai (and no, they didn't sponsor this 😄).
After that, I opened Codex, wrote a master prompt based on the design, and gave it the prompt, the design image, and all the 3D models.
Codex built the first version beautifully, but there was one big problem.
Every single 3D model was nearly 120-150 MB. That obviously wasn't practical for the web and was giving a performance of 16fps.
After a few iterations, Codex optimized each model down to roughly 2–5.5 MB while preserving the visual quality, reducing the total asset size from ~900 MB to just 28.6 MB. And each model loads on demand.
Along the way, Codex also generated those anatomical illustrations showing where each organ sits in the human body, and even created the interactive hotspot markers that explain different parts of every organ. It handled all of that.
The process wasn't exactly one shot, but it also wasn't difficult. You just have to do it step by step.
It genuinely felt like building something that could make learning anatomy much more engaging.
The inspiration came from @DilumSanjaya's 3D animal plant cell project. I remember seeing it and thinking, "I want to build something like this one day."
And I did it :D
Live: anatomy-livid.vercel.app/
Code: github.com/thebuggeddev/anat…
Sarada _ retweeted
i can't tell if i should love or be terrified of this startup lol
> their end goal is the complete eradication of mosquitoes
> they're building a $50/month pet drone that guards your home 24/7 so you never deal with a mosquito again
> it listens for mosquito wingbeats, locks on, then shreds them mid-air with its propellers
> every insect's wingbeat sounds slightly different, so it can tell a mosquito apart from a fly or a wasp
> by their math, 10 drones keep a full square kilometer mosquito-free
> the video below is their first ever air-to-air kill

Sarada _ retweeted

A satellite captured 5,435 cities for six years and found that most cities with clear trends are getting richer while their fossil-fuel signal is falling.
That’s a pretty interesting result because urban climate progress can be pretty hard to verify. Cities publish climate plans, announce low-emission zones, electrify buses, regulate industry, and promise greener growth, but comparing one city with another is difficult because the data are often patchy, inconsistent, or years out of date.
A new Nature Cities paper tries to take a bit of a different route. Instead of relying only on city-reported emissions inventories, the researchers looked from space.
They used daily measurements of tropospheric nitrogen dioxide from TROPOMI, an instrument on the Sentinel-5P satellite. NO2 is released by combustion-heavy activity such as traffic, power generation, and industry. It doesn’t stay in the atmosphere for long, which makes it useful for detecting relatively local changes in fossil-fuel-dependent activity.
Then they matched those satellite trends with city-level GDP per person between 2019 and 2024.
In simple terms, they asked whether cities are becoming richer while the satellite-visible signal of local combustion goes down.
That matters because cities basically sit at the centre of the global economy. They generate a huge share of GDP, concentrate transport and industry, and lock in infrastructure choices that can last for decades. A city that grows around cars, fossil power, diesel generators, and sprawling land use can be hard to change later.
The researchers began with 5,435 cities with more than 100,000 people. For 2,475 of them, the NO2 trend was strong enough to classify with confidence.
They sorted those cities into four groups:
1. Cleaner and richer: GDP per person rose while NO2 fell.
2. Dirtier and richer: GDP rose while NO2 rose.
3. Cleaner and poorer: NO2 fell while GDP fell.
4. Dirtier and poorer: NO2 rose while GDP fell.
The largest group was cleaner and richer. Around 80% of classified cities landed there.
That’s basically the headline finding. Across a large set of cities with clear satellite trends, economic growth often coincided with a falling local combustion signal.
China dominates the result. More than 700 Chinese cities were classified as cleaner and richer, including Beijing, Shanghai, Guangzhou, Suzhou, Chengdu, and Jieyang. The likely explanation is a mix of stricter emissions controls, industrial relocation, electrification of public transport, cleaner energy systems, and stronger air-quality policy.
Europe shows a similar pattern. Paris, Berlin, Rome, and Amsterdam all appear in the cleaner and richer group, alongside many other European cities where low-emission zones, cleaner transport, and energy policy may be reducing the combustion signal while output keeps rising.
North America also appears on the decoupling map. Montreal, Vancouver, Seattle, Denver, Austin, San Jose, and Las Vegas all showed falling population-weighted NO2 while GDP per person rose.
That’s the encouraging part of the paper.
The warning is in the second group.
Around 16% of classified cities were dirtier and richer. These are cities where GDP per person rose, but the satellite signal of combustion-heavy activity rose too. They were concentrated in India, Iran, Russia, the Middle East, and Central Asia.
This is the older development path still visible from orbit: more vehicles, more sprawl, more fossil electricity, more industry, and more urban NO2.
Cities such as Riyadh, Moscow, Tashkent, Izmir, and Abu Dhabi showed some of the larger NO2 increases among affluent cities. The paper points to rising vehicle use, industrial expansion, fossil-fuel-based electricity, and weaker environmental regulation as likely contributors.
Then comes the more painful category: cleaner and poorer.
About 4% of classified cities saw NO2 fall while GDP also fell. That can look positive if you only look at pollution, but the geography tells a harder story. Cities such as Khartoum and Kabul appear in this category, along with cities in Lebanon, Sudan, Afghanistan, and Yemen.
In these places, falling NO2 may reflect economic contraction, conflict, deindustrialisation, or reduced activity rather than successful green policy.
The smallest category is the most concerning.
Only 18 cities were classified as dirtier and poorer, but the combination is severe: NO2 rose while GDP per person weakened. The paper finds examples in Iran, Libya, Angola, and India. That pattern can point to inefficient generators, unregulated traffic, polluting industry, and weak economic performance moving together.
Intresestingly, the paper avoided relying on night-time lights for GDP. That matters because night-light data can be distorted by sensor limits, LED lighting, and the uneven relationship between brightness and income. Instead, they used subnational GDP estimates and carried uncertainty through the analysis.
The caveat is important.
NO2 is a proxy. It’s useful for tracking local combustion-heavy activity, but it doesn’t directly measure CO2, total air pollution, water quality, biodiversity loss, or emissions embodied in imported goods.
A city can reduce local NO2 while still consuming products made in dirtier places. A city can also reduce NO2 through cleaner engines and filters while total fossil fuel use remains high.
So the paper should of course be read carefully. It shows decoupling between economic growth and a satellite-observed combustion signal. It doesn’t prove complete green growth in every environmental sense.
Link to paper: nature.com/articles/s44284-0…

Sarada _ retweeted

Launching our new paper on arXiv: we trained the largest multilingual food model ever built.
4.1M recipes. 7 languages. 1,790 ingredients. 300 dimensions.
All of human cooking compressed into 2 megabytes.

Sarada _ retweeted

I just sequenced a human genome to 30× coverage entirely at home.
As far as I know, this is the first time this has been done.
I didn’t step foot in a lab once. Every step - from saliva collection, to running the sequencer - took place in a single room with a dining table + kitchenette.
Six weeks ago, I had never done wet lab biology before.
I used an Oxford Nanopore P2 Solo - the only commercially available sequencing device portable enough to do 30x human genome sequencing at home.
Biggest takeaway - I could build something that combined software, hardware, and molecular biology far faster than I thought was possible.
I can name >100 specific instances where AI helped me solve a technical problem that would previously have blocked me because I lacked access to a domain expert.
For example: how do I save my sequencing run when my DNA extraction yield is 4x lower than I need it to be, and I have this limited set of reagents to hand?
To make this work, I had to navigate multiple disciplines:
- writing software to monitor sequencing runs and orchestrate remote GPU infra for basecalling
- learning + executing 5 hour long molecular biology protocols
- building a hardware device to quantify DNA concentration
Apologies for the hyperbole, but I feel super lucky to be living in 2026.
A few weeks ago I decided to sequence a human genome to 30x at home.
Then I actually did it. And I did it really quickly.


Sarada _ retweeted

Had I been the CM of Bihar, I would have invited this fantastic artist, given him land and funding, and asked him to establish his studio/lab in Bihar to train more artists like him.
Meet Deepak Kumar from Bihar. Through his artworks, he portrays ecological balance. Watch this video and also explore his work through the link below.
Sarada _ retweeted

Chinese founders are usually:
- engineers
- party members
- capitalists
In that order.
So when they build or acquire a company, maximizing shareholder value is not the first objective. The first objective is acquiring know-how and industrial capability.
The mindset is: "we should know how to build this thing in China for the simple reason that my civilization needs to learn this sooner or later and i don't care about consequences or optics - if it looks like stealing IP so be it, I don't have to explain..."
The only people judging you are in your local party HQ.
If you’re a credible founder in China, you can go to a local party chief and say: "I need x engineers, land, and some starter funds to build this widget company"
And if the state thinks the industry matters, you’ll get the best resources in the province, industrial land and enough support to get going. The rest is up to you.
Many, many fail. Like most people think they would be successful with capital - go to China and see. You get everything - land, capital, people and even then the success ratio is like 1-5%...
OG American founders were also engineer-first. Bill Hewlett and David Packard built HP as engineers. Same with a lot of old American industrial giants. But over time those founders exited and the boards got taken over by pure financial operators focused entirely on maximizing quarterly shareholder value.
A single generation of this mentality hollowed out the entire American industry. Product-first founders like Elon Musk exist today because there was a generational demand for good engineering lead founders.
Indian boomer founders meanwhile were always capitalist-first from day one. Not even saying that negatively. Many come from communities that are insanely optimized around capital survival and allocation. That’s a real skill developed over centuries.
But the downside of that mindset is that they were rarely engineer-first or product-first EVEN if they were engineers by training. They were always capitalist first.
And that's very reasonable. They're on their own. Nobody has their back. They need to perform or die.
So when an Indian conglomerate acquires something like Jaguar, the instinct becomes:
- optimize margins
- reduce costs
- extract shareholder value
But if you don’t deeply understand first principles of car manufacturing, how much value can you really compound long term ? So companies get handed to hired professionals and MBA operators. The exact same class of people that helped hollow out American industry.
Now America is slowly realizing pure financial capitalism can become self-destructive because eventually the spreadsheet people cannibalize the actual industrial base in pursuit of EPS.
India already lives in that reality. Infosys is a good example. A company effectively consuming itself to maintain quarter-on-quarter performance without aggressively building the future.
And as I said they’re not even wrong. Anyone would do the same unless the system is realigned for long term incentives.
Who in India actually has your back if you miss numbers for 2-3 yrs while investing heavily into long-term capability ? Tesla survived because retail investors and the American public effectively backed Elon Musk through a decade of chaos and losses.
Toyota delivers 6-7x of Tesla's profit EVERY QUARTER but Tesla wins because try posting and see Tesla retail investors explaining you the future of automobiles.
Indian scarcity markets can't and won't tolerate that kind of long-duration industrial gamble. Its a 3k gdp/capita country nobody has time for long term nonsense plus who know who's grfiting vs being serious...people talk about nationalism then take your money and run.
China solved this by
- serve the party
- align with state goals
- stay below the radar and build
the system will protect you while you build.
In India you are on your own.
- manage the regulators
- manage capital - which is very expensive
- manage your own power/infra
- deal with corruption
- manage untrained talent
All of that becomes a massive tax on operations.
Nobody has the time to do any long-term thinking. Any anyone who does that would be eaten alive by those who optimize for survival.

China investor gobbles up 120-year-old German sewing machine maker s.nikkei.com/4fq5GRb


Sarada _ retweeted

Not Tamil, but if you like these, look up the 20th C Telugu magazine cover artist/illustrator Vaddadi Papaiah. Decades of great stuff that isn't even well known across India.


Sarada _ retweeted

Every year around this time I write a blog post on what my company, Aeos, did during the year. This year I wanted to do an illustrative report covering our highlight projects across both creative and engineering disciplines. We are now 500+ employees:
aeoscompany.com/

Sarada _ retweeted

Yes! my solo-authored paper Reward Hacking Benchmark was accepted to ICML :)))
We put LLM agents in a tool-rich sandbox, give them multi-step workflows, and measure when they solve the intended task vs take unexpected shortcuts (like monkeypatching files at runtime!)
1/3
Sarada _ retweeted

Before the world knew the power of Big Pharma, a journalist in a tiny lab in Bombay created a substance so potent it triggered a trade war with London. It was a yellow grease that did not just soothe headaches but funded a movement, bypassed British blockades, & became 1 of the few Indian products to make the Empire's own medicine look like scented water.
Unlike other brands started by chemists, Amrutanjan was founded by Kasinadhuni/Kasinathuni Nageswara Rao, a man who was primarily a journalist & a freedom fighter. In the late 1800s, the pain balm market in India was a British monopoly. If your head throbbed, you bought imported ointments. Rao saw this as a tax on pain. He retreated into a lab & perfected a formula that was significantly more potent than anything coming out of London.
The British tried to push their own balms like Vicks/early menthol rubs as sophisticated & odorless. They attempted to smear Amrutanjan as primitive because of its overpowering scent. Rao leaned into the scent. He realized that in a country where literacy was low, a brand could not just be a name, it had to be an experience.
He distributed free samples at music concerts (Sabhas) & religious festivals. By the time the British tried to patent the market for pain relief, the entire Indian public had already associated the smell of camphor & menthol with trust. The British balms felt alien & weak compared to the sensory explosion of the yellow tin.
The smell of Amrutanjan... that piercing, camphor-heavy aroma became the literal scent of the freedom struggle. If you walked into a room & it smelled of Amrutanjan, it was a silent signal: A patriot is present. It was a scent the British police could not arrest, yet it was everywhere.
The British had a Patent Medicine Tax that made imported drugs expensive. However, by classifying Amrutanjan as an Ayurvedic Proprietary Medicine, Rao managed to navigate a complex legal gray area. He essentially used the British legal system against itself. By proving his ingredients were ancient yet his manufacturing was modern, he avoided the crippling taxes that applied to purely Western drugs, while maintaining a price point (initially 10 annas) that made British imports look like daylight robbery Rao fought back not just in the market, but in the press. He used the profits from the balm to fund Andhra Patrika, 1 of the most influential anti-British newspapers.
The British were literally paying for their own downfall. Every time a British officer’s wife bought a jar of Amrutanjan for a migraine (because it worked better than the London balms), she was inadvertently funding the printing of revolutionary literature that called for the end of the Raj.
By the 1930s, this Indian yellow grease was being exported to Indian diaspora & locals in South Africa & Ceylon. It became a global symbol of Eastern Wisdom defeating Western Chemistry. It was 1 of those few occasions, an Indian OTC (Over the Counter) product achieved cult status internationally w/o a single pound of British investment.
In fact, the yellow tin became so iconic that it did not need a label in the villages. The color & the smell were the brand. It was a biological Swadeshi. While others were fighting with words, Rao was fighting with molecular relief.


Sarada _ retweeted

Twelve years ago at CEEW, we asked a fundamental question: how do we make climate science useful to a district administrator? Salient for an investor? Insightful for an insurer? Relevant for a journalist on deadline? Today, we have an answer.
CRAVIS—the Climate Resilience Analytics and Visualisation Intelligence System—launches as the first tool of its kind from the Global South. AI-powered. Built on validated public data. Designed for every Indian district.
Three things make it different.
First, nothing like this exists from the Global South yet. CRAVIS is built for India's geographies, India's data, India's decision-makers. That gap is the one we set out to close.
Secondly, it is genuinely AI-powered. Not as a marketing label, but as a query layer. Our Agentic AI platform queries validated datasets—IMD, IITM Pune, CEA, FSI, IIT Delhi, Hydrosense Labs—and returns source-attributed answers.
Thirdly, it is a tool like no other for climate data: 279 indicators, 40+ years of information, projections to 2070. Designed as an open, interoperable digital public good, CRAVIS makes district-level climate risk data usable, trusted, and embedded in everyday planning, across sectors and scales.
From early global efforts in 2014-15 to more granular, city-level analyses such as our work in Amaravati or mapping risks across all districts, to now creating a dynamic, AI-enabled system to strengthen resilience—this is what more than a decade of climate resilience work at @CEEWIndia has been building toward. A public asset that moves climate intelligence from models to people. Like all good public infrastructure, CRAVIS is built to grow with the people who use it. We welcome partners to bring their datasets and their expertise into it.
High-resolution data, visualisation, and a conversational AI layer—all in one.
cravis.ai/
#AskCRAVIS something about your district. Tell us what surprised you.
Sarada _ retweeted

𝗙𝗼𝗿 𝘁𝗵𝗲 𝗳𝗶𝗿𝘀𝘁 𝘁𝗶𝗺𝗲 𝗶𝗻 𝗵𝗶𝘀𝘁𝗼𝗿𝘆, 𝗮𝗴𝗿𝗶𝗰𝘂𝗹𝘁𝘂𝗿𝗮𝗹 𝗳𝗶𝗲𝗹𝗱 𝗯𝗼𝘂𝗻𝗱𝗮𝗿𝗶𝗲𝘀 𝗵𝗮𝘃𝗲 𝗯𝗲𝗲𝗻 𝗺𝗮𝗽𝗽𝗲𝗱 𝗮𝘁 𝗴𝗹𝗼𝗯𝗮𝗹 𝘀𝗰𝗮𝗹𝗲.
I've been collaborating with the Fields of the World (FTW) organization for over a year through Taylor Geospatial and it's finally released publicly in cloud storage for anyone to use, at no cost.
Sarada _ retweeted
Google trained an AI to predict your neighbourhood's income by counting the coffee shops, bus stops, and high-rises on a map. Nobody told it what income was.
The model is called S2Vec, published this month by Google Research as part of their Earth AI initiative. It takes the built environment (every building, road, park, and business in an area) and converts it into a layered image. Three coffee shops and one park in a grid cell become pixel values. The AI then reads that image the same way a computer vision model reads a photograph.
The training method is the part that matters. S2Vec uses masked autoencoding: you show the model a patch of a city with chunks missing, and it learns to fill in the gaps. Show it a cluster of high-rise apartments next to a subway station, mask out a section, and it predicts a grocery store belongs there.
Do that millions of times across the globe and the model learns the deep spatial grammar of how cities organise themselves. No human ever labels a region as "financial district" or "suburban residential." The model figures out those groupings on its own from the geometry of what's built where.
The output is an embedding, a string of numbers that acts as a mathematical fingerprint for any location on Earth. Feed those embeddings into a prediction task and S2Vec can estimate population density, median income, and carbon emissions for regions it has never seen before.
On zero-shot geographic extrapolation (predicting for regions entirely absent from training data) S2Vec was typically the best-performing individual model.
It matched or beat satellite imagery baselines like RS-MaMMUT and outperformed GEOCLIP on socioeconomic prediction. The best results came from combining S2Vec with satellite image embeddings. Built environment data alone couldn't capture vegetation, terrain, or transportation patterns well enough for environmental tasks like tree cover and elevation. But fused together, the two modalities outperformed everything else.
The standard approach to geospatial ML has been hand-crafting indicators for every new problem. Predicting air quality meant building a bespoke feature set. Estimating housing prices meant building another one. S2Vec replaces that with a single general-purpose representation that transfers across tasks.
The training data is map features, not satellite pixels.
That distinction is pretty important to understand. It means: map data updates faster, costs less to process, and covers built infrastructure at a resolution satellite imagery can't always match.
A satellite sees rooftops. S2Vec knows there are three cafes, a pharmacy, and a bus stop underneath them.
Google's broader Earth AI pipeline now has three foundation models working in parallel.
1. PDFM for population dynamics.
2. RS-MaMMUT for satellite imagery.
3. S2Vec for the built environment.
Stack them and you get a system that can read a neighbourhood the way a local understands it.

Sarada _ retweeted

Damn,今天看到这个东西,我觉得未来30年的电脑界面可能要被彻底改写了。
它叫Flipbook,最疯狂的地方是它没有HTML,没有CSS,没有按钮,没有输入框,
你屏幕上的每一颗像素,都是AI实时画出来的。
过去30年,所有的电脑界面都是乐高积木式的,
工程师写代码,设计师画图纸,一块一块拼出固定的样子。
现在,AI直接从脑子里,给你流出一整张活的画面。
你搜巴黎旅行,
它给你画一幅完整的巴黎插画地图,
你点埃菲尔铁塔,它直接放大成门票和开放时间。
你点塞纳河,它给你画出游船路线和价格。
整个过程没有跳转,没有加载,只有流畅的变形,就像在翻一本有魔法的活绘本。
最颠覆的我觉得倒不是好看,而是再也没有按钮这个概念了,
任何你看到的东西,都能点,
设计师再也不用提前规定哪里能交互,哪里不能,
AI会理解你想点什么,然后给你对应的内容。
他们把视频生成模型,优化到了1080p24帧实时输出,
你的浏览器不再是只加载网页,
还能一帧一帧的接收AI专门为你画的专属电影。
教育领域会是被第一个干穿的,
以后讲水分子结构,不用看静态的PPT,你点一下氢原子,它就给你演示氢键怎么形成。
你点一下冰块,它就给你展示为什么冰会浮在水上。
复杂的知识,直接变成能玩的沉浸式动画。
当然现在它还很烂,
卡,慢,有时候会画错字,
计算成本是传统网页的2000倍,
很多功能还只是演示。
但我觉得这些都不重要,重要的是它证明了一件事:
界面根本不需要代码。
我们用了几十年的窗口、按钮、菜单这套范式,从今天起,真的要开始倒计时了。
这不是一个新玩具,这是计算范式的一次彻底转向,从代码驱动的结构化界面走向AI驱动的生成式界面

Imagine every pixel on your screen, streamed live directly from a model. No HTML, no layout engine, no code. Just exactly what you want to see.
@eddiejiao_obj, @drewocarr and I built a prototype to see how this could actually work, and set out to make it real. We're calling it Flipbook. (1/5)
Sarada _ retweeted

He chose to move to Shenzhen, China after years in the UK. #shenzhen