

Build scrapers without having to manage proxies and headless browsers!
Joined May 2018
- Tweets764
- Following400
- Followers567
- Likes96




You came for data, not to rotate IPs, solve CAPTCHAs and rewrite headers.
Send a URL, get the page back. Proxies, rendering, geotargeting and CAPTCHAs are built in. Most users who try it make their first scrape within 10 minutes.
Request a custom trial: scraperapi.com/solutions/byp…
Collecting Amazon ASINs to track price and availability, enrich a catalogue or watch competitor listings?
In our guide: collect ASINs from search results, turn each into JSON product data, and batch thousands of them.
buff.ly/aWQT2xZ
Ian Williams, our Head of Engineering, on how bot detection tells a bot from a human: four signatures (IP reputation, TLS, browser, behaviour) that all have to pass at once and tell the same story.
Watch the on-demand webinar: buff.ly/t4tVhTZ
Our CEO, Simon Ernst-Sunne, talked to TechFinitive about what AI agents change for businesses that rely on public web data.
Thank you to TechFinitive and Ricardo Oliveira for the conversation.
Read the interview:
buff.ly/tiYWqxM

Getting past Akamai yourself means building proxies, tokens, a sensor-running browser, cookies, and pacing before you see one row of data.
ScraperAPI does that work. Half our engineering keeps it working as sites change.
Free trial, no card needed: buff.ly/Llq83fy
Python requests usually fail against Akamai because the five checks run at once. Fixing one doesn't get you through.
IP reputation, headers and tokens, JavaScript sensors, browser fingerprint, request behaviour.
How to bypass Akamai's bot detection: buff.ly/4F9kpLX

Your scraper ran fine for a week. Then: 403.
Akamai weighs IP reputation, headers, tokens, JavaScript behaviour, and how your browser acts, so a script can pass most checks and still get stopped by one.
Which site is blocking you, and what does the block look like?
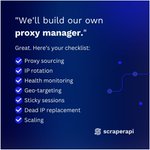
Building a proxy manager is more than IP rotation.
You'll also need proxy sourcing, health monitoring, dead IP replacement, sticky sessions, geo-targeting, and scaling.
See the full build-vs-buy checklist: buff.ly/qsIeNHY
#ScraperAPI #proxymanagement #webscraping

Thinking about switching web scraping tools?
We've compared #ScraperAPI with some of the most popular data collection infrastructures, covering pricing, features, and common use cases.
Take a look before making a decision: buff.ly/SWz3T2F
#webscrapingtools #comparison

No two #AI teams build the same way.
Whether you use MCP, LangChain, LlamaIndex, n8n, or the CLI, your web data layer should fit your stack, not force you to change it.
Find the right #ScraperAPI AI integration for your tech stack: buff.ly/qjn3xqZ
#ScraperAPI #llm

A drop from 4.5⭐️ to 3.9⭐️ is easy to spot.
Understanding why takes a closer look at the reviews.
Learn how to turn customer reviews into structured insights: buff.ly/q7p5xYc
#ScraperAPI #reviewanalysis #dataextraction

Building your own #proxy infrastructure is only the beginning.
Once it's live, you're responsible for monitoring, maintenance, scaling, and everything in between.
Before deciding to build in-house, understand the full operational commitment: buff.ly/qsIeNHY

ScraperAPI backs its infrastructure with enterprise SLAs, zero reported outages, and support that responds in under an hour, because reliable data collection doesn't end with successful requests.
Learn more: buff.ly/BpfwOqM
#ScraperAPI #marketplacedata #webscraping

Your marketplace data shouldn't have a single point of failure.
Whether it's pricing, operations, or commercial strategy, multiple teams depend on consistent access to reliable data.

There's no better validation than hearing how customers use ScraperAPI in the real world.
Feedback like this motivates us to keep building a product that's reliable, accessible, and delivers real value. 💙
#ScraperAPI #capterra #reviews

Stop asking, "What should we build?"
Start asking, "What is the market missing?"
Use competitor websites, customer reviews, and community discussions to validate ideas before you build.
See how #webscraping helps #startup: buff.ly/8knsty
#ScraperAPI

We're hiring a Growth Marketing Specialist at ScraperAPI, fully remote within Europe!
Full details and how to apply: buff.ly/Pot4ek5

If you're building on web data, collecting one version of a page isn't enough.
Learn how to collect the right product data, not just any data: buff.ly/flmbSVD
#ScraperAPI #geoscraping #datacollection

