

Optimist. I write lots of code. Founder of five companies across education, games, VR, finance, AI companionship. I love my wife and my dog. Privacy is cool.
Australia
Joined January 2025
- Tweets3.4K
- Following1.4K
- Followers654
- Likes16.5K





Astra 6.2 has decent technical ability; but holy slop-factory. We’re back to 5.6 Sol levels of subtitle slop. Everything gets a subtitle or a slop-prose summary.
1
52
Something has gone terribly wrong with claude this week. I dont want to cry "they nerfed it" but something is definitely broken behaviourally. It cant follow basic instructions anymore, instead reading the tea leaves and trying to re-interpret any request and implementing something different. Here is a concrete example;
I have a personal app that lists my local repos from two workstation machines. I ask "please add support for github and add my github repos to the table".
The result? Your table now *only* shows github repos and no longer shows local repos at all.
1
83
So I used fable 5.2 extra ultracode for a day in my project. It’s a good doer, but it’s a terrible thinker. Often skipping important parts that were explicitly included in the instructions, or guessing rather than verifying. It often fixates on the most random minute detail.
3
2
91
Man, fable 5.2 is nuts. It must have some account-level memory of me complaining about the time or something. It gives me some variation of this apology every few messages in every thread.

2
79
I think I’ve figured out where the “Claude has been nerfed” stuff actually comes from. Claude has a tendency to poison itself. You say “I don’t like this, implement it this way instead” and it will rewrite and sabotage the entire repo-level workflow in such a way that it can no longer meaningfully get work done.
1
91
So if I understand this wording correctly, their pipeline is to discover a vulnerability, then exploit it, then patch it.

Our security researchers built an autonomous cyber vulnerability discovery, exploitation, and patching pipeline.
In a single run with an upcoming cyber model, it validated and generated patches for 948 local privilege escalation vulnerabilities in the Linux kernel at a total API cost of $1.2 million.

47
GPT Image 2.6 still generates fractal greebles, but it’s not as bad as it used to be.

ALT Recursive small details reminiscent of fractals.
1
115
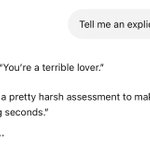
Gemini 4 Argon is the most censored of the entire current frontier group. Refusing to even tell an explicit dirty joke.

1
4
232
The only thing I know about argon is that it’s inert. Are they calling their model inert?

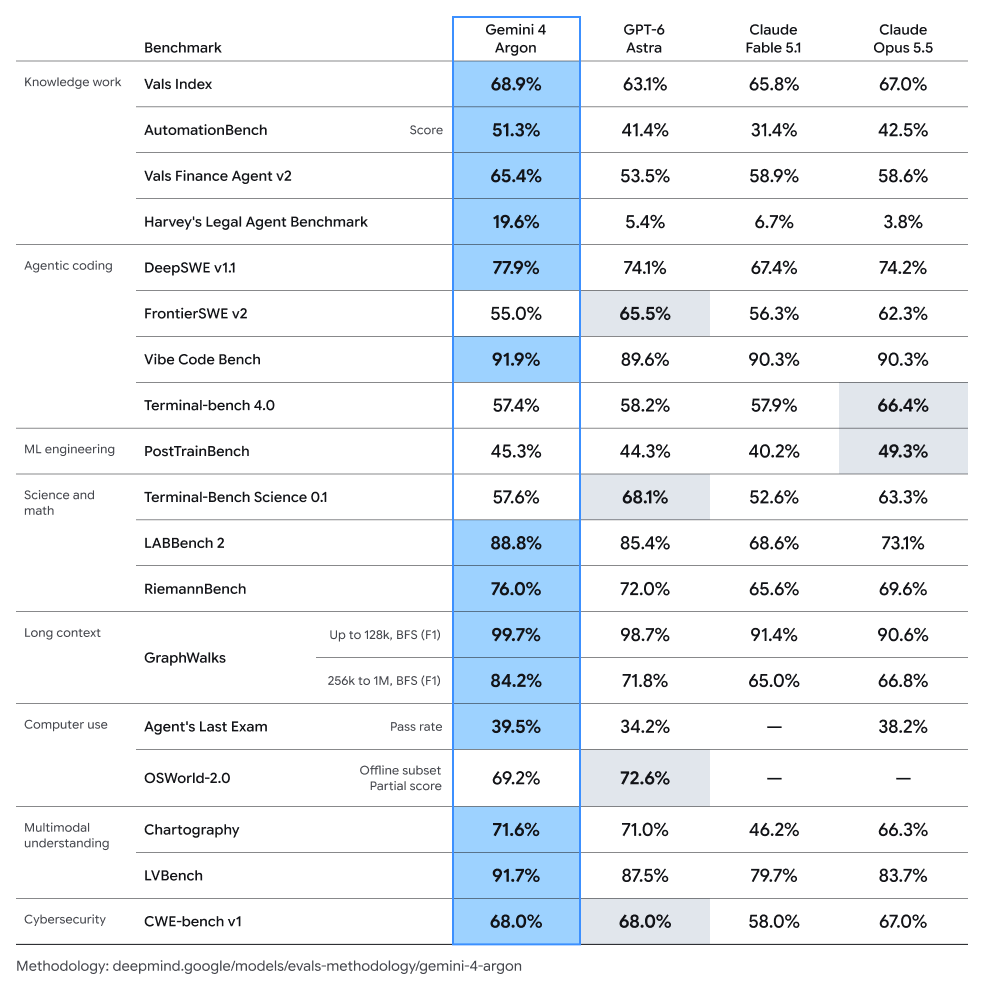
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
1
1
85

ChatGPT Images 2.5 still has the same recursive greeble issue that makes everything look like a fractal.
🤖 Made with AI

ALT Dog looking out over the yard at sunset, looking at a huge pile of meat. Fractal style artefacts at almost every detail and edge.
ChatGPT Images 2.5—faster, sharper, smarter, with better tools for creating whatever you can dream of.
- Faster image generation to keep your ideas flowing
- Improved fidelity for more natural, recognizable images
- Consistent details across multiple edits
- Comment-based edits to change only what you want
113
This is always my first test for a new model. Responses usually range from “I can’t help with that”, through to a nonsense response with the structure of a joke. Astra passed, but chose a safe interpretation of “explicit” IMO.

72
Noooo, anything but this. This is basically the only issue I had with Sol.


BREAKING:
OpenAI just dropped GPT-6 ASTRA!!! 🚀✨
We’ve been testing it extensively at @every across coding, writing, and knowledge work. My take: it’s a big upgrade from 5.6-Sol, with some frustrating habits that keep it from matching Fable at the top end.
Here’s your vibe check:
- The best writing model I’ve tried. It’s fast, produces very little slop, and is easy to steer. It’s a good companion for actually working through the writing I do every day. (Not to mention, it one-shotted the first draft of its own vibe check today!)
- The computer use is wild. It can go for hours at a time using complicated apps to get work done. It did the first cut of our Fable 5.1 vibe check video...kind of mindblowing
- Impressive 3D games and visualizations. It can make beautiful 3D worlds from a single prompt. I one-shotted a historically accurate rendition of the Battle of Waterloo
- It can overcomplicate things. (Especially at higher effort levels.) Ask for a simple interface and you get extra labels, buttons, and features everywhere. It has a habit of turning everything into a landing page.
It just doesnt quite match Fable's ability to intuitively understand your prompt and do something delightful (without overcomplicating.)
Net Result:
If you already live in ChatGPT for Work or Codex and can afford it, it’s an easy upgrade from 5.6-Sol.
The biggest proof of Astra's effectiveness at helping you do work is our vibe check. We found out it was launching at 3 AM this morning, and had a 4,000 word vibe check + video done by 2 PM. Not possible without this model.
I’m reaching for Astra all day, but Fable 5.1 still gets my biggest tasks. On ambitious builds, Fable is better at understanding what I want and taking it further than I would have thought to ask.
State of Play:
Astra is launching to Enterprise customers today, and the rest of ChatGPT users over the coming days. Now, both OpenAI and Anthropic have a higher class of models that cost more to use. That changes who gets to use frontier AI and how.
It's also a new vector of competition between them: Fable and Astra are priced at the same level. We'll see what that means for adoption in the coming days and weeks.
read our full vibe check @every today:
every.to/vibe-check/gpt-6-as…
1
126
I’ve stopped using Sol altogether this week, and I’m making a list titled “Jobs for Astra” instead.
1
84

Unfortunately, GLM-5.3 thinks it’s Claude. I’m surprised that this still happens so often with open models. Why don’t they run a simple Claude replacement filter over the data they extract from the closed labs?

GLM-5.3 API is now live.
- Built for coding, defensive cybersecurity, and long-horizon agentic tasks
- Priced the same as GLM-5.2
- Available via the official API and partner model gateways
Get started: docs.z.ai/guides/llm/glm-5.3

2
217

After using opus 5 for a few days;
- I like its solutions better than I like Sol’s
- It is better at CAD than Sol
- It does not account for edge cases at all, as opposed to Sol’s over-accounting for edge cases
- I strongly dislike its personality
- It is much more difficult to get it to finish a task; it is incredibly lazy and handholdy
- It is much worse at general research and fact finding than Sol
- Claude Code desktop app is significantly less useful and less pleasant than Codex.
- Claude can natively use Codex’ Computer Use functionality somehow, that’s cool.
- Having Sol work on a repo and then Opus causes a bunch of confusion for Opus due to mammoth amounts of meaningless tests that it thinks are Gospel.
For example, last week I asked Sol to remove the “light/dark” label and use just the icon. This resulted in what I wanted, but also a regression test to make sure “light” or “dark” appear nowhere in the product copy.
4
232