

PhD student @VT_CS; Intern @AmazonScience
Corvallis, Oregon
Joined March 2022
- Tweets55
- Following2.5K
- Followers223
- Likes40





Pinned Tweet
🌟New paper alert: The Master Key Hypothesis🌟
Post-training is expensive AND you have to repeat it for every new model. What if you could just transfer the capability instead?
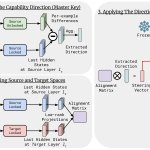
We introduce UNLOCK — a training-free and label-free framework that transfers capabilities across models using low-rank linear projections.
Takeaways:
1⃣ Skills like CoT & math reasoning live as directions in the model's latent space. We capture these as a steering vector — we call this the Master Key.
2⃣ Simple low-rank linear transformations are sufficient to transfer the Master Key across models' latent spaces
3⃣ UNLOCK elicits behaviors that even prompting can't reliably trigger
4⃣ Gains scale with base model strength. Stronger models show larger gains post-transfer.
5⃣ UNLOCK works by sharpening the output distribution — steering the model toward the right answer.

Why are the usage limits for Gemini Argon so miserably low? 5 prompts in with low thinking and I've already hit the limits. @OfficialLoganK
Rishab Bala retweeted

I'm not at @COLM_conf, but my awesome PhD student @noahpro99 is giving a talk on our EvoSkill work today at the COLM Social: Self-Improving Agents (Oct 6 1-2:30 PM PT, Franciscan D). Come chat with him about his first-hand experience with different skill evolution frameworks!


hosting the Self-Improving Agents social at @COLM_conf tomorrow
- 4 talks: @sethkarten @yoonholeee @qinyuan_ye and Noah Provenzano
- panel: @HuaxiuYaoML @ZhiruoW @jasonwu0731
my 4th one after ICLR, ICML and NeurIPS, and I still love hosting these.
1-2:30pm, Franciscan D. come by if you're at COLM
luma.com/m8v4fq76

Accepted to NeurIPS as a Spotlight paper!🎉🎉
Thanks to all my collaborators for their support and feedback!

🌟New paper alert: The Master Key Hypothesis🌟
Post-training is expensive AND you have to repeat it for every new model. What if you could just transfer the capability instead?
We introduce UNLOCK — a training-free and label-free framework that transfers capabilities across models using low-rank linear projections.
Takeaways:
1⃣ Skills like CoT & math reasoning live as directions in the model's latent space. We capture these as a steering vector — we call this the Master Key.
2⃣ Simple low-rank linear transformations are sufficient to transfer the Master Key across models' latent spaces
3⃣ UNLOCK elicits behaviors that even prompting can't reliably trigger
4⃣ Gains scale with base model strength. Stronger models show larger gains post-transfer.
5⃣ UNLOCK works by sharpening the output distribution — steering the model toward the right answer.
Rishab Bala retweeted
Glad to share that our paper on The Master Key Hypothesis / cross-model capability transfer got accepted @NeurIPSConf 2026 as spotlight 🎉 !! Top 1.3% (292 spotlight + 112 oral) out of 30709 submissions. Congrats to my students @Sub_RBala @linusdd44804 @helix9550 and co-authors @mohitban47!!
🌟New paper alert: The Master Key Hypothesis🌟
Post-training is expensive AND you have to repeat it for every new model. What if you could just transfer the capability instead?
We introduce UNLOCK — a training-free and label-free framework that transfers capabilities across models using low-rank linear projections.
Takeaways:
1⃣ Skills like CoT & math reasoning live as directions in the model's latent space. We capture these as a steering vector — we call this the Master Key.
2⃣ Simple low-rank linear transformations are sufficient to transfer the Master Key across models' latent spaces
3⃣ UNLOCK elicits behaviors that even prompting can't reliably trigger
4⃣ Gains scale with base model strength. Stronger models show larger gains post-transfer.
5⃣ UNLOCK works by sharpening the output distribution — steering the model toward the right answer.
Great work! We found something similar in our recent work: arxiv.org/abs/2604.06377. Still surprising that such communication channels exist across models.@mostik_ai @aimalysheva


meet @mostik_ai!
what happens when you put 12 PhDs in one room for four months? first place on the ARC-AGI leaderboard, which I can't say much about while the competition is still running. and this, which I can.
everyone's arguing about whether open models will catch up to frontier models. we think it's the wrong question. here's the one we pose: why does a frontier model have to generate your answer at all, when the only thing you need from it is the reasoning?
we do this by enabling models to communicate in latent space. through our protocol, hidden states pass straight from a frontier model into a small one running on your infrastructure -- no text between them, and neither model is fine-tuned. two models from different families, sharing reasoning, both left untouched.
how do we know it works? we tested it on a setup where a 753B model reads the problem, and a 4B edge-class model writes the answer. with this approach, we get results 80% as accurate as the frontier model, but at 20x faster performance.
we're committed to preventing frontier model lock-in and are already partnering with inference providers to accelerate open-weight adoption. we've done this between 15 of us, in four months, 12 PhDs and a Fields medalist, backed by @generalcatalyst
WIRED has the first external account of the company and the work: wired.com/story/russian-star…
full writeup, the setup, and all the numbers: mostik.ai/read-more

Read/write tool use on Muse 1.3 seems buggy? I found the file with a "find -name" command, but the model can't for some reason. There was no "personal_projects" in the file path either. @alexandr_wang


Rishab Bala retweeted
Nice work by @verma_apurv5 showing that post-training can be distilled into a portable logit delta that transfers across model sizes and families, which corroborates the findings in our recent work on the Master Key Hypothesis (arxiv.org/abs/2604.06377) and fine-tuning/alignment transfer (arxiv.org/abs/2503.20110).

5/8 🔁
Second, the delta is portable. A delta drawn from a 1.5B Qwen lifts Llama-3-8B, a different family with a different tokenizer, by 15% on GSM8K.
Other recent works do weight-space transfer such as task arithmetic (arxiv.org/abs/2212.04089) and the recent Master Key Hypothesis (arxiv.org/abs/2604.06377 by @tuvllms, @Sub_RBala), and typically require same model family. A simple vocabulary bridge is sufficient for logit grafting.

Can someone ELI5 how the J-space is different from steering vectors? Both map from some latent space to the vocab space, and with the right input prefix a steering vector could also act as a "working memory" and predict future tokens.
Rishab Bala retweeted
📢 New Preprint Alert
@SharmaRituraj19 found out a hidden supervision flaw in Looped Language Models: hidden-state norms can grow across iterations, but the LM head hides this from the loss. Exposing or controlling the scale yields more stable training and stronger performance.👇
Paper: arxiv.org/abs/2606.24898
Code: github.com/Rituraj003/readou…


Rishab Bala retweeted

🚨New paper alert:
Can dense supervision control a looped language model, if the loss never sees how large its hidden state grows?
Add loss at every loop, yet the norms blow up into thousands.
The decode layer hides the hidden state’s size from the loss. The readout blind spot 🧵

Rishab Bala retweeted
I am in Rio de Janeiro, Brazil for #ICLR2026 @iclr_conf. Would love to connect and chat about any LLM research topics, explore collaboration, or discuss potential funding opportunities for my lab at @ Virginia Tech.
Rishab Bala retweeted
🌟New paper alert: The Master Key Hypothesis🌟
Post-training is expensive AND you have to repeat it for every new model. What if you could just transfer the capability instead?
We introduce UNLOCK — a training-free and label-free framework that transfers capabilities across models using low-rank linear projections.
Takeaways:
1⃣ Skills like CoT & math reasoning live as directions in the model's latent space. We capture these as a steering vector — we call this the Master Key.
2⃣ Simple low-rank linear transformations are sufficient to transfer the Master Key across models' latent spaces
3⃣ UNLOCK elicits behaviors that even prompting can't reliably trigger
4⃣ Gains scale with base model strength. Stronger models show larger gains post-transfer.
5⃣ UNLOCK works by sharpening the output distribution — steering the model toward the right answer.
Based on our findings, we introduce the Master Key Hypothesis and postulate the convergence of capability representations across model families and scales.

Work done in collaboration with @linusdd44804 @SharmaRituraj19 @anjiefang, Fardin Abdi, Viktor Rozgic, Zheng Du, @mohitban47, @tuvllms
Paper: arxiv.org/abs/2604.06377
GitHub: github.com/rishabbala/Steeri…