
Researcher at Imec AI Labs. Continual Learning Vision/LLMs. Prev. Postdoc. @Mila_Quebec, PhD @IP_Paris_
Berlin
Joined February 2015
- Tweets882
- Following764
- Followers1.3K
- Likes1.8K


The scientist used to stand between nature and human understanding. Tomorrow they will stand between AGI's understanding of nature and our own.
7
317
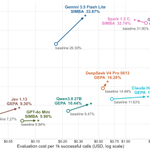
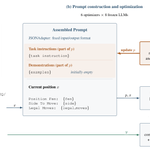
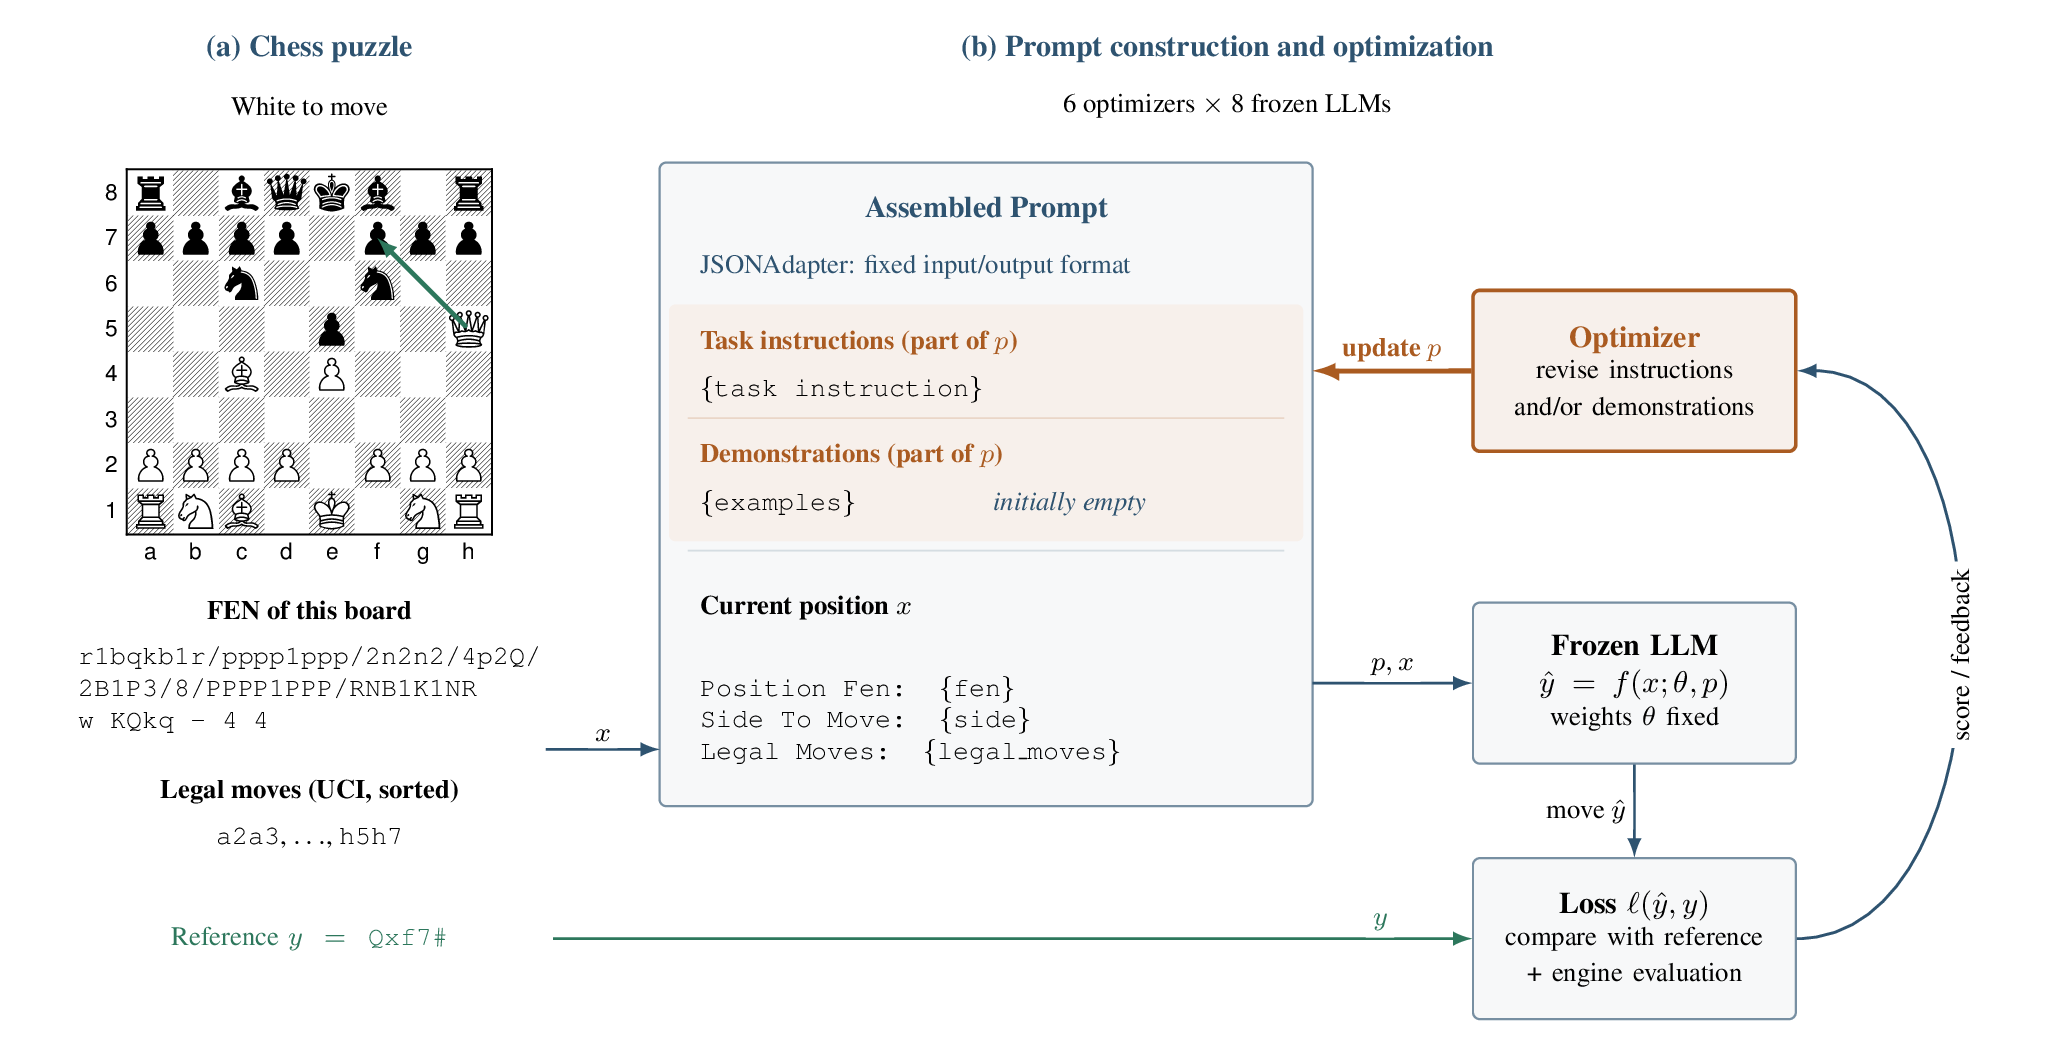
You can now navigate and explore the prompts that makes LLMs play better chess !
imec-ailabs.github.io/Automa…

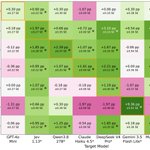
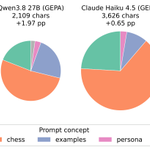
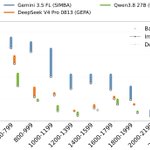
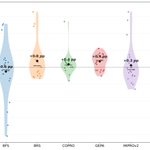
Automatic prompt optimization (APO) is one of the most efficient levers for boosting LLM and agent performance — but measuring real gains is surprisingly tricky.
Glad to share from @imec_int AI.labs: "Benchmarking Prompt Optimization of Large Language Models With Chess"
🧵
1
114
Automatic prompt optimization (APO) is one of the most efficient levers for boosting LLM and agent performance — but measuring real gains is surprisingly tricky.
Glad to share from @imec_int AI.labs: "Benchmarking Prompt Optimization of Large Language Models With Chess"
🧵
After 5 years away from Paris, in Montreal and Berlin, I am excited to announce that I am back! 🎉
I am starting as a researcher in the freshly created IMEC AILABS at @imec_int 🚀
We will work on pushing the frontier of AI research and building creative innovations 🎈
4
165
@giffmana I went to your talk at "Datasets for Foundation Models" workshop in ICML last Saturday (nice talk btw ;) ), I was wondering, to what extent is it possible to transfer work done in LLMs for improving eval, optimization, and scaling to Vision pretraining?
1
3
251
My company is hiring a senior Data Scientist for Large Scale Machine Learning.
aignostics.jobs.personio.de/…
We are in Berlin and work on ML with biomedical data to improve precision medicine.
If you are at #ICML2024 and would like to discuss send me a pm.
8
527
I will be in Vienna for the time of #ICML2024. Tomorrow I will be at the 7th workshop on Neural Scaling Laws. Send me a pm if you want to have a chat on Continual Learning, SSL for language/vision or training at scale :)

Registration is open for our next #ScalingLawsWorkshop next week.
📅 Monday July, 22
📍in person : Vienna (#ICML)
📍 Remotely : Via Zoom
🗒️ Free (but mandatory) Registration : shorturl.at/FQ0DM
#CERCAAI

12
1,016
Yesterday was organized the "gathering of the greatest French AI talents" at @Elysee . I was honored to be invited by @EmmanuelMacron. Inspiring discussions around France and Europe's recent progress in AI and together becoming one of the leaders of AI.


17
977
Do not forget to submit your paper to our special session on "Continual Improvement of Deep Neural Networks in The Age of Big Data" at ESANN 2024 before 02.05.2024. A great opportunity to share and discuss your work and ideas with the community!
[1/2] I am glad to announce that with Prof. Alexander Gepperth, we will organize the special session,
"Continual Improvement of Deep Neural Networks in The Age of Big Data" at ESANN 2024 (esann.org/special-sessions#s…). (Submission Deadline: 02.05.2024)
1
472
Look at our preprint on Continual Learning for increasing the scalability of LLMs pretraining. A great piece of work led by @ai_phd @benjamintherien and @kshitijkgupta
🔥

Interested in seamlessly updating your #LLM on new datasets to avoid wasting previous efforts & compute, all while maintaining performance on past data? Excited to present Simple and Scalable Strategies to Continually Pre-train Large Language Models! 🧵arxiv.org/abs/2403.08763 1/N

Thanks for featuring our work on continual learning for LLMs pretraining @_akhaliq much appreciated 🚀 🎉😀

Simple and Scalable Strategies to Continually Pre-train Large Language Models
Large language models (LLMs) are routinely pre-trained on billions of tokens, only to start the process over again once new data becomes available. A much more efficient solution is to continually

12
764
[1/N] We are glad to announce the release of the new version of our article
"Continual Learning Under Language Shift" with @EviGogoulou, Magnus Boman, and @JoakimNivre with whom I had the pleasure to collaborate.
arxiv.org/abs/2311.01200

I like to see continual learning (learning without forgetting) as sharing compute and data through time and federated learning as sharing compute and data through agents. In both cases, it should help scaling and improving our baselines 🚀

.@JeffDean, chief scientist, @Google DeepMind and Google Research, Grace Chung, Site Lead, and Engineering Director, Google Australia, and @ManishGuptaMG1, Director of Google Research India talk about large language models and the current AI landscape. @ETtech @EconomicTimes
11
607
[1/2] I am glad to announce that with Prof. Alexander Gepperth, we will organize the special session,
"Continual Improvement of Deep Neural Networks in The Age of Big Data" at ESANN 2024 (esann.org/special-sessions#s…). (Submission Deadline: 02.05.2024)
Look at the blogpost of our latest work at @cerc_aai on continual pretraining of large language models 🔥🚀
w. @kshitijkgupta @benjamintherien @ai_phd @M_L_Richter @QuentinAnthon15, @ebelilov, and @irinarish (PI).

More (belated) Xmas (or New Year :) presents for y'all! 🎁🥂🎉
Our @cerc_aai team @UMontreal (irina-lab.ai), jointly with our virtual @AGICollective community, is excited to announce the first release of CL-FoMo (Continually-Learning Foundation Models) suite of open-source LLMs (more coming soon!) Blog/models/code/paper: tinyurl.com/CL-FoMos
1
6
711
I am glad to share that I started a new job as Senior Data Scientist at @AIgnostics in Berlin.
This is an exciting new adventure to contribute to AI-powered tools to diagnose pathologies.
1
25
1,596
I had a great time as a Postdoc at @UMontreal and @Mila_Quebec . Thanks a lot to @irinarish for your support and all the opportunities to do impactful research.
2
5
355
The code is now available at:
github.com/TLESORT/SCoLe
To reproduce the paper experiments on SCoLe scenarios or create new ones!
We are glad to announce that our paper: "Challenging Common Assumptions about Catastrophic Forgetting" co-authored with @ostap__alex, @__z__9, @rarefin15, @prlz77 , @lcharlin , @irinarish has been accepted to @Collas2023.
(arXiv arxiv.org/abs/2207.04543)
[A thread (1/N)]

2
293
Last year was lit, great talks and great continual learning community🔥

Ditch the traditional single-distribution learning and soak up some fresh perspectives in Montreal this summer! 🌞Join us at #CoLLAs2023 from August 22 to 25. See you where non-i.i.d. learning meets poutine! 🧠🍟 Register here: lifelong-ml.cc/

10
1,203
We are glad to announce that our paper: "Challenging Common Assumptions about Catastrophic Forgetting" co-authored with @ostap__alex, @__z__9, @rarefin15, @prlz77 , @lcharlin , @irinarish has been accepted to @Collas2023.
(arXiv arxiv.org/abs/2207.04543)
[A thread (1/N)]