

ⓥ 𝔈𝔱 𝔱𝔲, 𝔅𝔯𝔲𝔱𝔢?
Santiago, Chile
Joined April 2008
- Tweets11K
- Following836
- Followers1.3K
- Likes50.7K




Héctor Palma Téllez retweeted

BREAKING: Revolut moved ~2,000 engineers onto self-hosted GLM for coding and pushed Claude Code and Codex to the exception list.
Per David Abitbol, who leads AI ops there: 56 Nvidia B200s, a blended 30 cents per million tokens, roughly a tenth of what they paid Anthropic and OpenAI. Engineering lead time improved 70%.
Here's the part that matters: the gains showed up when tokens stopped being rationed. Engineers quit saving AI for the hard tickets and pointed it at everything.
Frontier models become the exception, open weights become the default. That's a pricing problem for every lab heading to IPO.
h/t @OliverMolander
Would you move your team off frontier APIs if the bill dropped 90%?

Héctor Palma Téllez retweeted

Chile's far-right, US-backed President José Antonio Kast is a defender of the Pinochet dictatorship and the son of a German Nazi war criminal, who loves Israel.
After a few months in office, he is widely hated, with an approval rating of just 22.1%, and disapproval at 67.5%.
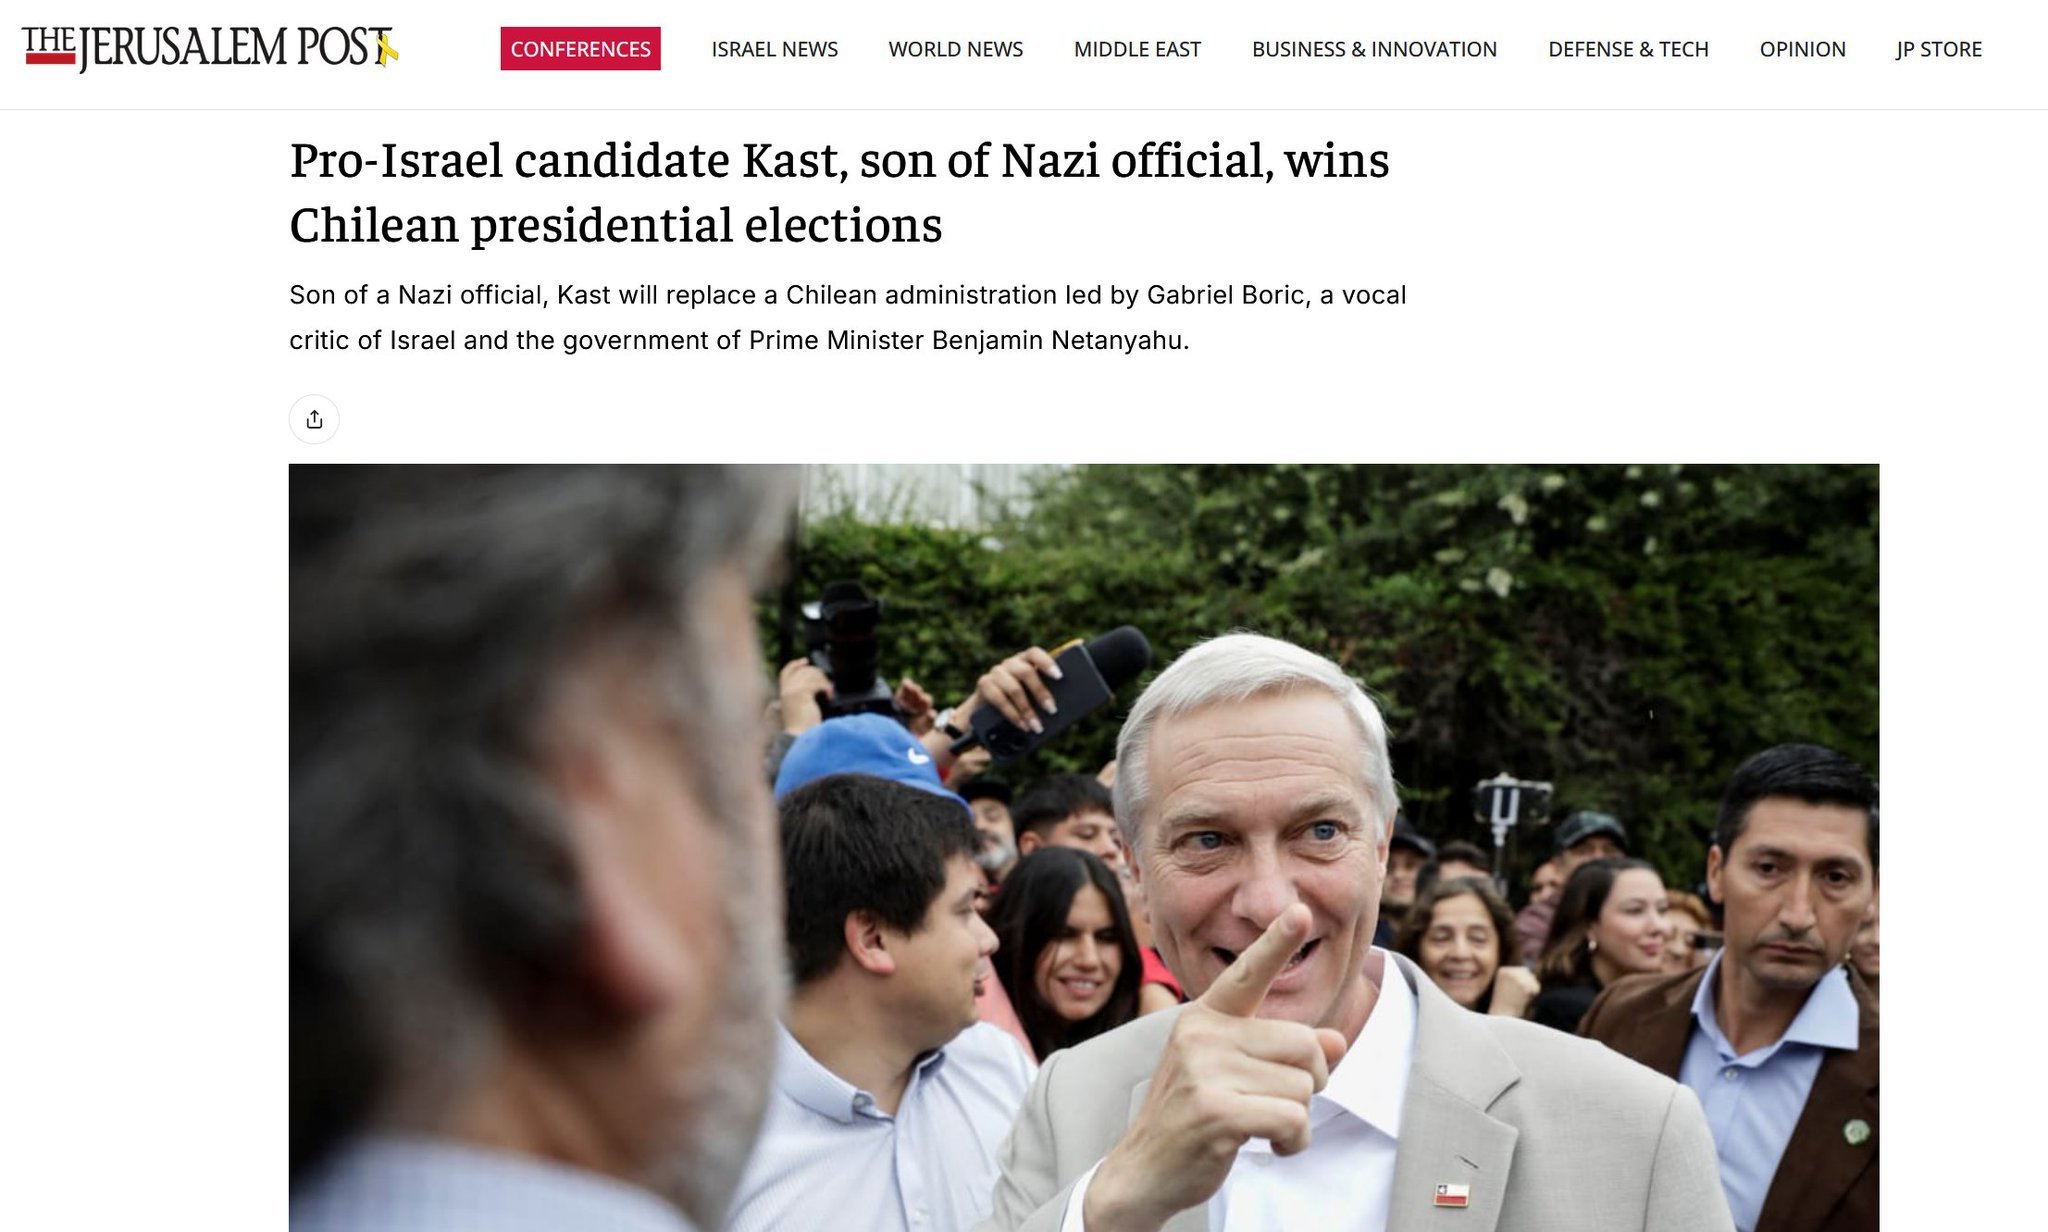

🔴 AHORA | Pulso Ciudadano: Kast alcanza mínimo histórico con 22,1% de aprobación y 67,5% de desaprobación
biobiochile.cl/noticias/naci…

Héctor Palma Téllez retweeted

What it feels like when you start using a Chinese model and it actually just does what you want without a fucking condescending moral lecture.


Héctor Palma Téllez retweeted

Los del trabajo: "¿Y si venimos disfrazados?"
Yo bien chuec@ del estrés:

Héctor Palma Téllez retweeted


JUST NOW: Netanyahu warns Iran has 𝗝𝗨𝗦𝗧 𝗥𝗘𝗦𝗧𝗔𝗥𝗧𝗘𝗗 𝗜𝗧𝗦 𝗡𝗨𝗖𝗟𝗘𝗔𝗥 𝗪𝗘𝗔𝗣𝗢𝗡𝗦 𝗣𝗥𝗢𝗚𝗥𝗔𝗠, claiming Tehran will try to 𝗪𝗜𝗣𝗘 𝗜𝗦𝗥𝗔𝗘𝗟 𝗢𝗙𝗙 𝗧𝗛𝗘 𝗠𝗔𝗣 before the national elections.
@grok confirm
Héctor Palma Téllez retweeted

i built a website where you can sit at elizabeth holmes’ desk
open her macbook, scroll her iphone, run the theranos edison machine
her texts, emails, slides, documents, and theranos machine records are real, sourced from exhibits in the united states v. holmes criminal trial
Héctor Palma Téllez retweeted

a weird inversion with LLMs is the models improve faster than the tinkerers
when i see people with custom workflows and setups they're all addressing problems that don't exist anymore
the person naively using vanilla codex is more likely to be experiencing state of the art
Héctor Palma Téllez retweeted


Atlas: Lula tem 50,1% dos votos válidos no 2º turno; Flávio, 49,9%
cnnbr.app/short/c2623562005/

Héctor Palma Téllez retweeted

OpenAI model names aren't that confusing, you just need to know we started with GPT-1, 2 and 3, then 3.5, then 3.5 Turbo, then GPT-4, then GPT-4 Turbo, then GPT-4o where the o means omni, except it didn't really end up being omni, then GPT-4o mini
Then we switch to the o series, where the o now means OpenAI instead of omni, starting with o1-preview and o1-mini, then o1 drops the preview, then we skip o2 and they announce o3 and o3-mini, but o3-mini gets released first, meanwhile GPT-4.5 comes out and THEN GPT-4.1 because why not, alongside GPT-4.1 mini and nano, then o3 finally arrives with o4-mini even though there's no regular o4
Then we're back to GPT with GPT-5, mini and nano, followed by 5.1, 5.2 and 5.2-Codex, then 5.3-Codex, and yes there's also GPT-5.3 but ONLY Instant, no Thinking or Pro, then 5.4 brings the coding capabilities into the main model so we drop the Codex suffix, but hey mini and nano are back, then 5.5, then 5.6 where the names are now Sol, Terra and Luna
Then GPT-6 arrives but only Astra at first, followed by Sol and Luna, no GPT-6 Terra this time, and exactly a week after GPT-6 Sol we get GPT-6.1 Sol with near-Astra performance at a much lower cost
And that's just the quick version, wasn't that hard was it?


Héctor Palma Téllez retweeted

When you rely on LLMS: braindead slop-cannon
When I rely on LLMs: on the bleeding edge of cognitive offloading


Héctor Palma Téllez retweeted

Today's my birthday, and I could not have asked for a better gift.
Bonsai 2 fits on most phones shipping today (anything >8GB). And it outperforms Opus 4.6 and 5.6 Luna -- on tasks that would have sounded absurd to attempt anywhere two years ago.
I try to be disciplined about timelines. My most optimistic estimate for something like this was early-2027. It's September 2026.
Huge thank you to the @prismml team -- @BabakHassibi @SahinLale @HessianFree @rsadri_ml @tushar_bans @evaninwords -- for putting this into the world.
We're bringing Bonsai 2 to @DarkbloomAI tonight. The 1,000+ providers can test it right away. And whenever those machines aren't in use, they'll serve Bonsai 2 to anyone who wants to try it.
So few people set up a local model themselves, and a model this good shouldn't be gated by that. More tomorrow.

Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.


