
Assistant Professor @PhysicsRutgers
Newark, NJ
Joined January 2019
- Tweets113
- Following121
- Followers106
- Likes186


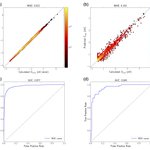


New preprint: a neural denoiser lets CTQMC-based DMFT run with 10-100x fewer Monte Carlo measurements, while keeping the exact impurity solver in the loop.

arxiv.org/abs/2610.28542
The trick: the network outputs an auxiliary spectral function, so the denoised Green's function is causal and normalized by construction. A CRM-style refinement then pins it to the measured self-energy moments and occupation. Noise never reaches the Dyson equation unchecked.
SrVO3 in DFT+DMFT: 10^5 measurements plus denoising reproduce the A(k,w) of a 5x10^6-measurement reference, Hubbard bands included, at 50x less solver time. The raw 10^5 run loses the Hubbard bands entirely.

Li Zhu retweeted

🏆 Congratulations to our very own Prof. Li Zhu on receiving the
👉 2026 CALYPSO-Elsevier Rising Star Award
recognizing early-career leaders in computational materials discovery. His group uses machine learning and first-principles theory to find new materials. 👏👏👏


Li Zhu retweeted

Our arxiv preprint is already making a splash! Number 2 out of 57 for March submissions in chemical physics! #compchem

Li Zhu retweeted

Physics is the backbone of electronics ⚡ From semiconductors to signals, understanding physical laws turns raw materials into the devices that power our modern world. No physics, no electronics.
Machine learning meets Earth science: new preprint uses ML-accelerated DFT+DMFT to model iron’s melting at core conditions (~330 GPa, ~6225 K). A step toward scalable correlated simulations of materials under extreme conditions. Read here ➡️ arxiv.org/abs/2512.25061

Li Zhu retweeted
Wonder how to push #QMMM to chemical accuracy?
➡️ Ab Initio is the only way!
Thanks Jessica, Xin, Xuecheng and Marc for this rigorous and impactful work! Thanks @PaesaniLab @MateriaLab_BSU for collaborating, and @NSF for funding!
pubs.acs.org/doi/10.1021/acs…

Li Zhu retweeted

🚨 New paper alert!
👉 doi.org/10.1021/acs.jctc.5c0…
Led by the Pavanello group, we combined subsystem #DFT with our MB-pol #datadriven #manybody #water potential to push the frontiers of multiscale modeling! 🖥️
Our analyses demonstrate how an accurate #quantum embedding scheme integrated with MB-pol #water achieves chemical accuracy in solution 🌊, thus bridging the gap between full #QM and #MM simulations. 🏄♀️
Exciting collaboration with @MikPavanello and @MateriaLab_BSU groups!
Big thanks to @NSF for funding!
@UCSanDiego @UCSDPhySci @UCSDChemBiochem @HDSIUCSD @SDSC_UCSD

Welcome to our new high school interns, Alex Fu from Union County Magnet High School and Collins Esubonteng from Science Park High School. We are excited to have them join our group!

Li Zhu retweeted
How to keep academia relevant? What's the future of STEM scholarly publishing? I am bringing together librarians, researchers, educators and publisher to try to figure it out. @RULibraries @RutgersSASN @PhysicsRutgers @Princeton @AIP_Publishing

Li Zhu retweeted

🚀my suggestions to boost American STEM to @DOGE_NSF:
* scientific publications open-access; cap on cost/paper to mitigate excessive extraction from scientific publishers.
* research proposals 3-5 pages, not 15 pages. (researchers spend too much time writing proposals rather than doing research.)
* simplify proposal requirements; the proposal and award policies and procedures guide is absurdly 215 pages.
* try to distinguish training from research. this might re-allocate $ to more permanent researchers rather than fresh-start PhD students who only work on a problem for five years while distracted by courses and exams.
* reduce excessive overhead and tuition charged (even when students are not taking courses) by universities.
* remove broader impacts requirement for every proposal, which ~requires outreach. some profs. are specialized, skilled, and excited about this, some are not. have special, optional supplement grants for these activities.
* a cap on proposals per PI.
* eliminate the awful NSF SciEnv to format our CV.
* yearly reporting burden could be reduced and simplified.
Li Zhu retweeted
✅ Do you have a PhD in #compchem or #physics?
✅ Is electronic structure your obsession?
✅ Do you love to code?
➡️ You should join us for a #postdoc!
jobs.rutgers.edu/postings/24…
Excited to share our new paper in JPCL! @JPhysChem @PhysicsRutgers: We introduce EOSnet, a GNN framework that leverages Gaussian Overlap Matrix to capture many-body interactions for accurate material property predictions.
#MachineLearning #MaterialScience

Link to the paper:
pubs.acs.org/doi/full/10.102…

It's great to know that VASP has included a Python plugin infrastructure in version 6.5, but I need to pay more to upgrade the license. Maybe I will stick with QEpy instead.
Li Zhu retweeted

Introducing Meta’s Open Materials 2024 (OMat24) Dataset and Models! All under permissive open licenses for commercial and non-commercial use!
Paper: arxiv.org/abs/2410.12771
Dataset: huggingface.co/datasets/fair…
Models: huggingface.co/fairchem/OMAT…
🧵1/x

Li Zhu retweeted
Join us on November 12 at 3PM for our Graduate Open House!
- poster session
- department presentations
- lab tours
- fun!!!

Li Zhu retweeted

Advancing molecular optimization with language models and prompt engineering
Molecular optimization is an essential step in drug and material design, requiring the balancing of multiple properties such as efficacy, safety, and stability. Traditionally, this process has relied on computational chemistry and expert judgment, often constrained by limited multiproperty-labeled data and the inherent complexity of molecular structures.
In a recent development, Wu et al. present Prompt-MolOpt, an AI-driven framework that employs large language models (LLMs) and prompt engineering to address multiproperty molecular optimization in drug discovery and materials science. Unlike conventional models, which often require separate methods for each property and are hindered by limited data, Prompt-MolOpt generalizes across single- and multiproperty datasets, offering a flexible solution for chemical design.
The model performs well in few-shot and zero-shot learning settings by using prompt-based embeddings to guide molecular transformations, even when data is sparse. In comparisons with established methods such as JTNN, hierG2G, and Modof, Prompt-MolOpt demonstrated a 15% improvement in multiproperty optimization success rates.
Paper: nature.com/articles/s42256-0…
