
PhD in @Berkeley_ai and @BerkeleyNLP. Previously @UNCNLP and @MSFTResearch.
Berkeley, CA
Joined February 2019
- Tweets142
- Following591
- Followers1.8K
- Likes154



Zineng Tang retweeted

Want to know who's the most cited person in ICLR 2027, and which submissions cite your paper?
I downloaded all 43,013 public ICLR 2027 submissions through the OpenReview API and asked my good friends Codex and Claude to build a site that ranks the most-cited papers and authors.
#1 paper is not Attention Is All You Need 👀
Link: modal-labs-leon-dev--iclr202…

Zineng Tang retweeted
Come hang out at our #COLM2026 workshop on Oct 9!
LSEI asks how LMs can learn by interacting w/ the world and other agents!
We’ve got an exciting speaker lineup and plenty to discuss. Bring your questions & hot takes! 🔥
📍 Hilton SF Union Sq, 15&16
🔗 learning-situated-interactio…

Come hang out at our #COLM2026 workshop on Oct 9!
LSEI asks how LMs can learn by interacting w/ the world and other agents!
We’ve got an exciting speaker lineup and plenty to discuss. Bring your questions & hot takes! 🔥
📍 Hilton SF Union Sq, 15&16
🔗 learning-situated-interactio…
Check out our paper at COLM 2026. We make (world-model based) controller language-instructable. It needs no manual labels with rollouts + our pos-hoc annotation method. The result is a flexible controller interface that any VLM/human can plug into.
zinengtang.github.io/instruc…

Zineng Tang retweeted

Excited to announce the first workshop on Learning from Situated and Embodied Interaction @ #COLM2026! 👥🤖🎉
What can interaction with environments, humans, and other agents teach language models that passive text cannot?
🔗 learning-situated-interactio…
📅 Submit by June 30th!

Zineng Tang retweeted

Join our COLM workshop on learning from situated and embodied interactions! Now accepting papers 📢
Interaction with environments, humans, and other agents can serve as an important learning signal for language models. We welcome paper submissions on anything related to learning from interactions (including embodied, multi-turn, multi-agent contexts), cooperative AI, social learning, pragmatics, and more!

Excited to announce LSEI @ COLM 2026: Workshop on Learning from Situated and Embodied Interaction, happening in San Francisco on Oct 9!
We study how interaction can serve as a learning signal for language models.
Deadline: June 23, 2026
CFP: learning-situated-interactio…
(1/2)
Zineng Tang retweeted
Excited to announce LSEI @ COLM 2026: Workshop on Learning from Situated and Embodied Interaction, happening in San Francisco on Oct 9!
We study how interaction can serve as a learning signal for language models.
Deadline: June 23, 2026
CFP: learning-situated-interactio…
(1/2)
Excited to announce LSEI @ COLM 2026: Workshop on Learning from Situated and Embodied Interaction, happening in San Francisco on Oct 9!
We study how interaction can serve as a learning signal for language models.
Deadline: June 23, 2026
CFP: learning-situated-interactio…
(1/2)
Here is the submission portal: openreview.net/group?id=colm…
We’re also looking for reviewers, DM me or submit the form if interested!
docs.google.com/forms/d/e/1F…
(2/2)
2
621
Zineng Tang retweeted

🚨Announcing Zebra-CoT, a large-scale dataset of high quality interleaved image-text reasoning traces 📜. Humans often draw visual aids like diagrams when solving problems, but existing VLMs reason mostly in pure text. 1/n

Zineng Tang retweeted
CoT transformed text reasoning. What about multimodal? 🤔 Check out our new dataset of interleaved text and image reasoning traces. We also show interesting visual CoT examples generated inherently by the model finetuned on our dataset!

Zineng Tang retweeted
Excited to share our new work!
DOVE 🕊️: a dynamic vision encoder that adapts token count to image complexity. Fewer tokens, same fidelity—outperforming fixed-length AEs tokenizer on classification & VLM tasks!
Arxiv: arxiv.org/abs/2506.03643
Web: dove-encoder.github.io/dove-…
#AI #CV

Excited to share our new work!
DOVE 🕊️: a dynamic vision encoder that adapts token count to image complexity. Fewer tokens, same fidelity—outperforming fixed-length AEs tokenizer on classification & VLM tasks!
Arxiv: arxiv.org/abs/2506.03643
Web: dove-encoder.github.io/dove-…
#AI #CV
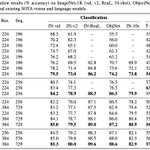
🔥 DOVE uses 68 % fewer tokens but has better FID than VQGAN/TiTok and +10–12 pts on VQA/ImageNet/CIFAR. It achieves significantly stronger performance on classification, probing, and VLM tasks.
DOVE also brings emerging properties—PCA heatmaps reveal sharper segmentation.


1
3
502
We are thrilled to announce TULIP!
🌷 tulip-berkeley.github.io/
A state of the vision language encoders coupled with generative model for stronger representation learning.

TULIP achieves state-of-the-art performance across multiple vision and vision-language benchmarks. It significantly improves zero-shot classification on ImageNet-1K, enhances fine-grained object recognition, and boosts multimodal reasoning scores. Compared to existing methods, TULIP shows up to a 3× improvement on MMVP and a 2× boost in fine-tuned vision tasks.

Also thanks to, @LongTonyLian, Seun Eisape (seuneisape.github.io), @XDWang101, @roeiherzig, @Yalatweets, @alsuhr, and @trevordarrell for their great efforts!
1
5
682

