

🫳💙💜💗❤️🖤 6~11월 ✈️ 헤더:해요님🤍 선차단=(뒷말 방지용 선캡쳐 후, 맞차단)
Joined December 2024
- Tweets20.4K
- Following372
- Followers1.2K
- Likes72.7K



A few technical points that I think need clarification:
ㅡ
1. Using YouTube Embed for video and live chat
The video player and live chat can be embedded separately. They don't necessarily need to be retrieved through an API.
2. Retrieving video and chat through the official API
The video is generally handled through the YouTube iframe Embed Player, while live chat can be integrated separately through chat embedding or the YouTube Data API.
3. Extracting clean audio from the studio
To obtain audio with minimal loss, there would need to be a separate audio feed with direct access to the studio's audio output.
4. Translation arriving instantly
Both STT and the translation process introduce processing latency. The translated text doesn't arrive instantaneously.
5. Manually adjusting translation speed
This is more accurately described as manually adjusting subtitle display delay or the synchronization offset, rather than changing the translation speed itself.
6. API costs being under IDR 150,000 per live broadcast
This depends on several factors, including audio duration, the STT model being used, and the amount of translation API usage. Without those details, it's difficult to make a reliable cost estimate.
7. The server infrastructure being the most difficult and expensive part because of tens of thousands of concurrent viewers
If both video and live chat are embedded directly from YouTube, YouTube handles the video delivery and streaming traffic.
The main sources of server load for Livecap would instead include:
Concurrent user requests to the website
Real-time distribution of translated subtitles(e.g. through WebSockets)
User-specific subtitle settings and synchronization data
Translation data processing and caching
Connection management and server-side error handling
Of course, when tens of thousands of users access the service simultaneously, distributed processing and server scaling become increasingly important. However, it would be inaccurate to suggest that Livecap's own servers are responsible for handling the video streaming traffic as well, assuming the YouTube Embed architecture described above is actually being used.
8. Training the translation API with PLAVE-specific vocabulary
Strictly speaking, retraining the translation model isn't necessarily required to handle PLAVE-specific terminology.
There are several other approaches:
Custom Glossary: Registering proper nouns and specialized terminology in a dedicated glossary
Prompt Context: Providing PLAVE-related terminology and contextual information before translation
Post-processing: Automatically replacing or correcting specific terms in the translated output
NER(Named Entity Recognition): Identifying and preserving proper nouns during the translation process.
For example, terms such as Caligo, PLLI, and Dduks could be protected from being unnecessarily altered or mistranslated during translation.
I think these are important technical distinctions when discussing the architecture. Some of the explanations are reasonable in principle, but the roles of embedding, APIs, streaming infrastructure, and translation processing need to be distinguished more precisely:)


블래스트가 기존 스튜디오 외부에서도 실연자의 움직임을 실시간 캐릭터로 구현하고 송출할 수 있는 별도의 운용 환경을 마련한 것으로 추정된다.
언리얼 엔진 기반의 자체 기술을 활용하더라도 모션 캡처 및 트래킹 장비, 얼굴/신체 데이터 수집 환경, 기존 리깅 데이터와의 실시간 리타게팅 및 렌더링 연동, 안정적인 네트워크와 영상 송출 시스템, 장비 캘리브레이션 및 유지보수 환경 등이 필요하다.
따라서 멤버 개개인의 자택에 각각 독립적인 시스템을 구축했다기보다는, 블래스트가 관리하는 별도 공간에 공용 또는 개인별 운용이 가능한 라이브용 경량 트래킹 및 송출 환경을 구축했을 가능성이 높다.
구현 방식으로는 ARKit 기반 페이스 트래킹, 웹캠 또는 별도 센서를 활용한 상반/핸드 트래킹, 필요에 따른 장갑형 모션 센서 등의 조합을 생각해 볼 수 있다.݁˖Ი𐑼⋆


ㅁㅁ
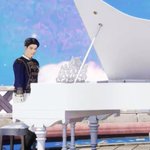
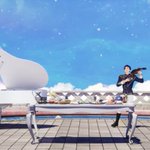
플레이브 보이는 위버스 라이브 방송(사전 테스트)에서 추가 확인된 것들
액세서리 상태 전환
헤어 및 의상 에셋 적용
멤버 3D 캐릭터 외형의 실시간 변경
변경된 외형과 기존 리깅 데이터의 호환성
별도로, 화면에 노출되지 않는 하체 영역까지 모션 데이터가 수집/반영되는지는 추가적인 확인이 필요하다.


플레이브 위버스 보이는 개인 라이브
예상 시나리오 TOP 3(공개된 사전 공지 기반)
ㅡ
1. 클라우드 또는 원격 스트리밍 파이프라인
원격 환경에서 모션 데이터 수집 및 전송
클라우드 렌더링 또는 원격 렌더링 연동
실시간 영상&음성 스트리밍 최적화
2. 경량화된 페이스&상반신 트래킹 + AI 모션 보간
ARKit 또는 전용 웹캠 기반 경량 트래킹
상반신 중심의 모션 데이터 추출
관절 및 동작 데이터 보정과 모션 보간
원격 환경에서도 자연스러운 아바타 표현
3. 원클릭 자동화 오퍼레이팅
방송 세션 초기화 및 캐릭터 로딩
트래킹/렌더링/송출 파이프라인 자동 연결
방송 상태 모니터링 및 오류 대응 자동화
ㅡ
일반적인 상용 솔루션을 적용하는 데 그치지 않고, 블래스트는 아티스트의 활동 반경과 소통 방식을 확장하기 위해 R&D 단계에서부터 엔진 기반의 자체 기술 개발과 송출 파이프라인 커스터마이징을 진행하고 있다.
쟘깐 기다리면 곧 홀로그램도 오겠지?👶
@plave_official
#PLAVE #플레이브 #プレイブ #블래스트 #언리얼엔진
