

open to technical writing internships/gigs ~ making contributions @chonkieai. interested in vector search and SLMs.
Joined February 2024
- Tweets380
- Following374
- Followers397
- Likes4.9K





Pinned Tweet
hey everyone!
i'm looking for a technical writing internship.
here's my portfolio 👇
chimchim89.github.io/portfol…


achal retweeted

i really really look up to anthropic’s comms.
but i never really dug into their paid ads
so since the launch is here. i used @treg_a 's new marketing skill to pull every us ad they’ve run since september
here’s what’s actually going on
- 239 meta ads since sep 1.
- 132 of them went live on a single day, nov 19. that’s ipo day. 0 of them mention the ipo.
- google ad spend went from ~$8.5k/month (oct 2025) to ~$1M/month (oct 2026). ~119x in a year (estimated)
- google is where the money goes. ~$2.7M on search vs ~$0.3M on meta since september (estimated)
- 29 paid creators running 90 ad versions. almost none are tech creators. it’s moving to new york, job hunting, morning routines, side businesses
- every creator video gets ~3 cuts, so meta picks the winner
- 69 ads are just two customer stories, stripe and palo alto networks. they went live 3 weeks before the consumer push
the playbook as i read it
> devs already talk about claude for free, so paid money goes to everyone else
> enterprise proof first, consumer volume after
> ride your biggest news day with product, not news
kinda crazy that whole teardown cost me just 7 cents
🤝 Paid partnership


Introducing /REA-marketing skill
Reverse-engineer any brand's marketing, layer by layer
Try it at treg.to/rea-marketing
- Every ad, creator collab and offer, week by week
- How each tactic contribute to Reach, spend, sales
- REA playbook from Nike, DJI, Replit or your competitors...
Prep your black-friday campaign with this
Git Repo below 👇
sometimes you just need to see someone do it before you believe you can too. be that someone.
1
2
99
looking for research ideas?
the limitations and future work sections of a research paper are worth reading. they tell you what the work doesn't cover and what the authors left open.
3
86
achal retweeted
feels surreal to witness this shifting happening right in front of you.
i was watching these things from the sidelines till last month.
to be present there and having the chance to document it all is a very strange feeling but I'm all in for it
here's the complete event documented: nitter.cf/escvelocityprod/status…


came across two new terms while reading the sentence-bert paper
> siamese network
> triplet network
here's what they mean

1
2
114
> siamese network
one network used twice, with shared weights. sentence a goes through it to get a vector u, and sentence b goes through the same network to get a vector v.
the shared weights mean we're using the same encoding function for both sentences. the model is trained to make these embeddings useful for comparison.
how it learns depends on the task. for classification, it uses both embeddings to predict a label, like whether one sentence contradicts the other. for regression, it learns to make their cosine similarity match a given similarity score.
the useful part: each sentence can be encoded separately, and its vector reused instead of running the model again for every pair.
in the paper's comparison, finding the most similar pair among 10,000 sentences took about 65 hours with bert, versus about 5 seconds with sbert. bert needed roughly 50 million pairwise computations.
1
1
36
> triplet network
same shared-weight idea, but with three sentences:
anchor: "a man is playing a guitar"
positive: "someone is strumming a guitar"
negative: "a woman is cooking pasta"
the goal is to bring the anchor closer to the positive than to the negative, with a minimum gap called a margin.
once that gap is big enough, the loss for that triplet is zero. if it isn't, that triplet still adds to the training loss.
both setups are used in sbert to learn sentence embeddings we can compare by meaning, without running bert on every sentence pair.
20
it's been a while since i read a research paper in information retrieval.
started reading one today.
and idk why i suddenly stopped contributing to oss a few months ago. i used to be so happy doing it... it was like my daily dose of dopamine.
need to get back to that too.

4
98
achal retweeted
dm me if you are hiring for content lead

i've been poking around inside ModernBERT with one sentence, "Tom is a good person, Mary thinks he is not."
the model gets that the "not" is Mary's opinion. but it still ends up thinking worse of Tom, almost as much as Mary does (77%).
wrote it all up.
please give it a read.
chimchim89.github.io/Does-an…

Read this sentence.
"Tom is a good person, Mary thinks he is not."
You probably understood three things without even trying. "He" is Tom. Tom is a good person. And the "not" is only what Mary thinks. The sentence never says Mary is right. It just tells you she disagrees.
So I ran it through ModernBERT and looked inside to see if it understands the same three things.
It gets the first one right every time. The other two get tangled up.
The video shows what happens inside the model, and the full article is right below.


achal retweeted
i have been job hunting for a week using all platforms
and it’s been a mess. none of the job platforms are getting me replies
the only calls and interviews i’ve gotten have come from twitter cold dms or cold mails
but it’s been getting harder to figure out who to cold mail, and then actually finding their emails
pretty sure @treg_ai is gonna be super handy for the rest of this job hunt
ps: last search costed me just 4 cents (screenshot as proof)
🤝 Paid partnership

Introducing Jev @typesafeai powered jobs-api
Try it at treg.to/jobs-api
- One API to any jobs data
- $0.03 to run a full job hunt
- Real salary & Hiring manager data
- Plugin to any agent for your dream job
Fully open source, 0% markup
Git Repo below 👇
if the gift of art is in your hands, it's not random.
paint. write. sketch. create. even if the world doesn't clap, your soul will.
4
262


achal retweeted
I’m looking for a founder’s office role at a Deeptech or AI company. Here’s my story.
A year ago I joined Quarq Labs as a technical writing intern. Two months later I was running growth.
No hand-holding. I wrote the technical posts, planned content, handled presence on socials, worked with our designer on every visual, ran ads, and bugged engineers for exactly 15 minutes at a time so I didn’t eat their week.
Some of it worked:
> our open-source launch hit 145K views and got shared by LangChain’s co-founder
> six articles drew 256K views
> the account went from 100 to 1,000 followers in 6 weeks
> got attention from researchers and engineers in ai and robotics
Some of it didn’t. Our paid ads converted badly. I learned more from that than from the wins.
Since then I’ve written about robotics and simulation for an NVIDIA Inception startup and a @spc backed startup, started a podcast just to talk to Indian deeptech founders, and done outreach for a robotics tooling company.
The common thing is I’m obsessed with hard technology. Robots, simulation, Technicals behind ML architectures, the stuff that’s difficult to explain. I want to spend my career making it make sense to buyers, engineers and investors.
I’m learning to be a generalist. Content, launches, ops, some GTM and research that founders needs help with. I pick up whatever’s on the floor.
If you’re building something hard and want someone like that in your founder’s office, I’d love to talk.
Based in Bangalore or US (Remote). DMs open. Resume below
(pic unrelated. it weirdly helps with reach sometimes when theres a personal story involved)

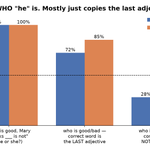
been poking around inside bert and modernbert with sentences like this- "tom is a good person, mary thinks he is not"
both got who "he" refers to right every time in my tests. but when i asked who's actually good, they mostly just went with whichever adjective came last.
also found one neuron (#251) in modernbert taking up 97% of the activity i was measuring in the later layers. it quietly broke my measurements for a while.


1
5
207