




Pinned Tweet
Super excited that INCLUDE-2.0 is an oral presentation at #EMNLP2026! 🎉
@mariagrandury will present our work tomorrow at 11:00 am (CET), as unfortunately I couldn't make it in person.
Check out her talk and chat about the paper or future INCLUDE collaborations! 🌍

Super excited to present INCLUDE-2.0 at #EMNLP2026 🎉
Join me tomorrow at 12:15 in room G13 for our oral presentation in the Resources and Evaluation session!
Come to chat about the paper or collaborate in future INCLUDE versions!
Angelika Romanou retweeted

Looking forward to speaking at the BLISS AI Speaker Series next Tuesday! 🧠
I’ll talk about our recent projects at the intersection of AI and neuroscience. If you’re in Berlin, come say hi!
🗓️ Tue, Nov 3, 7pm
📍 TU Berlin, Room C130
🎟️ Free: lnkd.in/dyPshYJB

Gouthami Vadithya, Guido Ivetta, Hitesh Laxmichand Patel, Javier Conde, Jorge Vallego, Juan J. Calderón G., Karan Gupta, Marcos J. Gomez, Marvin M. Agüero-Torales, Mithil Bangera, Naira Paola Arnez Jordan
Interested in collaborating with us on future versions of INCLUDE? 🌍
Help us expand the benchmark's coverage of languages, countries and regional knowledge by filling out this form: forms.gle/FSeHV9AZsguE79Sm7

🤗 Dataset: huggingface.co/datasets/epfl…
🧪 Evaluation: supported in lm-evaluation-harness
📄 Paper: aclanthology.org/2026.emnlp-…

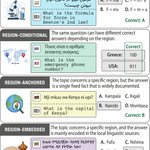
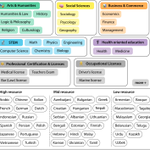
We're excited to release INCLUDE-2.0! 🌍 An expanded multilingual benchmark evaluating models' regional factual knowledge using questions from local exams across 91 languages, 22 scripts and 86 countries.
Special thanks to the main contributors of this work
@mariagrandury @clara__meister @negarforoutan @jabez_magomere Anna Sotnikova @SciOrestis @computermacgyve @Shmuhammadd @ABosselut
And to all our data contributors, without whom this project would not have been possible! 💙
Angelika Romanou retweeted

Looking forward to discuss about our paper in poster session A in Hall H at 11:00am! #emnlp2026

1/🚨 New paper #emnlp2026
Do multilingual #LLMs work in English? It depends on how you ask. In "Lingua Franca or Probing Artifact?", we probe the same hidden states with three latent language identification methods and get different answers. 🧵👇
#interpretability #NLProc

Angelika Romanou retweeted
1/🚨 New paper #emnlp2026
Do multilingual #LLMs work in English? It depends on how you ask. In "Lingua Franca or Probing Artifact?", we probe the same hidden states with three latent language identification methods and get different answers. 🧵👇
#interpretability #NLProc
Angelika Romanou retweeted

After escaping European heat with 30+ hrs delay and missing luggage I am finally in San Diego attending @aclmeeting! 🇺🇸🌴#ACL2026
I will be presenting our work on the multilingual benchmark translation from @INSAITinstitute 🇺🇦🇧🇬
📍Poster Session E, July 6th 11.00-12.30
Also check out @apertusllm poster, presented by the greatest @agromanou, to know more about the biggest fully open multilingual models 🇨🇭
📍Poster Session F, July 7th 9.00-10.30

Angelika Romanou retweeted

New research from our MLO Lab @EPFL: Improving Neural Network Training by Decoupling the Magnitude and Direction of Weight Vectors.
Magnitude-Direction Decoupling (MD): a simple optimizer tweak, and what we (currently) think is the right way to train efficiently at scale. 🧵

Angelika Romanou retweeted
🧠 When you watch a movie, your brain blends sight, sound, and speech into a single experience.
Should models of the brain blend them too, or keep the senses separate until the very end?
We built MIRAGE to find out. Sets a new SOTA for predicting whole-brain fMRI from movies 🧵

Our paper, PERK, is at #ICLR2026 today! 🎉
I couldn’t make it, but @eric_zemingchen will present our work and share all the details on long-context reasoning and how TTL improves it!

Our paper PERK is accepted to #ICLR2026 🎉
Long-context reasoning is one of the most critical skills a frontier model must master. The standard approach: feed the context into the model’s attention and hope the model figures out how to reason over its content.
We show that Test-Time Learning (TTL) is a more effective way to process long context than standard long-range attention.
Instead of just reading the context, the model should learn it at test time, by internalizing it into LoRAs via next-token prediction.
Come find us at our poster — Pavilion 3 #509, Thu, Apr 23 • 10:30 AM – 1:00 PM — if you want to dig in further.

Angelika Romanou retweeted

So excited to share that our paper “Hire your Anthropologist: Rethinking Cultural Benchmarks through an Anthropological Lens”, found here: arxiv.org/abs/2510.05931has been accepted for publication at #EACL2026.