

Research Scientist at Waymo working on improving autonomous behavior. Prev: Ph.D @UCBerkeley, UG @RiceUniversity | he/him
CLE ➡️HTX ➡️Cal➡️SF
Joined April 2012
- Tweets159
- Following252
- Followers479
- Likes3.2K




Ameesh Shah retweeted

How can robot policies be trained to best leverage VLMs' CoT reasoning and in-context learning for generalization?
The key is Steerable Policies: vision-language-action models that can be flexibly controlled in many ways!
steerable-policies.github.io
1/9

Ameesh Shah retweeted

Flow policies are getting popular in robotics as they capture multimodal prior data well, and synergize nicely with action chunking. But it is unclear how to best train them with RL effectively.
We found something that works pretty well! (spoiler: use Adjoint Matching) 🧵1/N

🗣️📣Announcing VerifAI 2: AI Verification in the Wild, an upcoming workshop at #ICLR2026!! 🗣️📣
VerifAI will gather researchers to explore topics at the intersection of genAI and trustworthy ML. Submit your work!
Check out our website and CFP for more: verifai-workshop.github.io/

Ameesh Shah retweeted
Action chunking is drawing growing interest in RL, yet its theoretical properties are still understudied.
We are excited to share some insights on when we should use action chunking in Q-learning + a new algo (DQC) to tackle hard long-horizon tasks!colinqiyangli.github.io/dqc🧵1/N

Ameesh Shah retweeted

I’m at #NeurIPS2025 until Sunday!
Reach out to chat about multi-agent learning, AI safety, human-AI interaction, or LM agents.
Excited to present our work on rational policy gradient in hall C,D,E, #5511, 11-2pm on Wed with @MichaelD1729 @MicahCarroll @ameeshsh


Had a lot of fun working on this project with @NiklasLauffer et. al. 🤠 We're able to improve multi-agent policies by having agents play with *meaningfully challenging* partners! But finding those partners is not an easy task - check out the thread for more!
Ameesh Shah retweeted
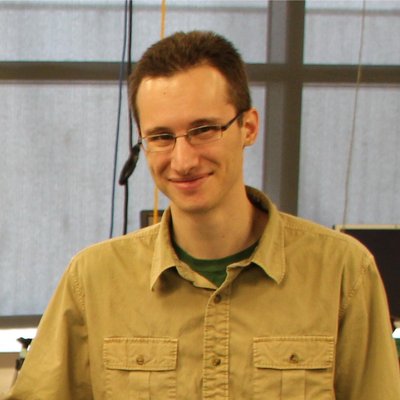
Now we can have self-refinement for VLAs in the real world (with the aid of a big VLM)! VLM critiques VLA rollouts and iteratively refines the commands to make it perform better.

LLMs have shown a remarkable ability to “self-refine” and learn from their mistakes via in-context learning. But in robotics, most methods are single-shot. How can we bring inference-time adaptation to robot learning? A 🧵:
As a result, LITEN’s VLM planner can iteratively learn both the VLA’s capabilities and relevant information about real-world dynamics to solve complex, long-horizon tasks.
This was a really fun project to work on with great collaborators: @verityw_ , @adwait_godbole, Sanjit, and @svlevine. I'm excited to see more inference-time techniques develop for robot learning!
arXiv: arxiv.org/abs/2510.19752
website: liten-vla.github.io

Ameesh Shah retweeted
Everyone knows action chunking is great for imitation learning. It turns out that we can extend its success to RL to better leverage prior data for improved exploration and online sample efficiency! colinqiyangli.github.io/qc/
The recipe to achieve this is incredibly simple. 🧵 1/N
The submission deadline to our workshop has been extended until Feb. 7!!!! Submit your papers on trustworthiness + verification + genAI + ML and come hang with us in Singapore!

📣Announcing VerifAI: AI Verification in the Wild, a workshop at #ICLR2025
VerifAI will gather researchers to explore topics at the intersection of genAI/trustworthyML and verification: verifai-workshop.github.io/
@celine_ylee @theo_olausson @ameeshsh @wellecks @taoyds

Ameesh Shah retweeted

The ultimate test of any physics simulator is its ability to deliver real-world results.
With MuJoCo Playground, we’ve combined the very best: MuJoCo’s rich and thriving ecosystem, massively parallel GPU-accelerated simulation, and real-world results across a diverse range of robot platforms: quadrupeds, humanoids, dexterous hands, and arms.
Best of all? You can get started today with a single command: pip install playground
playground.mujoco.org/
Ameesh Shah retweeted

📣Announcing VerifAI: AI Verification in the Wild, a workshop at #ICLR2025
VerifAI will gather researchers to explore topics at the intersection of genAI/trustworthyML and verification: verifai-workshop.github.io/
@celine_ylee @theo_olausson @ameeshsh @wellecks @taoyds
Ameesh Shah retweeted

📢📢 Thrilled to share our new work: Syzygy: Dual Code-Test C to Rust Translation using LLMs and Dynamic Analysis!
Key Principles
1️⃣ 🤖🤝🔍 Combining LLM Inference Scaling with Dynamic Analysis:
* Best of both worlds (program semantics and neural search)
2️⃣ ⚡️🧪 Dual Code-Test Translation:
* Don't just convert the code; translate tests for incremental validation
Results: We successfully translated Zopfli, a C compression library with ~3000 LoC to Safe Rust with test-based validation 🤯
1/
