

Official twitter handle of Apache Hudi, an open data lakehouse platform. https://nitter.cf/t.co/SXay7oHNah
Joined January 2019
- Tweets1.1K
- Following124
- Followers4K
- Likes317





Apache Hudi retweeted
At scale, table metadata explodes, as Google's VLDB paper "Big Metadata" shows.
Hudi's metadata table treats it like big data 📊: self-managed, indexed
Key bits:
- Partition/file listings 📁
- Column stats 📈
- Record indexes 🔍
This ensures efficient reads/writes as things grow 🚀.

Apache Hudi retweeted

2/
Apache Hudi continues to operate at trillion-record scale inside one of the most demanding data platforms in the industry.
Not experiments. Not edge cases. Production systems moving hundreds of petabytes.
At Uber, Hudi is powering:
• high-volume ingestion
• continuous updates & merges
• replication
• incremental processing

Apache Hudi retweeted

[BLOG] Just published a blog on a problem that trips up many teams: retry storms from concurrent writers on data lakehouses
Streaming ingestion + long-running maintenance jobs = OCC fails you. Long jobs lose every commit race and retry indefinitely
@apachehudi NBCC solves this by eliminating conflicts by design—writers append in parallel, completion time determines order. No retries needed.
Deep dive 👇
hudi.apache.org/blog/2025/12…
#ApacheHudi #DataLakehouse #DataEngineering

Apache Hudi retweeted
The pace of innovation in the @apachehudi ecosystem is accelerating fast. If you want to keep up with these architectural shifts and production lessons, the monthly newsletter is the best way to stay plugged in.
🗞️ Read + subscribe:
hudinewsletter.substack.com/…


Apache Hudi retweeted
New release: @apachehudi 1.1 is out!
The standout innovation: Pluggable Table Format Framework decouples Hudi’s storage engine from the format, unlocking full read compatibility with Iceberg and Delta Lake.
It’s a massive unlock: Hudi’s ingestion performance with total format interoperability. Read my full write-up here: hudi.apache.org/blog/2025/11…
#ApacheHudi #DataLakehouse

Apache Hudi retweeted
🎉 Apache Hudi 1.1 has landed—and it's a banger! 🚀
This release is packed with innovations that will transform how you build data lakehouses:
🎯 Pluggable Table Format Framework for multi-format support (Hudi, Iceberg, Delta Lake)
⚡ 15x faster clustering with Parquet binary copy—yes, you read that right!
⚡ 2-3x higher throughput for Flink writers!
🚀 Spark 4.0 & Flink 2.0 support —harness the latest engine capabilities
Read the blog: hudi.apache.org/blog/2025/11…
#ApacheHudi #ApacheSpark #ApacheFlink

Apache Hudi retweeted
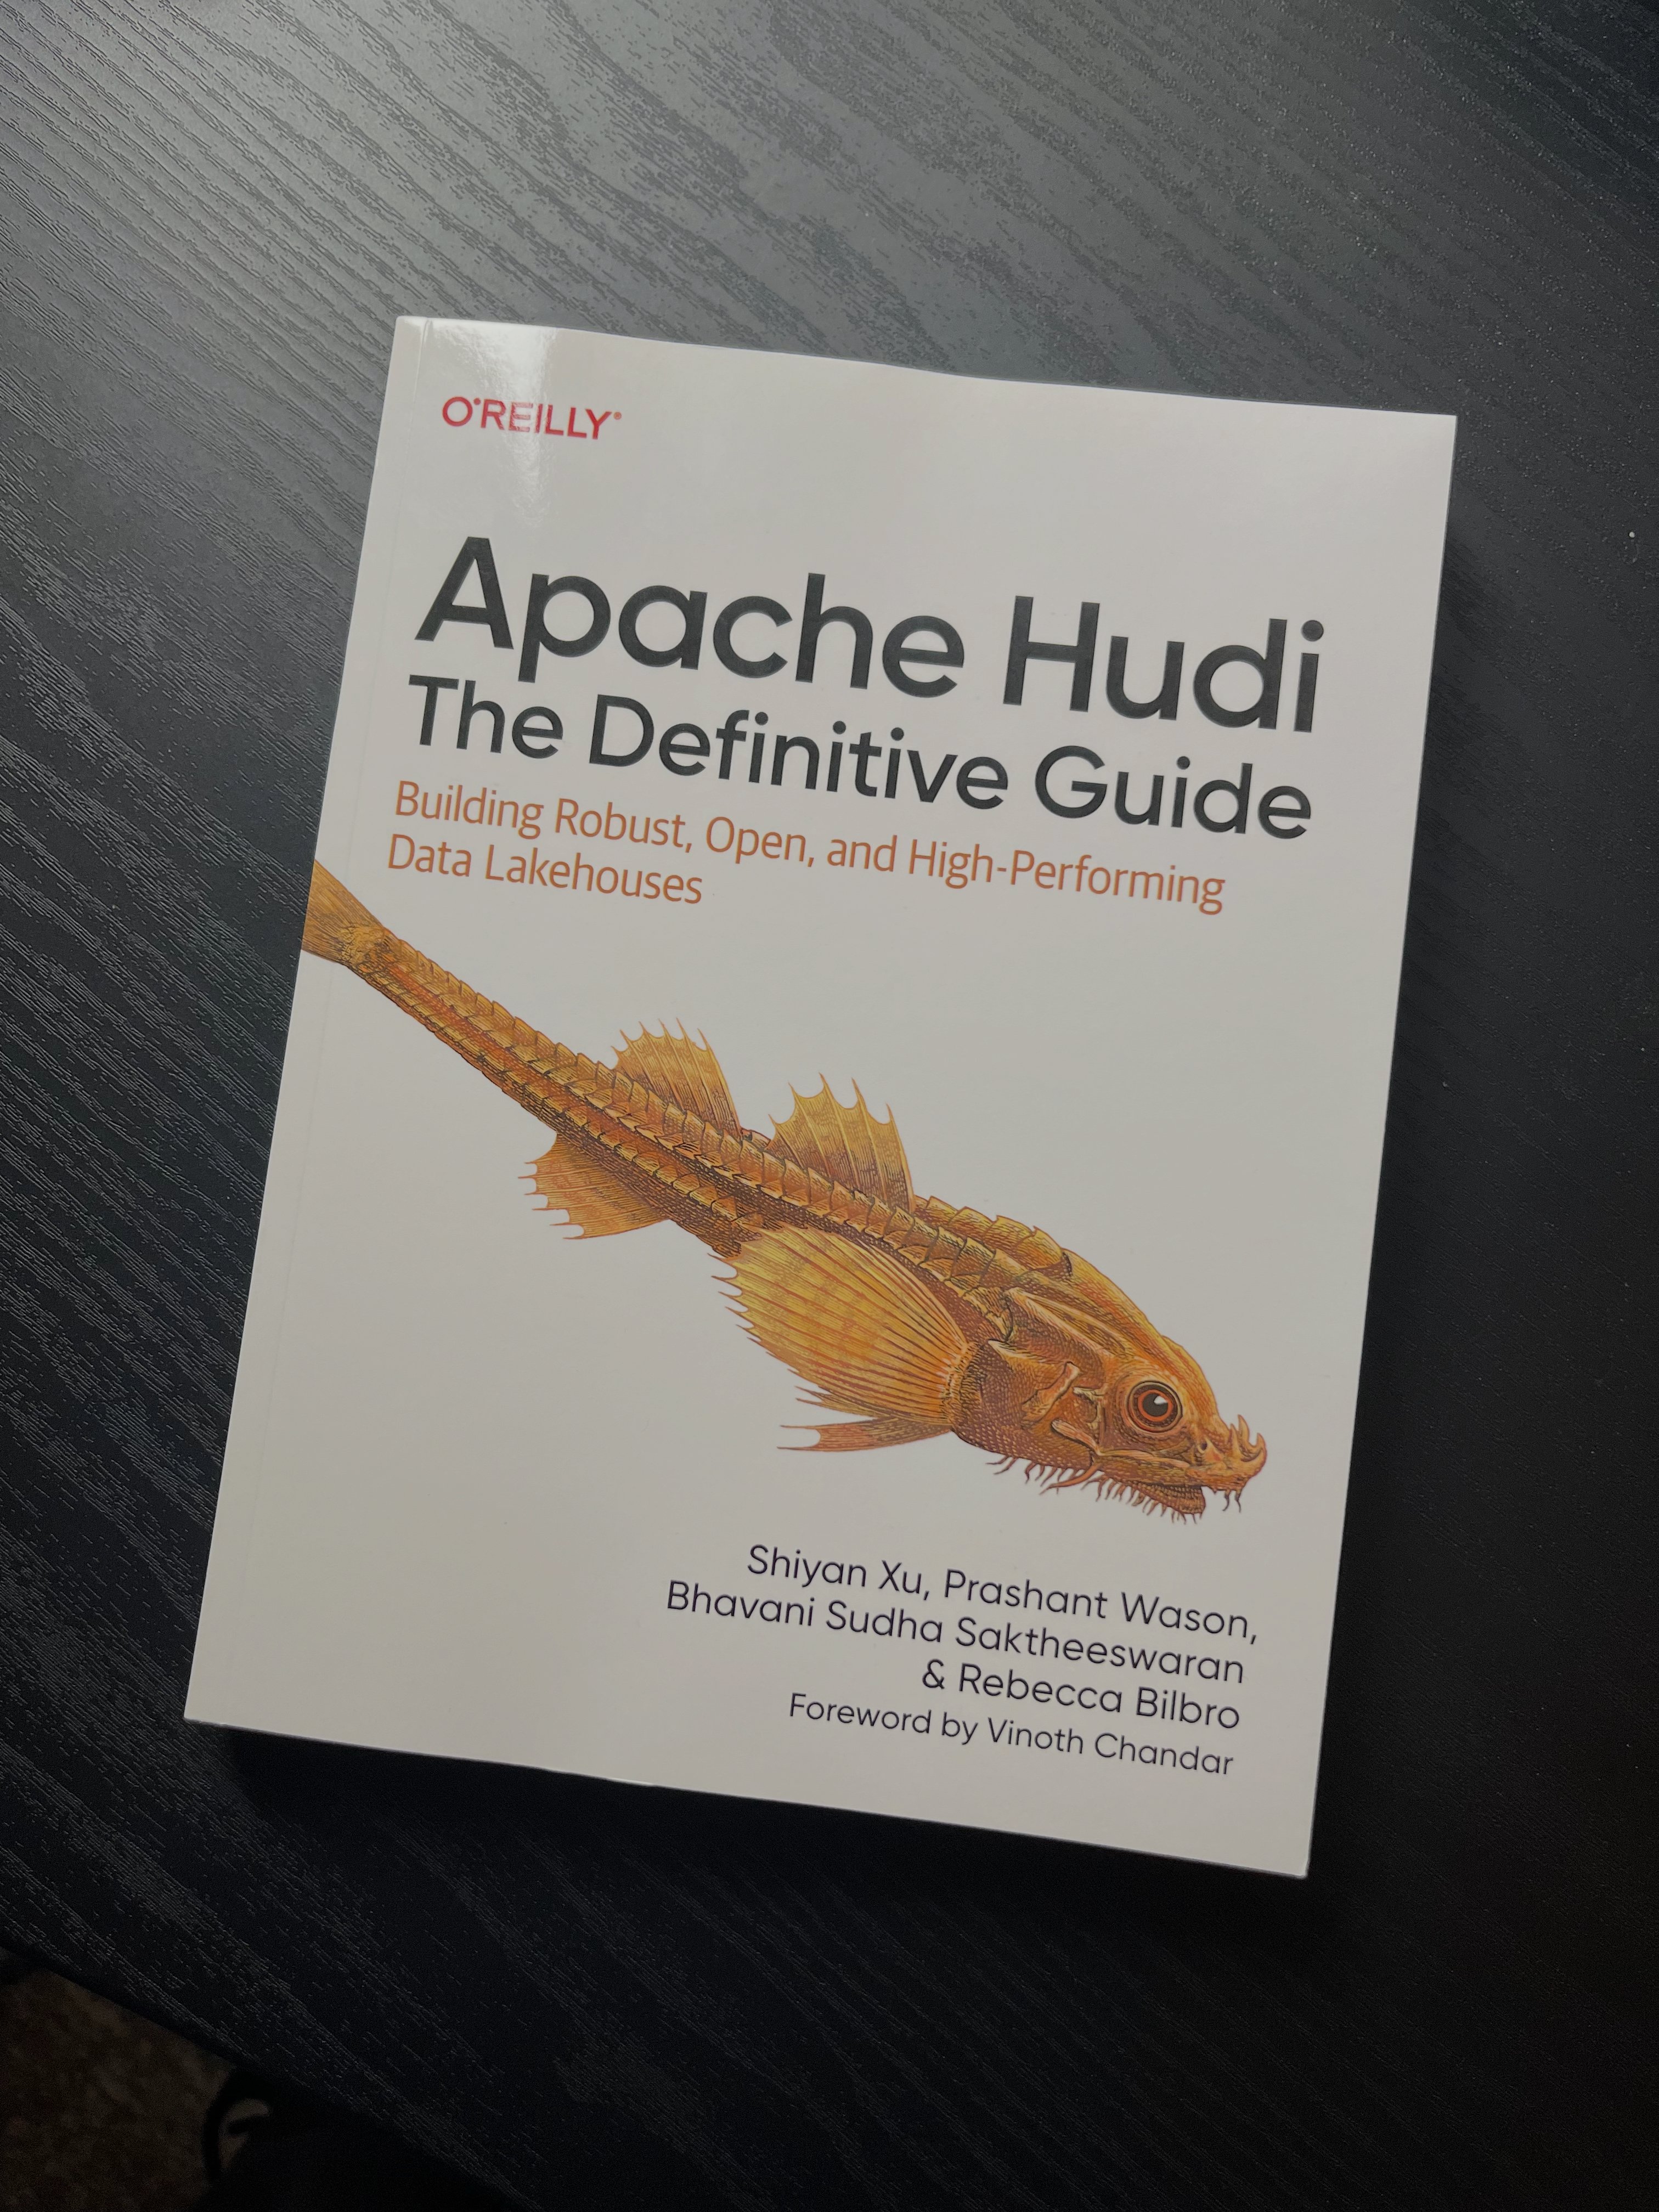
📚 The Definitive Guide of @apachehudi has arrived!
This was a collaborative effort with my co-authors Prashant, @SudhaSakthee , and @RebeccaBilbro , bringing together years of collective knowledge from the Apache Hudi community — from fundamental concepts to production patterns for building data lakehouses.
Grateful to @byte_array for writing the foreword, and to all the tech reviewers, editors, and those who provided praise and support for the book.
Thanks to @OReillyMedia and @Onehousehq for making this happen, and to everyone in the Hudi community who's shaped this technology.
For anyone building data lakehouses or exploring Hudi, hope this guide proves useful. 🚀
#ApacheHudi #DataEngineering #DataLakehouse

Apache Hudi retweeted
Speaking at Open Source Data Summit (Nov 13) on building streaming-first lakehouses with @apachehudi 🎤
We'll dive into:
• Merge-on-Read tables
• NBCC for conflict-free writes
• LSM Timeline
• Solving the small file problem
Register: opensourcedatasummit.com/
#OSDS2025 #ApacheHudi #DataLakehouse

Apache Hudi retweeted
💡✨ [New Blog] Part 1 of a two‑part deep dive on how Hudi brings multimodal indexing to the lakehouse.
🔗 Read: hudi.apache.org/blog/2025/10…
@apachehudi brings indexing to the data lakehouse with a self‑managed metadata table — a multimodal index that tracks partition and file lists, column stats, and partition stats, using HFile for fast key lookups.
How data skipping works:
🔎 Parse predicates from your SQL
✂️ Prune partitions with partition‑level stats
✂️ Prune files with file‑level stats
📉 Scan only the minimum required data
Why it matters: 📉 less I/O, ⚡ faster queries, 💵 lower compute — at scale.
Pro tip ⚙️: index only the columns you frequently filter on using 𝗵𝗼𝗼𝗱𝗶𝗲.𝗺𝗲𝘁𝗮𝗱𝗮𝘁𝗮.𝗶𝗻𝗱𝗲𝘅.𝗰𝗼𝗹𝘂𝗺𝗻.𝘀𝘁𝗮𝘁𝘀.𝗰𝗼𝗹𝘂𝗺𝗻.𝗹𝗶𝘀𝘁 to control metadata overhead.
#ApacheHudi #DataLakehouse #DataEngineering

Apache Hudi retweeted
[Blog] 𝐊𝐚𝐟𝐤𝐚 𝐂𝐨𝐧𝐧𝐞𝐜𝐭 𝐯𝐬. 𝐅𝐥𝐢𝐧𝐤 𝐯𝐬. 𝐒𝐩𝐚𝐫𝐤 for data ingestion. Which should you choose?
✦ 𝐀𝐩𝐚𝐜𝐡𝐞 𝐊𝐚𝐟𝐤𝐚 𝐂𝐨𝐧𝐧𝐞𝐜𝐭: The reliable data mover 🚚 As a component of Kafka, Connect is a framework for reliably streaming data between Kafka and other data systems. It uses a distributed and scalable architecture with source connectors to ingest data into Kafka and sink connectors to move data out to destinations like data lakehouse.
✦ 𝐀𝐩𝐚𝐜𝐡𝐞 𝐅𝐥𝐢𝐧𝐤: The real-time specialist ⚡ Flink is a true stream-processing engine that excels at low-latency, event-driven pipelines. A key feature is Flink CDC, which can ingest Change Data Capture (CDC) events directly from databases without needing Kafka. I recommend Flink when you need to filter, enrich, or run complex aggregations in-stream before loading.
✦ 𝐀𝐩𝐚𝐜𝐡𝐞 𝐒𝐩𝐚𝐫𝐤: The batch powerhouse 🏭 Spark is the go-to for large-scale batch processing and complex transformations. While it supports streaming, its micro-batch model means slightly higher latency. It's the ideal choice for heavy-duty batch backfills, ML data prep, and workloads where transformation complexity is more important than ultra-low latency.
In short, my recommendation is:
Just need to move data reliably? ➡️ Kafka Connect
Need true stream processing with low latency? ➡️ Flink
Need to process large batches or run complex transformations? ➡️ Spark
@apachehudi supports all three of these engines for writes. The right tool really depends on your specific needs for latency, processing, and scalability.
Read the full blog here: onehouse.ai/blog/kafka-conne…
#ApacheKafka #ApacheFlink #ApacheSpark #ApacheHudi #DataLakehouse

Apache Hudi retweeted
[Blog] Struggling with Apache Iceberg performance when your data dimensions get too hot? 🔥🌡️
Frequent updates and deletes in Iceberg can lead to a "chilly meltdown," forcing a tough choice between fast writes and efficient reads. 🥶 But what if you didn't have to compromise? 🤔
In this recent blog, I explored how you can get the best of both worlds by combining the power of @apachehudi with @apachextable to serve fast, native Iceberg tables.
Read the full post to learn how to get fast writes and reads with Iceberg:
👉 onehouse.ai/blog/how-to-save…
#ApacheIceberg #ApacheHudi #ApacheXTable #DataLakehouse

Apache Hudi retweeted
Had a fantastic time speaking at the Data Streaming Summit SF 2025 this Tuesday! 🎤 It was a great pleasure to share my perspective on the architectural challenges of streaming writes in the data lakehouse.
I really enjoyed diving into how @apachehudi streaming-first designs for building streaming lakehouses. For those who couldn't make it, here’s a quick recap of the key challenges and how Hudi handles them: 💡
⚡️ High-frequency updates: use 𝐌𝐞𝐫𝐠𝐞-𝐨𝐧-𝐑𝐞𝐚𝐝 (𝐌𝐎𝐑) tables to absorb changes.
📈 Large volumes of mutable workloads: use 𝐫𝐞𝐜𝐨𝐫𝐝-𝐥𝐞𝐯𝐞𝐥 𝐢𝐧𝐝𝐞𝐱𝐢𝐧𝐠 to find records fast and keep write latency low.
🗂️ Small File issues: use 𝐚𝐮𝐭𝐨-𝐟𝐢𝐥𝐞 𝐬𝐢𝐳𝐢𝐧𝐠 and 𝐚𝐬𝐲𝐧𝐜 𝐜𝐨𝐦𝐩𝐚𝐜𝐭𝐢𝐨𝐧/𝐜𝐥𝐮𝐬𝐭𝐞𝐫𝐢𝐧𝐠.
⚔️ Conflicts and retries with OCC: Hudi 1.0 introduced 𝐍𝐨𝐧-𝐁𝐥𝐨𝐜𝐤𝐢𝐧𝐠 𝐂𝐨𝐧𝐜𝐮𝐫𝐫𝐞𝐧𝐜𝐲 𝐂𝐨𝐧𝐭𝐫𝐨𝐥 (𝐍𝐁𝐂𝐂) to avoid costly retries.
📜 Long commit history: Hudi 1.0 𝐋𝐒𝐌 𝐓𝐢𝐦𝐞𝐥𝐢𝐧𝐞 for optimized access and storage.
Thanks again to the Data Streaming Summit by @streamnativeio for having me!
#DataLakeHouse #DataStreaming #ApacheHudi #DSSSF25


Apache Hudi retweeted
🗞️ OLD NEWS: but worth a shout-out. Keys are optional in Hudi ...
One of Hudi’s core goals was to remove friction from building data lakes. That’s why — for a long time now — Hudi has quietly supported auto-generation of record keys. No need to think up a key field just to get started.
Old news, but worth reiterating. Shiyan Xu has a great blog walking through the considerations:
👉 hudi.apache.org/blog/2025/09…
Why does this matter?
•Keys are what enable Hudi’s unique features: indexing, seamless CDC, async & bounded compaction, log compaction… all without extra work from you.
•They come at almost zero storage cost — even more compressible than popular UUID formats.
•They lower the barrier to adoption for append-only workloads while keeping all of Hudi’s advanced table services intact.
Enjoy your table...

Apache Hudi retweeted

New work on Generic Table APIs from Snowflake and Onehouse in Polaris uses XTable for non-iceberg tables. Running XTable via REST API =
POST
/v1/conversion/table/
{"source-format": "HUDI | DELTA"
...}
Decoupling catalog spec from formats future proofs innovations in storage

Apache Hudi retweeted
I'm delighted to be delivering this talk at Data Streaming Summit SF 2025 hosted by @streamnativeio. Some highlights of the talk are:
✅ Understand the architecture and workflow of NBCC and its alignment with Flink for streaming ingestion.
✅ Learn how the new file layout, LSM-tree backed event logs, and TrueTime semantics eliminate ingestion bottlenecks.
✅ Gain actionable insights into using NBCC for concurrent, conflict-free ingestion with tunable consistency.
Check out more about the event: datastreaming-summit.org/eve…
#ApacheFlink #ApacheHudi #DataStreamingSummit

Apache Hudi retweeted
✍️ [Blog] Part 2 of building a RAG-based AI recommender 🤖
A reliable, efficient data lakehouse isn't just a prerequisite—it's the core component that enables RAG (Retrieval-Augmented Generation) applications to thrive. While the LLM usually gets the spotlight, the data pipeline does the heavy lifting.
Part 1 of the blog introduced RAG from a conceptual perspective and explore why solid data architecture is crucial for AI success.
In part 2, we go through each of the five main components in the demo app, and discuss the key code snippets. A complete working project is also shared.
👉 blog.datumagic.ai/p/building…
The demo app uses @FastAPI for building the main server app, @apachehudi as the primary data source for incremental processing, @qdrant_engine for storing vectorized data for building context, and an @OpenAI model for generating responses.
#datalakehouse #ai #rag

Apache Hudi retweeted
🎉 A new chapter "Running Hudi in Production" is now available in the early release of "Apache Hudi™: The Definitive Guide" - the first book ever written about @apachehudi, by industry experts: @_xushiyan, Prashant Wason, @SudhaSakthee, and @RebeccaBilbro.
👉 Get a free copy of the e-book: onehouse.ai/whitepaper/apach…
In this new chapter, you'll learn about
✅ Operational utilities provided by Hudi
✅ Hudi's platform integration features
✅ Tips on performance tuning
Apache Hudi transforms your data lake into a powerful lakehouse with database-like capabilities - efficient upserts, deletions, and incremental processing without the complexity you'd expect.
What's your biggest data lake challenge today? Drop a comment below - we'd love to hear your experiences!
#ApacheHudi #DataLake #DataEngineering

Apache Hudi retweeted
💡 𝗛𝗼𝘄 𝗱𝗼𝗲𝘀 𝗱𝗮𝘁𝗮-𝘀𝗸𝗶𝗽𝗽𝗶𝗻𝗴 𝘄𝗼𝗿𝗸 𝗶𝗻 @apachehudi ?
The metadata table (a multi-modal index system) located within your Hudi table contains multiple index components such as 𝗙𝗶𝗹𝗲𝘀, 𝗣𝗮𝗿𝘁𝗶𝘁𝗶𝗼𝗻 𝗦𝘁𝗮𝘁𝘀, 𝗖𝗼𝗹𝘂𝗺𝗻 𝗦𝘁𝗮𝘁𝘀.
✦ 𝗙𝗶𝗹𝗲𝘀: tells you what partitions are there, and what files are under each partitions
✦ 𝗣𝗮𝗿𝘁𝗶𝘁𝗶𝗼𝗻 𝗦𝘁𝗮𝘁𝘀: tells you, for each partition, what are the min/max values for column A, B, C, ...
✦ 𝗖𝗼𝗹𝘂𝗺𝗻 𝗦𝘁𝗮𝘁𝘀: tells you, for each data file, what are the min/max values for column A, B, C, ...
These indexes work jointly to reduce the files needed to be scanned by query engines:
1️⃣ Query engine parses a SQL and extract the predicates from the WHERE clause
2️⃣ Ask 𝗙𝗶𝗹𝗲𝘀 for a list of partitions, then prune it based on 𝗣𝗮𝗿𝘁𝗶𝘁𝗶𝗼𝗻 𝗦𝘁𝗮𝘁𝘀
3️⃣ For the pruned partition list, ask 𝗙𝗶𝗹𝗲𝘀 for a list of data files, then prune it based on 𝗖𝗼𝗹𝘂𝗺𝗻 𝗦𝘁𝗮𝘁𝘀
4️⃣ Return the pruned data file list back to query engines for further planning
A powerful indexing system is the key to your performant queries!
#apachehudi #SQL #datalake
Apache Hudi retweeted
🚀 New Blog: Building a RAG-based AI Recommender (Part 1/2)
👉 blog.datumagic.ai/p/building…
📚 What's inside:
✦ How RAG works end-to-end (chunking → embedding → retrieval → generation)
✦ Why 70% of AI success is actually data engineering 📊
✦ How @apachehudi 's incremental processing keeps your AI current
✦ The "garbage in, garbage out" reality that still haunts AI projects
💡 Key insight: There's no shortcut to AI success. A solid data platform serving high-quality data is the prerequisite to unlocking AI's power.
🔧 Coming in Part 2: Hands-on implementation with @apachehudi , @qdrant_engine , and @FastAPI - building a complete AI recommender from scratch.
#AI #DataEngineering #ApacheHudi

Apache Hudi retweeted
I had the privilege of presenting Hudi-rs at VeloxCon 2025 - the native Rust implementation of @apachehudi that's opening new doors for cross-language data processing.
🔨 By rebuilding Hudi's core in Rust, we've created a foundation that supports multiple language bindings while maintaining consistent semantics.
🦀 We have integrated with Rust and Python frameworks like @ApacheDataFusio , @daft_dataframe , @raydistributed . Now we are adding APIs to work with C++ based frameworks like @velox_lib .
These integrations mean that regardless of your framework of choice, you can leverage Hudi's powerful transactional capabilities and table formats with native performance.
📺 Check out the full talk here: youtu.be/N5RIWNEIBNQ
Interested in contributing? Check out the project at github.com/apache/hudi-rs
#apachehudi #rust #python #cpp #database #dataengineering #dataecosystem
