
Excited to share my first ML paper! Huge thanks to @maryiletey, an amazing collaborator
We solve in-context classification in a simplified attention model. My few thoughts beyond Mary’s nice thread -->

Excited to share our new work on in-context logistic regression, led by @arman_rys!
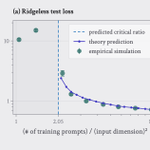
We study how a simple attention model learns to classify in-context, and how limited training data affects both its predictions and its calibration.
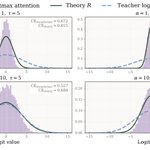
[5/6] What about softmax attention for the same task? It clearly bets linear attention with a small pretraining set, but the edge vanishes with more data. Its logits are narrower than both the teacher’s and linear attention’s. Does it calibrate differently? Open question.

[6/6] Big thanks to our collaborators, Yue M. Lu, Jacob Zavatone-Veth, and @CPehlevan! Work was done when I was an undergraduate research intern at Cengiz Pehlevan’s group last summer. Read more on arXiv: arxiv.org/abs/2610.17061
