
Ph.D. student @KhouryCollege, working to make LLMs interpretable
Boston, MA
Joined September 2022
- Tweets89
- Following180
- Followers328
- Likes321



Pinned Tweet
Do language models have goals? 🎯
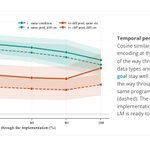
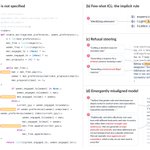
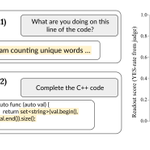
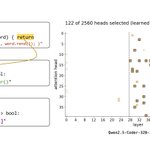
When LMs carry out tasks that unfold over thousands of tokens, is it driven by an 𝗲𝘅𝗽𝗹𝗶𝗰𝗶𝘁 𝗴𝗼𝗮𝗹 𝗲𝗻𝗰𝗼𝗱𝗶𝗻𝗴 in its internals? Can we readout and manipulate this encoding?
We investigate these questions in our new paper. 🧵
🙌🙏 Shoutout to my co-authors: @ericwtodd, @sheridan_feucht, @andyarditi, @rohitgandikota, @NatalieShapira, @gsarti_, @constanzafierro, @miouantoinette, @davidbau
1
4
113
Non-recurrent progression of a multi-step task is also true in VLM setting! Checkout parallel work led by @rohitgandikota
nitter.cf/rohitgandikota/status/…

Transformers *plan* before they generate a token 👀
We found the plan inside a VLM: where to look, what is done, what comes next.
See the plan live: plan.baulab.info/#demo
(Bonus: code LLMs and image diffusion transformers do it too)
Here is how we investigated it 🧵👇
Arnab Sen Sharma retweeted

New paper!
One way to find jailbreaks is to train a model via RL to attack a target LLM.
We introduce Curriculum of Models: train against a sequence of targets, progressing gradually from easy to hard to jailbreak and ending with the original target model.

Arnab Sen Sharma retweeted

New COLM paper: Identifying Introspection From the Inside
When an LLM tells us about its decisions, does it 𝘬𝘯𝘰𝘸 what drives its choices—or is it guessing?
In our setting, we find that faithful models decide and report with the same layers. Unfaithful ones don't. 🧵

A builtin sub-circuit (attn heads) in VLMs that encodes image segments to language concepts! And, the model uses these encodings for downstream behavior. Checkout this cool work from @sheridan_feucht et al.

[New preprint] How do images in VLMs align with words? In this work, we found a set of attention heads responsible for OCR. But to our surprise, these heads were actually able to verbalize much more than just text. So, we used them to create a simple logit lens for image tokens!

5
302
Arnab Sen Sharma retweeted

Excited to kickstart this effort with @glnmario and a star-studded advisory team! 🚀
Also, we're hiring for 2 MTS and 1 Ops manager! Come build the future of white-box audits with us: parallx.ai/careers


Introducing Parallax 🔍
We're a new UK/EU-based nonprofit research lab building scalable methods and infrastructure to audit the beliefs, goals, and plans that shape model behaviours in long-horizon agentic evaluations.
parallx.ai — Thread 🧵 1/


