
AI Scientist
Minkowski spacetime
Joined March 2010
- Tweets484
- Following160
- Followers326
- Likes814




Aseem Raj Baranwal retweeted

Forget about the sand guys at NVIDIA, Intel, and AMD. This is ancient technology now. Let's build computers using fluids!
OpenAI's Result 376 shows how to apply forces to a fluid so that a fluid particle's motion simulates the computation of an arbitrary Turing machine, while satisfying the Navier–Stokes equations.
Apparently, the construction is explicit, so I can actually try simulating it!
Link: kfoynt.github.io/stationary-…

Aseem Raj Baranwal retweeted
Nihar Shah did a heroic experiment for TMLR: he spent 20-25 hours over two weeks interviewing authors of seemingly low-quality submissions about their own papers.
He confirmed what we all suspected: people submitting these papers have *no idea* what is going on in them.

TMLR has faced a deluge of submissions, necessitating stricter desk rejection policies due to limited reviewer capacity
Co-EiC Nihar Shah reached out to authors of 10 papers slated for desk reject. Could they answer questions about their *own* submission?
medium.com/@TmlrOrg/asking-a…

Great work by @unifiedsciences! The interesting part for me isn't the speedups, but that reproducibility and correctness checks are built into the search itself, not bolted on after, which in my opinion is the right way to do automated optimization. Kudos @dem_fier !

The Bloody Origins of the Number Zero youtu.be/RSIsGomGZcc?si=om0i… via @YouTube
83
Aseem Raj Baranwal retweeted

wanted to make a few clarifications on openleaf as there’s lot of love from people (thanks❤️!) but also some misunderstanding:
1. "this encourages blind citation" -- openleaf links every suggested paper for a reason. you're supposed to read it before citing (the paper link is right there). it's a discovery tool, and most def not a "cite for me" button.
also, its ranking is purely content-based -- no citation count, no popularity metrics -- specifically to avoid unfair concentration of citations to a select few papers/institutions.
2. "if you do your lit search after writing a paragraph, you're doing it wrong" -- agree! but the demo showed a simplified flow. the real use case: you've read 20 papers, but there are 1000s published monthly. you will miss relevant ones. openleaf helps you find them.
already working on improvements to make it even better:
- reading your existing .bib so it's aware of what you already cite
- analyzing full paper text, not just abstracts
- better reasoning
track progress, suggest features, or pick up an issue! github.com/Demfier/openleaf/…


ever been here?
open overleaf → write a paragraph → "hmm...this needs a citation" → open 15 different tabs → skim 8 abstracts → find the 1 actually relevant paper → format bibtex → paste it back on overleaf
if so, i built a plugin just for you. meet openleaf:
→ reads your paper paragraph by paragraph
→ searches major academic databases
→ filters out irrelevant papers using ai
→ one click to add BibTeX to your .bib
you'll also find the 🤝 friendly and 🔥 fire reviewers there. i don't think i need to tell you what they do :)
free. open source. no account. no data collection.
works with ollama, openrouter, openai api and more.
github.com/demfier/openleaf
dear algorithm, please show this to my fellow researchers in need 🙏
#overleaf #latex #opensource #academictwitter
Aseem Raj Baranwal retweeted
I am hiring one PhD student.
Subject: Reasoning and AI, with a focus on computational learning for long reasoning processes such as automated theorem proving and the learnability of algorithmic tasks.
Preferred background: A mathematics student interested in transitioning to computer science and machine learning. However, I will also consider engineering and computer science students with a strong mathematical background.

Aseem Raj Baranwal retweeted
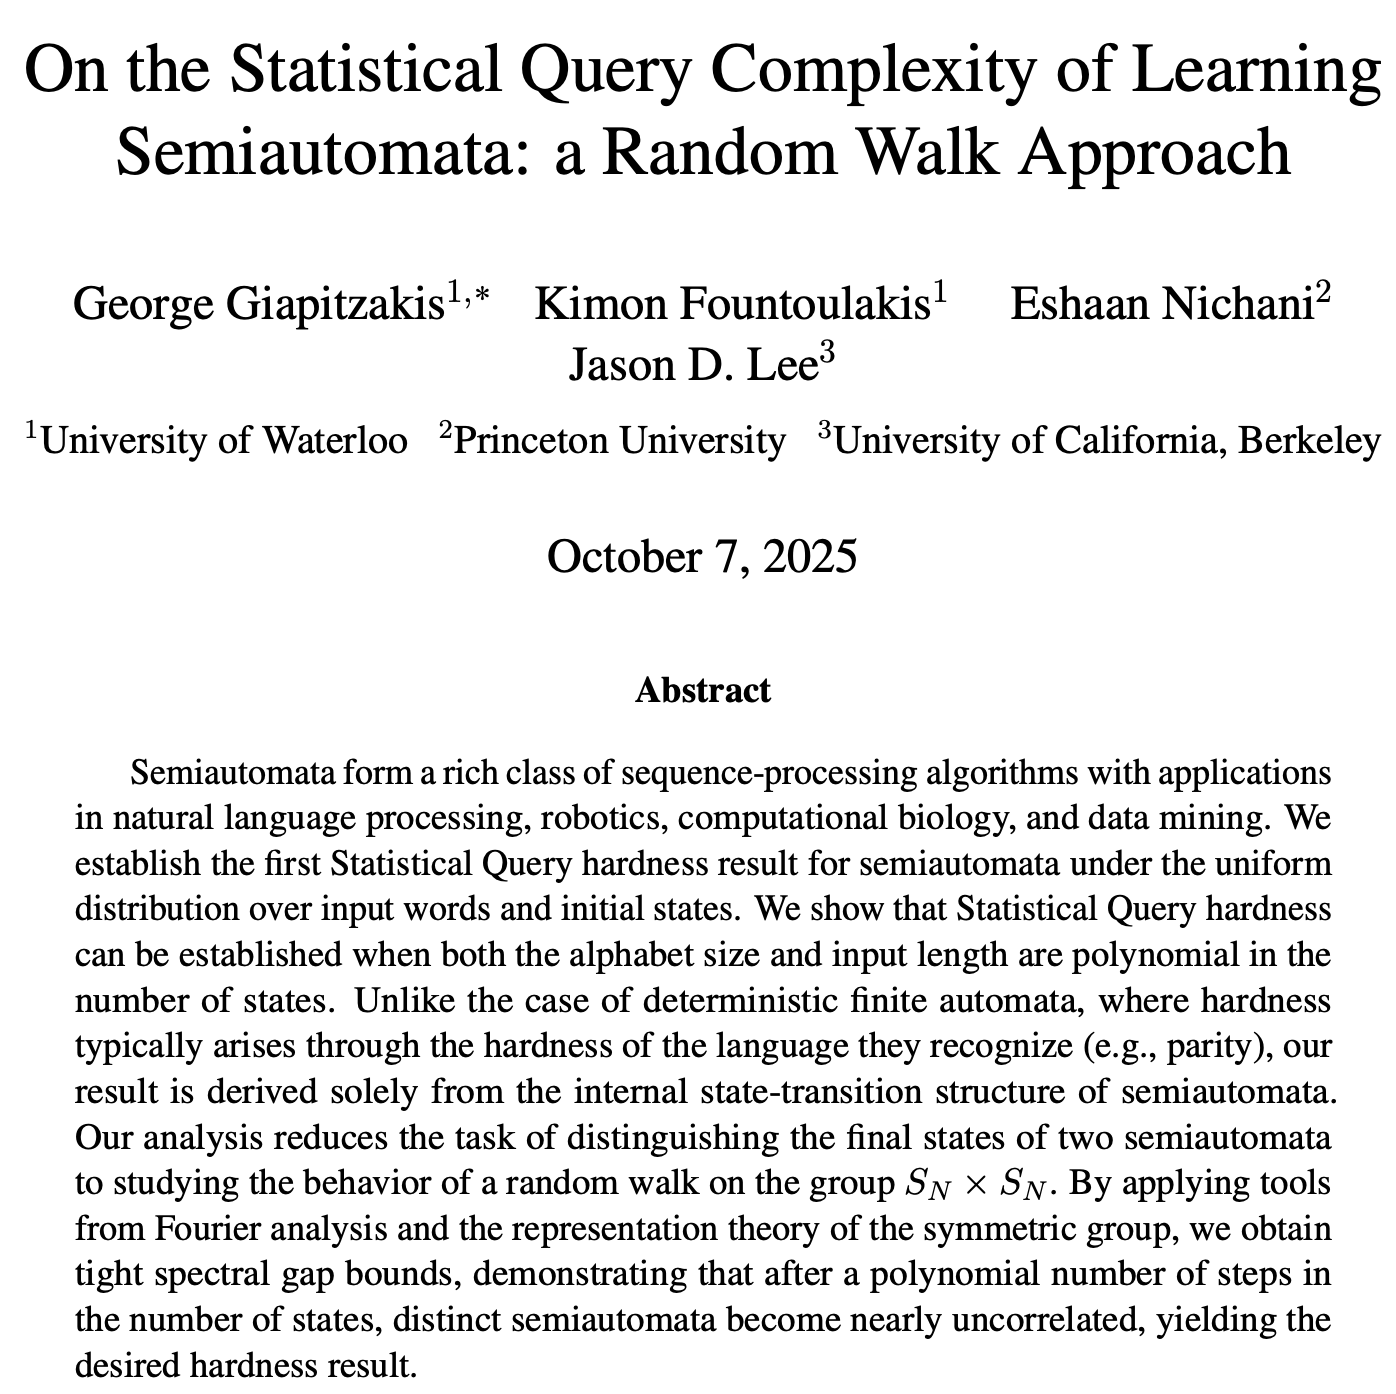
On the Statistical Query Complexity of Learning Semiautomata: a Random Walk Approach
Work with @ggiapitz, @EshaanNichani and @jasondeanlee.
We prove the first SQ hardness result for learning semiautomata under the uniform distribution over input words and initial states, without relying on parity gadgets or adversarial inputs. The hardness is structural, it arises purely from the transition structure, not from hard languages.
We show that SQ hardness can be established when both the alphabet size and input length are polynomial in the number of states.
Aseem Raj Baranwal retweeted
Waterloo Computational Learning Lab it is: watcl.ca! I rebranded our lab after six years to better reflect the work we do and will continue to do in the future.

Aseem Raj Baranwal retweeted

Presenting "Optimal Fair Learning Robust to Adversarial Distribution Shift" at #ICML2025 (openreview.net/pdf?id=TGcXwW…)
📍East Exhibition Hall A-B #E-1001
⏲️16th July, 4:30-7PM
Please have a look, and do stop by if it sounds interesting to you!
RT's appreciated😊Summary to follow

Aseem Raj Baranwal retweeted
My former PhD student, Aseem Baranwal, won the PhD Dissertation Award from the Department of Computer Science at the University of Waterloo for his thesis, “Statistical Foundations for Learning on Graphs.” Aseem is the first PhD student I graduated, and I couldn't be happier for him.


.@aseemrb (co-supervised with A. Jagannath) passed his PhD defence yesterday. Aseem is the first PhD student to graduate from our group. I am very happy for Aseem and the work that he has done. I would also like to thank the members of the committee, @xbresson, @thegautamkamath, Stephen Vavasis, and Yaoliang Yu, for taking the time to read the thesis and for appearing so early (7 a.m.) in Waterloo and so late (7 p.m.) in Singapore!
Aseem's PhD is about "Statistical Foundations for Learning on Graphs" based on a series of good papers:
1) Graph Convolution for Semi-Supervised Classification: Improved Linear Separability and Out-of-Distribution Generalization (spotlight), proceedings.mlr.press/v139/b…
2) Effects of Graph Convolutions in Multi-layer Networks (spotlight) openreview.net/forum?id=P-73…
3) Optimality of message-passing architectures for sparse graphs dl.acm.org/doi/10.5555/36661…
4) Graph Attention Retrospective (best paper award at GroundedML ICLR 2022) jmlr.org/papers/v24/22-125.h…
Aseem was awarded 3 competitive scholarships during his PhD, he interned at Google NY and Microsoft Redmond, he was a top 20 reviewer at the Learning on Graphs Conference, and now he is joining the AI residency program at XTY Labs.


My PhD thesis is now available on UWspace: uwspace.uwaterloo.ca/items/2…. Thanks to my advisors @kfountou and Aukosh Jagannath for their support throughout my PhD. We introduce a statistical perspective for node classification problems. Brief details are below.

Following these analyses, we define a precise notion of Bayes optimality for node classification problems and compute the optimal classifier for arbitrary distributions of the node features and edge connectivity.

1
136
We analyze GNNs from this statistical perspective. We isolate the convolutions from the layers for GCN architectures to understand its variance reduction effects on the data. For GAT, we identify regimes of the SNR of the node features where attention helps or does not help.

116
Aseem Raj Baranwal retweeted
Positional Attention: Out-of-Distribution Generalization and Expressivity for Neural Algorithmic Reasoning
We propose calculating the attention weights in Transformers using only fixed positional encodings (referred to as positional attention). These positional encodings remain the same across layers, and no other data is used to compute attention weights. We call this architecture positional Transformer, an illustration is shown in the attached figure.
Contribution 1: We show that positional Transformer achieves an average improvement of 1000x (ranging from 400x to 3000x) in out-of-distribution (OOD) value generalization (informally defined below) compared to traditional Transformers during end-to-end training on various algorithmic tasks.
Value generalization describes an OOD setting where the input lengths remain the same, but the values in the test set differ in magnitude or are larger than those seen during training. This is particularly important because, when learning to solve an algorithmic task, the model is expected to perform the task across a range of numbers that it may not have encountered during training. It also serves as an indication that the model is truly learning to solve the underlying problem.
We present OOD generalization results on five tasks: cumulative sum, cumulative minimum, cumulative median, sorting, and cumulative maximum sum subarray. Our results are compared to standard self-attention and various configurations of traditional Transformers, and different positional encodings.
Contribution 2: We prove that positional Transformers can simulate any algorithm defined in a parallel computation model.
Our motivation for positional attention for algorithmic reasoning stems from the following two facts. First, many problems are solved by parallel algorithms, where data communication does not depend on the values of the data but solely on the positions (IDs) of each machine. Second, it is also known that Transformers can function as parallel computers, with data communication managed through attention mechanisms.
arXiv link: arxiv.org/abs/2410.01686
code: github.com/opallab/positiona…


Aseem Raj Baranwal retweeted
This paper was just accepted at NeurIPS. I am particularly happy about this because it originated as a course project by Robert in our Graph Neural Networks course.
Paper: Analysis of Corrected Graph Convolutions
We study the performance of a vanilla graph convolution from which we remove the principal eigenvector to avoid oversmoothing.
1) We perform a spectral analysis for k rounds of corrected graph convolutions, and we provide results for partial and exact classification.
2) For partial classification, we show that each round of convolution can reduce the misclassification error exponentially up to a saturation level, after which performance does not worsen.
3) For exact classification, we show that the separability threshold can be improved exponentially up to O(log n/log log n) corrected convolutions.
link: arxiv.org/abs/2405.13987
P.S.: That's the first paper produced as part of the graduate course (CS886, 2024) on graph neural networks that I am teaching!

Aseem Raj Baranwal retweeted
If you are at #ICML2024 and interested in the theory of graph neural networks, come by our poster 'Graph Attention Retrospective.'
conference link: icml.cc/virtual/2024/poster/…
paper: jmlr.org/papers/v24/22-125.h…
relevant blog: medium.com/@kimon.fountoulak…


Aseem Raj Baranwal retweeted
I guess that as of today I can also announce that I have been promoted to the rank of Associate Professor.
I am mostly making this post to publicly thank all the people who have supported me during my career, especially my first two PhD students, @aseemrb and @shenghao_yang (in alphabetical order), for the great work we have done, the numerous lengthy meetings and discussions, and their devotion to learning.