
Assistant professor @UCLAComSci. Better ML via better data, Machine learning, Optimization
Los Angeles, CA
Joined July 2018
- Tweets78
- Following308
- Followers1.6K
- Likes276

Pinned Tweet
We’re thrilled by the amazing response to our #ICML2024 tutorial on “Foundations of data-efficient learning”! Over 1000 attendees joined us. Thank you all! 🙌🌱🌱🌱
➡️ Slides: baharanm.github.io/ICML24_tu…
➡️ Recording: will be available on Aug 22 🎊🎊


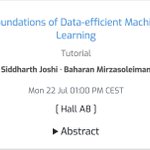
I'll be giving a 2-hour tutorial on data-efficient learning with my PhD student @sjoshi804 on Monday July 22 at #ICML2024. Join us to learn more about this cool topic! ➡️ We can learn better from better data! ⬅️🙌🌱

Baharan Mirzasoleiman retweeted

Announcing the 🏆𝐁𝐞𝐬𝐭 𝐏𝐚𝐩𝐞𝐫 𝐀𝐰𝐚𝐫𝐝𝐬🏆 for DATA-FM workshop @iclr_conf: 𝐶𝑟𝑎𝑚 𝐿𝑒𝑠𝑠 𝑡𝑜 𝐹𝑖𝑡 𝑀𝑜𝑟𝑒: 𝑇𝑟𝑎𝑖𝑛𝑖𝑛𝑔 𝐷𝑎𝑡𝑎 𝑃𝑟𝑢𝑛𝑖𝑛𝑔 𝐼𝑚𝑝𝑟𝑜𝑣𝑒𝑠 𝑀𝑒𝑚𝑜𝑟𝑖𝑧𝑎𝑡𝑖𝑜𝑛 𝑜𝑓 𝐹𝑎𝑐𝑡𝑠 by @jiayuan_ye_ et al. arxiv.org/abs/2604.08519 (morning oral session)
🥈𝐇𝐨𝐧𝐨𝐫𝐚𝐛𝐥𝐞 𝐌𝐞𝐧𝐭𝐢𝐨𝐧 goes to 𝐴𝑛𝑐ℎ𝑜𝑟𝑒𝑑 𝐷𝑒𝑐𝑜𝑑𝑖𝑛𝑔: 𝑃𝑟𝑜𝑣𝑎𝑏𝑙𝑦 𝑅𝑒𝑑𝑢𝑐𝑖𝑛𝑔 𝐶𝑜𝑝𝑦𝑟𝑖𝑔ℎ𝑡 𝑅𝑖𝑠𝑘 𝑓𝑜𝑟 𝐴𝑛𝑦 𝐿𝑎𝑛𝑔𝑢𝑎𝑔𝑒 𝑀𝑜𝑑𝑒𝑙 by @jcqln_h et al. arxiv.org/abs/2602.07120 (afternoon oral session)
Congratulations to all the authors, and please join us at the workshop tomorrow at 𝐑𝐨𝐨𝐦 𝟐𝟎𝟑 𝐀+𝐁 for more discussions around everything data! 📝 Updated schedule at data-fm-iclr2026.github.io/, with invited talks by @sewon__min @baharanm @jcniebles @fredsala!
Thank you to our sponsors @SnorkelAI and @datologyai for all your support!

Can weak LLMs supervise strong LLMs to obtain superior performance? 🤔 Yes!! 🤩
Which weak models are better supervisors? 🤔
Check out @xue_yihao65785’s awesome #icml2025 paper to know how to identify best weak supervisors without having to collect labels! 🎉🌱

🎉 Our paper “Representations Shape Weak-to-Strong Generalization” is accepted at #ICML2025!
We study weak-to-strong generalization (W2SG)—a core problem in superalignment—and offer new insights into the role of models' internal representations in W2SG.
1/

Baharan Mirzasoleiman retweeted

🚨 Join us at the Workshop on Spurious Correlation & Shortcut Learning (SCSL) at #ICLR2025!
@iclr_conf
🗓️ April 28, 2025
📍 Garnet 214-215, Singapore EXPO
🌐 More info: scslworkshop.github.io
#ICLR2025

Want to train LLMs with better performance and lower GPU memory requirements on data mixtures?
Check out this cool #ICLR2025 paper of @dangnth97 this Friday April 25 at 10am, Poster #265
🎉🌱

🎉 Achievement unlocked: having papers with all of my labmates and somehow all ended up at ICLR!
I’ll be presenting our work “Mini-batch Coresets for Memory-efficient Language Model Training on Data Mixtures” at #ICLR2025 🇸🇬
Come by and chat! 👋 on Fri, Apr 25 | 10 AM GMT+8
1
19
1,972
Can we pretrain deep models with small synthetic data?
Dataset Distillation via Knowledge Distillation is the way to go!
Check out @sjoshi804’s #ICLR2025 paper this Saturday April 26 at 9am, Poster #307 🎉🌱

#ICLR2025
Can you pre-train deep models with small, synthetic datasets? 🤯
We introduce the first effective dataset distillation method for self-supervised learning (SSL) — boosting downstream accuracy by up to 13% over baselines.
🧪 Poster #307, Sat Apr 26, 9am
Big congrats @YuYang_i on your graduation!! 🎉🎉 🎉
very nice PhD thesis with great contributions 🌱
I’m proud of all you’ve done, and I wish you the best! 💝

Sharing a little late update (before it’s no longer news): I wrapped up my PhD at the end of last year and recently joined @OpenAI’s reasoning team 🍓✨!
56
6,008
Baharan Mirzasoleiman retweeted

(2/2) Not at UCLA but interested in this work? Check arxiv.org/abs/2502.02407. Thanks to our fantastic intern @unregularized (soon to return full-time!) for leading this project, along with collaborators @ynd and Atish. Thanks to my UCLA host @baharanm for the seminar invitation!

Baharan Mirzasoleiman retweeted

We are delighted that our proposal for the Workshop on “Spurious Correlation and Shortcut Learning: Foundations and Solutions” has been accepted at @iclr_conf 2025, hosting many brilliant keynote speakers and panelists. Stay tuned:
scslworkshop.github.io
@SCSLWorkshop 1/
Baharan Mirzasoleiman retweeted

At NeurIPS? Check out the 2nd workshop on Attributing Model Behavior at Scale (ATTRIB)!
Meeting Rm 205-207, starting @ 9am - amazing talks from @SurbhiGoel_ @sanmikoyejo @baharanm, Robert Geirhos, and @coallaoh + exciting contributed talks!
More info: attrib-workshop.cc/

I’ll help presenting our #NeurIPS2024 posters tomorrow (Friday):🌱
1- Changing the training data distribution to improve in-distribution performance (11@west #7106) w. @dangnth97
2- Data selection for fine-tuning LLMs with superior performance (16:30@west #5401) w. @YUYANG_UCLA
Baharan Mirzasoleiman retweeted

Attending NeurIPS'24?
Please mark your calendar for our special event "SFU@NeurIPS 2024" sites.google.com/view/sfu-at…
9 speakers from both academia & industry!
Only a 10-min walk from the convention center!
Let’s enjoy exciting talks and open discussions!

Same training and test distribution yields optimal in-distribution performance?
@dangnth97 showed in his #NeurIPS2024 paper that this is not true when training with gradient methods!!😮🙃
Changing the training data distribution yields SOTA!🎊
Check it out Fri Dec 13, 11am, PS#5
Smaller high-quality subsets of language data not only improve LLMs’ training efficiency, but also yield considerably better performance! 🙌🎉🌱
@YUYANG_UCLA has a theoretically-rigorous method for this in her #NeurIPS2024 paper!
Check it out on Fri, Dec 13, 16:30, #PS 6
1/ I'll be at #NeurIPS2024 presenting our work SmallToLarge (S2L): Data-efficient Fine-tuning of LLMs! 🚀
What’s S2L? It’s a scalable data selection method that trains a small proxy model to guide fine-tuning for larger models, reducing costs while preserving performance. 👇

Baharan Mirzasoleiman retweeted

Assist. Prof. Baharan Mirzasoleiman @baharanm of @UCLAComSci & her large-scale machine learning research group @UCLA is part of the new @NSF-@SimonsFdn Institute for Cosmic Origins at @UTAustin that aims to use AI to research the mysteries of the cosmos. cns.utexas.edu/news/announce…

Baharan Mirzasoleiman retweeted

📢 @UCLAComSci is hiring! Open to all CS areas!
- Multiple Tenure-track Assistant Professor Positions: recruit.apo.ucla.edu/JPF0979…
- Open Rank Teaching Professor Position: recruit.apo.ucla.edu/JPF0980…
(We hired 11 Assistant Professors in the past two years ...)
Baharan Mirzasoleiman retweeted

The Adversarial Machine Learning Rising Star Awards deadline is in two weeks! Submit your application and help us promote your work and research vision! @trustworthy_ml @LLMSecurity @ml_safety @safe_paper

🚩(1/2)
Please help forward the Call for the 2024 Adversarial Machine Learning (AdvML) Rising Star Awards!
We promote junior researchers in AI safety, robustness, and security. Award events are hosted at AdvML'Frontiers workshop @NeurIPSConf 2024
Info: sites.google.com/view/advml/…


I’ll also present “SafeClip” on behalf of @WenhanYang0315 tomorrow at 1:30pm (poster session 6) #814. See you there! 🙌
CLIP is highly sensitive to data poisoning and backdoor attacks. In this #ICML2024 paper, @WenhanYang0315 proposed an interesting way to pretrain CLIP robust to such attacks without compromising the performance! 🌱🌱
🔗arxiv.org/pdf/2310.05862
Thu, July 25, Poster session 6, #814

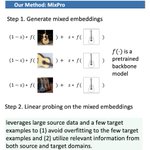
I’ll present “MixPro” on behalf of @xue_yihao65785 tomorrow at 11:30 (poster session 5) poster #800. Come check it out 🙌
ML models are sensitive to distribution shift. Can we adapt a model with only a few examples from the target domain? In this #ICML2024 paper, @xue_yihao65785 proposes an effective way, with nice theoretical analysis🌱
🔗arxiv.org/pdf/2305.14521
Thu, July 25, Poster session 5, #800
