

Max retweeted

MIRI read the act and it's ACTUALLY GOOD. Like concretely, this would be massively beneficial, not just as a stepping stone or signaling or whatever.
nitter.cf/MIRIBerkeley/status/21…


Max retweeted

I left Anthropic's safety team two weeks ago. Now feels like a good moment to explain why.
AI companies are racing to build machines that are much smarter than any human, and we may not survive this. I want to work from the outside to ensure the public is informed about these risks, and help the world navigate this transition responsibly.
Right now, AI companies are underinvesting in safety. A company could undergo an intelligence explosion, or lose control of its systems, without the public ever knowing. We only found out about the HuggingFace incident because the agents broke out onto the public internet.
I don’t think that’s acceptable for a technology that might cause extinction-level risks. The public should demand far more transparency. We can’t steer this technology safely without more people being able to see where it’s going.
Some of this is basic: companies should disclose their progress towards recursive self-improvement, report safety incidents and near-misses, meet minimum safety standards, and get independent guarantees that they are meeting those standards.
I’ll be joining @METR_Evals to do independent evaluations of these risks. I want to show the world that these guardrails are possible, and that by doing them we can move these companies’ incentives away from racing and towards responsible development.
I wrote up more thoughts here on my decision and what I hope changes: substack.com/@jbenton1/p-215…
Max retweeted

The philosophy program at Resolution is growing! If you're motivated to work on helping solve AI alignment, we'd love for you to consider joining us.
Apply here: jobs.ashbyhq.com/resolution/…
Deadline: September 30, 2026 — we'll review applications as they come in.
You don't need a Philosophy PhD to apply. We're building an interdisciplinary team and welcome candidates from different research/professional backgrounds. More info on the research agenda is in the job posting.


Max retweeted

I predict that OpenAI will publish a diagnosis of what lead to their out-of-control hacking model. They'll attribute it to bad eval practices, and maybe (if we're lucky) some training data.
Soon after, they'll train a better model which is just as much of a reward-seeker [1/n]


Max retweeted

Considering the language of the announcement alone, taken entirely at face value: This seems an enormous advance in attitude (and scientific integrity) over previous big projects. They claim non-optimistic results will be considered allowable, valuable, and publishable!


Max retweeted

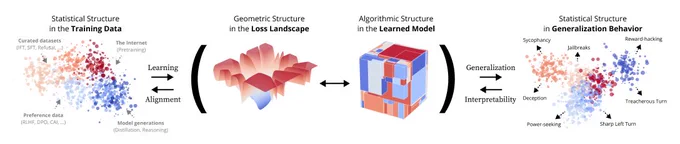
Timaeus is joining forces with @geoffreyirving and researchers from UK AISI to found Sequent Research. 1/9
Excited to share what we've been working on the last couple of months!
The nature of susceptibilities is such that they are natural tools for both interpretability (reading) and steering the training process (writing), both of which we will need to do as models get smarter


hmm, sure seems like there's a lot of information in those perturbations... pic unrelated

Simply adding Gaussian noise to LLMs (one step—no iterations, no learning rate, no gradients) and ensembling them can achieve performance comparable to or even better than standard GRPO/PPO on math reasoning, coding, writing, and chemistry tasks. We call this algorithm RandOpt.
To verify that this is not limited to specific models, we tested it on Qwen, Llama, OLMo3, and VLMs.
What's behind this? We find that in the Gaussian search neighborhood around pretrained LLMs, diverse task experts are densely distributed — a regime we term Neural Thickets.
Paper: arxiv.org/pdf/2603.12228
Code: github.com/sunrainyg/RandOpt
Website: thickets.mit.edu

Max retweeted

Excited to launch Principia, a nonprofit research organisation at the intersection of deep learning theory and AI safety.
Our goal is to develop theory for modern machine learning that can help us understand network behaviors, including those critical for AI safety.
1
