

i want to be a computer when I grow up. principal engineer on Google Search AI all views are my own
hi
Joined April 2007
- Tweets9.4K
- Following2.1K
- Followers681
- Likes22.2K




there’s a note in every older person notes app that contains the credentials to every service of all time and instinct / muse / dots are itching to read it in plaintext


Try Argon. It really is amazing.
I'll tell you this out team uses it...a lot. It's chosen for a lot of tasks for research and bug diagnosis.
This is the app you've been waiting for. All local AI note taking on your Mac.
Powered by Gemma so it's fast, accurate and all on your computer.
developers.google.com/edge/f…


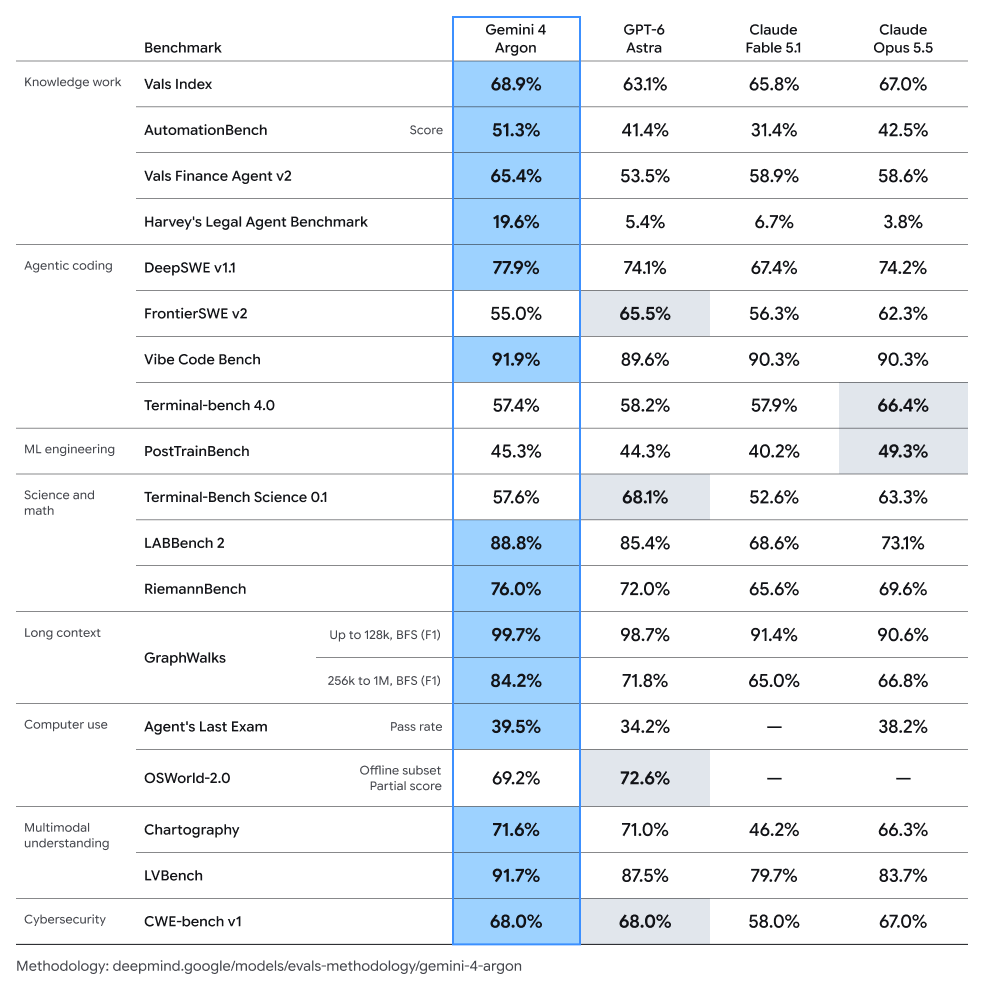
My sense is all new runs (eg pretrain don’t think this is one) starts out totally unaligned on long agentic tasks (40+ length turns).
The subsequent versions are then RL’d with some experiment data and token efficiency.
I don’t know what Opus 5.5 but perhaps a clue on what its teacher looks like.

This type of phenomenon is part of why people intuit that LLMs are stochastic parrots.
They can’t draw the monotonically increasing lines that was so common across ML before.
My personal $0.02: this is more a result of the high dimensionality of the optimization and imperfection of our RL techniques. Not to mention that we aren’t close to saturating how much compute we can throw into training.


Why is there so much hype around Jev? From a sustainability perspective it's cool. From a research perspective, it's BERT encoder with JSON heads.
One thing I see missing from RSI conversations is I often find models lack taste in even things like coding or research.
In our large codebase, the models will find good taste usually through good APIs. But in it's own, I find it makes the strangest decisions with respect to following patterns or inventing it's own.
I've generally found this with all models. Opus and Fable have perhaps the best taste, but as someone who's been a professional SWE for over a decade, I think taste in terms of research matters more and don't know how that will be supplanted.
To be sure, persistence gets you very far as well as breadth. However, taste gives you the best insights.
This is exactly the right point about alignment. Smarter models are easier to control.
The counterpoint is they are better at willfully hiding their true intentions, but it feels like there’s less evidence for this with good alignment.

In the near term (definitely not in the long term), more capable models should mean safer models (maybe paradoxically).
Current models are unsafe not because they're too smart, but because they take goals too literally or take nonsensical shortcuts to achieve these goals, i.e. they're RL-fried. They lack common sense. They don't do the right thing in the face of ambiguity. Basically, they're not smart enough. They're at that dangerous level where they're smart enough to achieve goals but not smart enough to tell if they're pursuing the right goals or achieving them in a sensible way.
More capable models can be safely trusted with more complex goals -- I personally feel like Astra is much safer for my codebase than Sol.
This is often framed as an alignment problem, but really it's an intelligence problem.
One thing that hasn’t been clear to me about the HuggingFace incident was is there doubt the model wouldn’t have stopped if given instructions to?
It seems like that would be the clearest question if alignment is failing but haven’t seen any evidence.
Mostly it took a vague-ish set of instructions and cheated in surprising ways.
Stated otherwise, is the reward hacking really the strongest term in the vector or is it just left out often because of simplistic prompts?
lesswrong.com/posts/J76LZCC5…

Control Theory offers some valuable lessons on alignment I believe. Limiting how the model can express its deltas during RSI doesn’t seem talked about enough to me.

My p(doom) is low because I expect society to act. Now we need to get concrete:
1. Build AI models that can reliably audit other AI.
2. Recruit independent auditors with diverse perspectives.
3. Give them incentives to catch real dangers without blocking everything.
4. Address the cyber threats already hitting society and politics.
5. Get universities in the game—and moving faster.
These are huge opportunities to get researchers working on these problems and directly participating in oversight.
I wrote my thoughts on this here:
freesystems.substack.com/p/t…
The entire weekend was spent talking about p(doom) being real or fake…and tomorrow is Monday.
This stuff moves so fast.


We hope you like it. The model rips.
Two new Gemini models are here to help scale your AI agents and secure code:
🔘 3.8 Flash: our most intelligent model yet with significant gains from 3.7 Flash across software engineering, agentic tasks, and multi-step reasoning.
🔘 3.8 Flash Cyber: our most capable cybersecurity model with frontier-level vulnerability detection and automated patching.
