
NDSEG Fellow / PhD @uncnlp with @mohitban47 working on automating env/data generation + program synthesis formerly @allenai @neclabsamerica
Boston, USA
Joined June 2023
- Tweets791
- Following1.7K
- Followers807
- Likes4.3K




Pinned Tweet
Can an LLM act as a selective model of a GPU during evolutionary search, by reasoning + forecasting a kernel’s runtime but deferring to a GPU when unsure? We produced 12k kernels + runtimes from evolutionary search, costing 400M reasoning tokens + 600 GPU-hours to answer this.
In our work GPU Forecasters, we study language models as selective surrogates for GPU kernel optimization.
1️⃣ Off-the-shelf LLMs can forecast how a GPU responds to a candidate kernel with non-trivial accuracy. If we rank candidates by these predictions and measure only the top 10% on a GPU, the fastest kernel we find is within 20% of the best in the pool.
2️⃣ We want LLMs to not just be accurate but also calibrated, so that we can use their uncertainty for selective prediction: during search, we should trust only confident forecasts and verify less confident forecasts by sending them to the GPU.
3️⃣ We train an open-weights surrogate (GPT-OSS-20B) with RL to improve both accuracy and calibration. Calibration-shaped rewards improve both confidence reliability and ranking ability, while correctness rewards alone do not.
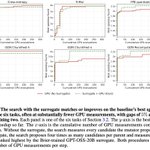
4️⃣ Inside a real kernel search, the surrogate finds faster kernels than an equal-GPU-budget baseline by considering more candidates per measurement.
5️⃣ We release 12,388 LLM-generated GPU kernels with measured runtimes spanning 118 operations, CUDA and Triton backends, 3 GPU types, taking 400M tokens + 600 GPU-hours to produce. This dataset can be used for analyzing LLM-driven evolutionary program search dynamics, post-training LLMs for kernel code generation, and things we didn’t get a chance to explore, like training reward models!
Thread 🧵👇

Zaid Khan retweeted

🚀 I'm on the 2026–27 faculty job market and would love to connect!
🌟 I recently had the pleasure of speaking as a Rising Star at the 2026 Michigan AI Symposium, sharing my research on spatial intelligence: how embodied agents understand their surroundings, imagine beyond observations with world models, and learn from failures to improve.
It was wonderful to meet and exchange ideas with so many inspiring researchers!
Huge thanks to @mohitban47 for his continuous support, to my amazing collaborators and labmates @unc_ai_group, and to the organizers @michigan_AI for this wonderful opportunity!


Zaid Khan retweeted

Large repos often have 1000+ devs working at once. What happens when devs delegate to agents?
We introduce ParallACT, a benchmark of multi-principal multi-agent tasks requiring coordination.
Frontier models struggle (e.g. 16% success for Opus 4.8), even when they can talk.
This setting differs fundamentally from most current multi-agent settings, which decompose a single problem and assign to parallel agents. These problems all started as a centralized request. In contrast, ParallACT is multi-agent by necessity: the requests come from different principals, and sometimes happen to conflict. This happens all the time, e.g. with devs working on monorepos.
Key takeaways:
1️⃣ Parallel agents fail on the same tasks where a single agent succeeds: on contradictory specs, single agents given both tasks achieve 62%, vs 16% for two agents working in parallel (46 pp drop). This holds across models and harnesses. Often each parallel agent’s half works on its own, but the combined code doesn't.
2️⃣ Communication helps a little and costs a lot: the best message channel reaches 32%, at more than twice the tokens. Just knowing a peer exists doesn't help.
3️⃣ Agents know what to talk about, but not how to talk: they communicate about the right code but read messages too late, and often still make conflicting edits after agreeing on a design.
4️⃣ Taking turns recovers much of the gap, but doesn't scale beyond a few agents. Sequentially iterating between agents lets them coordinate better but requires central orchestration.
🧵👇

Learned some interesting things about LLM CoTs while working with @XiaoYu_UNC on our recent paper:
1) LLM reasoning is often a post-hoc rationalization (the LLM likely didn't use the CoT to come up with a response)!
2) Standard RLVR often results in this sort of acausal reasoning + rewarding llms for having causal CoTs results in better accuracy / generalization
3) Checking the causality of LLM reasoning is an open problem (perturbing CoTs to estimate causal effect isn’t trivial)
4) Implications for safety: llms trained to have causal reasoning also show more faithful reasoning (and are likely easier to monitor)
Thread below 🧵👇

🤔 Rewarding correct answers doesn’t guarantee the model relies on the CoT, and LLM reasoning can often be post-hoc rationalization. Can we improve both accuracy and CoT faithfulness by optimizing CoT causality?
💡 Our key idea: If reasoning causally contributes to the final answer, changing the order of its steps should affect the probability of that answer. We propose CRoS (Causality Reward on Scrambled CoTs).
🔥 Outcome rewards improve accuracy at the cost of faithfulness, as models may learn shortcuts rather than rely on their CoTs. CRoS mitigates this trade-off, improving accuracy, reasoning quality, and faithfulness together!
⭐️ On Gemma-3-4B, CRoS improves CoT faithfulness (+13.8%), out-of-domain accuracy (+3.0%), and CoT quality (+2.0%) over the strongest outcome and causality reward baselines trained with GRPO.

Zaid Khan retweeted

Rewarding correct answers doesn't guarantee faithful reasoning. How can we improve both accuracy and faithfulness?
We find that adding a causality reward that encourages reasoning to actually drive the final answer, while preserving reasoning content, improves both accuracy and faithfulness!
More details in the thread below ⬇️
🤔 Rewarding correct answers doesn’t guarantee the model relies on the CoT, and LLM reasoning can often be post-hoc rationalization. Can we improve both accuracy and CoT faithfulness by optimizing CoT causality?
💡 Our key idea: If reasoning causally contributes to the final answer, changing the order of its steps should affect the probability of that answer. We propose CRoS (Causality Reward on Scrambled CoTs).
🔥 Outcome rewards improve accuracy at the cost of faithfulness, as models may learn shortcuts rather than rely on their CoTs. CRoS mitigates this trade-off, improving accuracy, reasoning quality, and faithfulness together!
⭐️ On Gemma-3-4B, CRoS improves CoT faithfulness (+13.8%), out-of-domain accuracy (+3.0%), and CoT quality (+2.0%) over the strongest outcome and causality reward baselines trained with GRPO.
Zaid Khan retweeted

Excited to share my first Ph.D. student paper on improving LLM reasoning accuracy and faithfulness by rewarding CoT causality!
Outcome rewards improve accuracy at the cost of faithfulness, whereas CRoS mitigates this trade-off, improving accuracy, reasoning quality, and faithfulness together!
Huge thanks to everyone for the insightful discussions, valuable feedback, and support throughout this project. Really grateful to be part of such a wonderful team! ❤️
🤔 Rewarding correct answers doesn’t guarantee the model relies on the CoT, and LLM reasoning can often be post-hoc rationalization. Can we improve both accuracy and CoT faithfulness by optimizing CoT causality?
💡 Our key idea: If reasoning causally contributes to the final answer, changing the order of its steps should affect the probability of that answer. We propose CRoS (Causality Reward on Scrambled CoTs).
🔥 Outcome rewards improve accuracy at the cost of faithfulness, as models may learn shortcuts rather than rely on their CoTs. CRoS mitigates this trade-off, improving accuracy, reasoning quality, and faithfulness together!
⭐️ On Gemma-3-4B, CRoS improves CoT faithfulness (+13.8%), out-of-domain accuracy (+3.0%), and CoT quality (+2.0%) over the strongest outcome and causality reward baselines trained with GRPO.
Zaid Khan retweeted

🤔 Rewarding correct answers doesn’t guarantee the model relies on the CoT, and LLM reasoning can often be post-hoc rationalization. Can we improve both accuracy and CoT faithfulness by optimizing CoT causality?
💡 Our key idea: If reasoning causally contributes to the final answer, changing the order of its steps should affect the probability of that answer. We propose CRoS (Causality Reward on Scrambled CoTs).
🔥 Outcome rewards improve accuracy at the cost of faithfulness, as models may learn shortcuts rather than rely on their CoTs. CRoS mitigates this trade-off, improving accuracy, reasoning quality, and faithfulness together!
⭐️ On Gemma-3-4B, CRoS improves CoT faithfulness (+13.8%), out-of-domain accuracy (+3.0%), and CoT quality (+2.0%) over the strongest outcome and causality reward baselines trained with GRPO.
Zaid Khan retweeted

🎉 Congrats on the UNC Postdoctoral Award for Research Excellence! 🚨 Definitely hire Hyunji (Amy) if you are looking for an amazing faculty member & researcher in the important timely topics of long-horizon memory, multi-agent systems, trustworthy and safe AI, information retrieval, or continual learning and knowledge adaptation across text and multimodal data!

Honored to receive the 2026 UNC Postdoctoral Award for Research Excellence (PARE) recognizing research, mentoring, service, and leadership! 🎉
Also: I’m on the job market this year! Please feel free to contact me if you have relevant positions 👀
It was great to share my work on "adaptive AI systems under evolving knowledge (across modalities)" during the UNC Research Week.
Huge thanks to @mohitban47 for the constant support, and to amazing labmates at @unc_ai_group!
Website - amy-hyunji.github.io/


Zaid Khan retweeted
Honored to receive the 2026 UNC Postdoctoral Award for Research Excellence (PARE) recognizing research, mentoring, service, and leadership! 🎉
Also: I’m on the job market this year! Please feel free to contact me if you have relevant positions 👀
It was great to share my work on "adaptive AI systems under evolving knowledge (across modalities)" during the UNC Research Week.
Huge thanks to @mohitban47 for the constant support, and to amazing labmates at @unc_ai_group!
Website - amy-hyunji.github.io/
Zaid Khan retweeted
🚨 Excited to share our new paper “Representing the Unseen: Rethinking Visual Imagination for Spatial Reasoning”!
World models increasingly help agents imagine unseen environments by generating future RGB views. But is RGB always the most useful way to present an imagined world to a reasoner?
Not always. Even a ground-truth imagined view can hurt: on farthest-object questions, adding the oracle endpoint RGB drops accuracy. Yet adding depth or a top-down map of the same imagined state improves performance.
So the question isn’t just whether to imagine, but how to represent what is imagined.
We introduce:
🔹 IMAGIREP: A controlled benchmark that fixes the imagined state and question while varying the representation (RGB, depth, normals, panorama, top-down, text, video). Different questions benefit from different representations, and the benefit persists even when the state is estimated by a world model.
🔹 GEARS: A lightweight test-time strategy that selects when to trust imagined evidence and which representation to use.
➡️ Spatial imagination is more than generating views. World models should produce representations reasoners can actually use.
🧵👇
Zaid Khan retweeted

Excited to share our work on MiRL! 🚀
💡 More training isn't always the answer — learning from the right failures matters.
Many agent failures stem from a small set of recurring misbehaviors. Rather than simply scaling up RL training, MiRL focuses on identifying and correcting these systematic errors.
🎯 By targeting where agents go wrong, we achieve stronger performance with substantially less training compute.
Great work by the team! Check out the thread below 👇

🤔 How can we efficiently train terminal agents to avoid misbehaviors?
😮 We try error-targeted learning on terminal agents and find that, with < 200 envs in TMax-15K & 35% of TMax's rollout, we can match TMax-4B full recipe.
🚨Introducing MiRL (Misbehavior-driven RL): MiRL first profiles the errors of a policy to find mistakes that recur across many environments, which we call generalizable misbehaviors. It then trains the policy with RL, starting rollouts at the steps where these misbehaviors occur and rewards a rollout only if it passes the tests and avoids the misbehavior.
Key takeaways
🔍 On Qwen3.5-4B, we find that 8 dominant misbehaviors account for 52.1% of wrong steps and appear in 75.4% of the environments.
🔥 MiRL outperforms TMax-4B, the released checkpoint trained with the full TMax recipe on Terminal-Bench Lite (51.8% vs. 47.4%) and matches it on Terminal-Bench 2.1 (21.3% vs. 20.6%), while using 35% of its rollouts and 189 selected training envs.
🧵👇 [1/9]

Error-targeted learning is a direction I'm excited about for agentic post-training. The idea is to find mistakes an agent is making, and focus compute on training away those mistakes. It's efficient + tells you how training is changing your agent.
We show how to make it work for a strong, recent terminal agent policy (Qwen3.5-based), and show training away repeated misbehaviors is a viable path to capability improvement.
One of the reasons I like this paradigm so much is that it seems important for democratizing agentic post-training. Doing thousands of rollouts on long-horizon tasks in hundreds of environments is expensive, and it's hard to predict what the outcome of that training will be. In contrast, error-targeted learning lets you decide what errors you want to fix, and then you can watch those errors go away during training. It's very legible and accessible. 🧵👇
🤔 How can we efficiently train terminal agents to avoid misbehaviors?
😮 We try error-targeted learning on terminal agents and find that, with < 200 envs in TMax-15K & 35% of TMax's rollout, we can match TMax-4B full recipe.
🚨Introducing MiRL (Misbehavior-driven RL): MiRL first profiles the errors of a policy to find mistakes that recur across many environments, which we call generalizable misbehaviors. It then trains the policy with RL, starting rollouts at the steps where these misbehaviors occur and rewards a rollout only if it passes the tests and avoids the misbehavior.
Key takeaways
🔍 On Qwen3.5-4B, we find that 8 dominant misbehaviors account for 52.1% of wrong steps and appear in 75.4% of the environments.
🔥 MiRL outperforms TMax-4B, the released checkpoint trained with the full TMax recipe on Terminal-Bench Lite (51.8% vs. 47.4%) and matches it on Terminal-Bench 2.1 (21.3% vs. 20.6%), while using 35% of its rollouts and 189 selected training envs.
🧵👇 [1/9]
Zaid Khan retweeted
🚨 Terminal agents often fail because of a few recurring mistakes. Can we fix these misbehaviors directly, rather than wasting RL compute on entire trajectories?
💡 Sometimes, learning where and what to fix matters more than training on more data!
We propose ✨MiRL (Misbehavior-driven RL)✨ which identifies generalizable agent errors and trains directly from the steps where they occur!
We find that:
1️⃣ Just 8 misbehaviors account for 52.1% of wrong steps across terminal tasks.
2️⃣ Targeted RL from misbehavior prefixes improves generalization while avoiding redundant rollouts.
3️⃣ With only 189 training envs and 35% of the rollouts, MiRL outperforms TMax-4B on Terminal-Bench Lite and matches it on Terminal-Bench 2.1!
More details in the thread! 🧵👇
🤔 How can we efficiently train terminal agents to avoid misbehaviors?
😮 We try error-targeted learning on terminal agents and find that, with < 200 envs in TMax-15K & 35% of TMax's rollout, we can match TMax-4B full recipe.
🚨Introducing MiRL (Misbehavior-driven RL): MiRL first profiles the errors of a policy to find mistakes that recur across many environments, which we call generalizable misbehaviors. It then trains the policy with RL, starting rollouts at the steps where these misbehaviors occur and rewards a rollout only if it passes the tests and avoids the misbehavior.
Key takeaways
🔍 On Qwen3.5-4B, we find that 8 dominant misbehaviors account for 52.1% of wrong steps and appear in 75.4% of the environments.
🔥 MiRL outperforms TMax-4B, the released checkpoint trained with the full TMax recipe on Terminal-Bench Lite (51.8% vs. 47.4%) and matches it on Terminal-Bench 2.1 (21.3% vs. 20.6%), while using 35% of its rollouts and 189 selected training envs.
🧵👇 [1/9]
Zaid Khan retweeted
MiRL
Error-Targeted Reinforcement Learning for Correcting Terminal Agent Misbehaviors
paper: huggingface.co/papers/2610.3…

Zaid Khan retweeted

🤔 How can we efficiently train terminal agents to avoid misbehaviors?
😮 We try error-targeted learning on terminal agents and find that, with < 200 envs in TMax-15K & 35% of TMax's rollout, we can match TMax-4B full recipe.
🚨Introducing MiRL (Misbehavior-driven RL): MiRL first profiles the errors of a policy to find mistakes that recur across many environments, which we call generalizable misbehaviors. It then trains the policy with RL, starting rollouts at the steps where these misbehaviors occur and rewards a rollout only if it passes the tests and avoids the misbehavior.
Key takeaways
🔍 On Qwen3.5-4B, we find that 8 dominant misbehaviors account for 52.1% of wrong steps and appear in 75.4% of the environments.
🔥 MiRL outperforms TMax-4B, the released checkpoint trained with the full TMax recipe on Terminal-Bench Lite (51.8% vs. 47.4%) and matches it on Terminal-Bench 2.1 (21.3% vs. 20.6%), while using 35% of its rollouts and 189 selected training envs.
🧵👇 [1/9]
Zaid Khan retweeted
Unfortunately I couldn't make it to #EMNLP2026 but do check out the following work at the conference, covering:
- pragmatics as a self-taught reasoning task
- faithful CoT via multi-agent speaker-listener training
- grounding CUAs to history/vision
- early exiting for report generation
- tracing errors in deep research
- trade-offs between debugging and regenerating

Zaid Khan retweeted
👋 Looking forward to attending #EMNLP2026 where I will be giving an industry keynote on the hard, imminent AI challenges of trust, world discovery, and memory, plus an important, timely discussion on re-strengthening industry-academia collaborations!
We're also hiring at all levels: phd, postdoc, faculty! Feel free to ping if you want to meet up to discuss research, hiring, life 🙂

We're looking forward to the Industry Track at #EMNLP2026! Two keynotes:
• Mohit Bansal (UNC Chapel Hill): Agentic Challenges & Industry–academia Collaboration (Sun, 16:30)
• Verena Rieser (Google DeepMind): Constitutional Alignment (Mon, 9:30)
2026.emnlp.org/program/indus…

Zaid Khan retweeted
Theory-of-mind lets agents coordinate by modeling others’ thoughts/beliefs, but requires the agent to hold many hypotheses at once. ToM2Vec teaches agents to produce continuous ToM thought vectors which capture multiple hypotheses, improving across 5 multi-agent tasks and transferring to unseen partners, including frontier-model partners.
LLM agents often focus on their own plans without accounting for their partners’ next steps, leading to redundant or conflicting actions. ToM2Vec addresses this by improving agents’ theories-of-mind, training agents to predict a continuous, abstract representation of a partner’s reasoning. These continuous ToM tokens then guide the agent’s own reasoning and actions.
At test-time, the main agent generates a series of latent thought vectors representing its estimate of another agent’s reasoning/thoughts.
ToM2Vec improves coordination without any task rewards, across cooperative, competitive, and mixed-motive settings, including Overcooked, negotiation, Decrypto, Hanabi, and Collab Escape/Capture.
Crucially, agents trained with ToM2Vec generalize to unseen partner model families, including GPT-5.4 and Gemma-4.
🧵👇

Zaid Khan retweeted

We're looking forward to the Industry Track at #EMNLP2026! Two keynotes:
• Mohit Bansal (UNC Chapel Hill): Agentic Challenges & Industry–academia Collaboration (Sun, 16:30)
• Verena Rieser (Google DeepMind): Constitutional Alignment (Mon, 9:30)
2026.emnlp.org/program/indus…