

Modern DXP for the Enterprise
- Tweets10.4K
- Following3.3K
- Followers3K
- Likes16K




ALT Warm beige checklist card titled Before Black Friday: conditions next to the price, end dates on every deal, feed updates in the promotion calendar, brief your service team.


ALT Lime card. Large text: 92% confidence. An Italian food preference from one assistant conversation, time-bound, sourced, never permanent. Target, RecSys 2026.


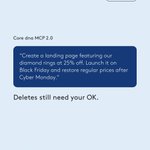
ALT Illustration of a chat message on a pale blue card: Create a landing page featuring our diamond rings at 25% off. Launch it on Black Friday and restore regular prices after Cyber Monday.


ALT Bar chart on a light card, named versus recommended in 40 ChatGPT answers. JB Hi-Fi named 21, recommended 2. Officeworks named 13, recommended 7.

ALT Brown card with a quote: Design what agents show their users by value, not by approval rate. Margaret Mitchell, Hugging Face, RecSys 2026 keynote.

ALT Illustration on a beige card: Brief, then Plan reviewed by the CTO, then Built: a new content type, a 13-step automation and a 26-step automation.


ALT Deep red card. Large text: 15 of 24 Black Friday recommendations had the wrong price. Every wrong price was too low. Example: Garmin Forerunner 265, ChatGPT said $479, store charged $797.

ALT Dark card. Large text: about 70% of experiments on YouTube’s watch page ranking model are run by an AI system. Source: YouTube at RecSys 2026.

